Overview

11 Large Language Models (LLMs)

Large language models extend the simple idea of next‑word prediction into systems that learn rich patterns across massive corpora using billions of parameters and the Transformer architecture. Built on attention, deep neural networks, and vast, carefully curated text (and sometimes code), they move far beyond n‑grams to generate coherent prose, answer questions, translate, and reason in context. The chapter builds intuition by contrasting phone‑style autocomplete with modern LLMs, then situates LLMs in the broader ML landscape, emphasizing why scale—of tokens, parameters, and data diversity and quality (including licensing and safety)—matters for generalization and capability.

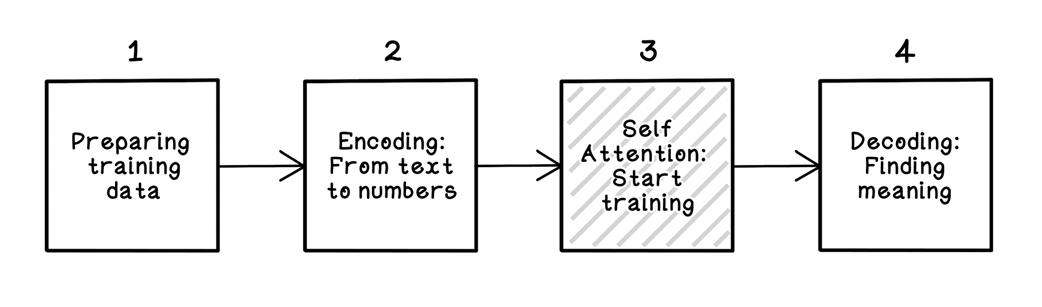
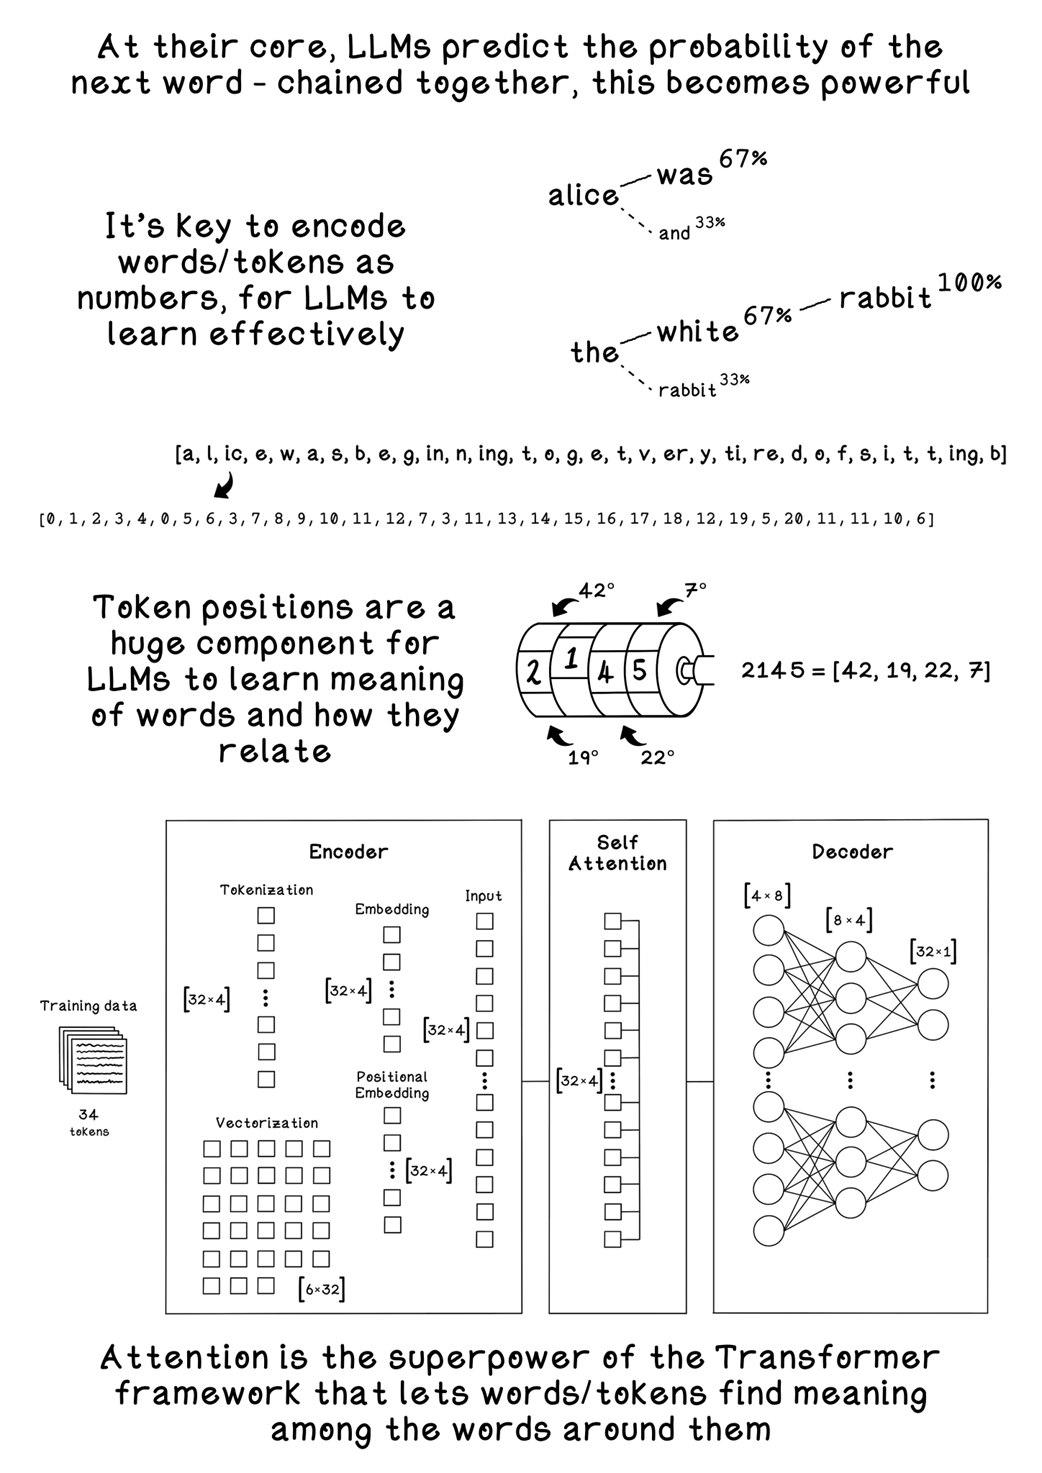
The workflow begins with preparing data: language filtering, boilerplate and near‑duplicate removal, normalization, and safety/PII scrubbing. Text is tokenized (e.g., via byte‑pair encoding) to form a vocabulary and token IDs, then streamed into fixed‑size context windows. Tokens are mapped to trainable embeddings and augmented with positional encodings so order is preserved. A Transformer block applies self‑attention (Query–Key–Value projections, scaled dot‑product, softmax weights), often across multiple heads, followed by residual connections, layer normalization, and a feed‑forward network; stacking many blocks yields progressively richer representations. Decoding projects final vectors to vocabulary logits, converts them to probabilities, and computes loss (cross‑entropy) against the true next token; gradients backpropagate through all components, and training iterates over batches and epochs, typically accelerated on GPUs.

Controlling and improving LLMs involves managing epochs and checkpoints, early stopping on validation loss to avoid overfitting, and tuning hyperparameters (learning rate, batch/context size, width/depth, attention heads). At inference time, sampling controls like temperature balance determinism and creativity; LLMs excel at zero‑shot and few‑shot in‑context learning. Beyond pretraining, Reinforcement Learning from Human Feedback aligns models with human preferences; Mixture‑of‑Experts scales capacity efficiently by routing tokens to specialized subnets; and Retrieval‑Augmented Generation grounds outputs in external, up‑to‑date sources. Together, these techniques power practical applications—content generation, information synthesis and summarization, coding assistance, and product experiences that turn unstructured inputs into organized, actionable outcomes.

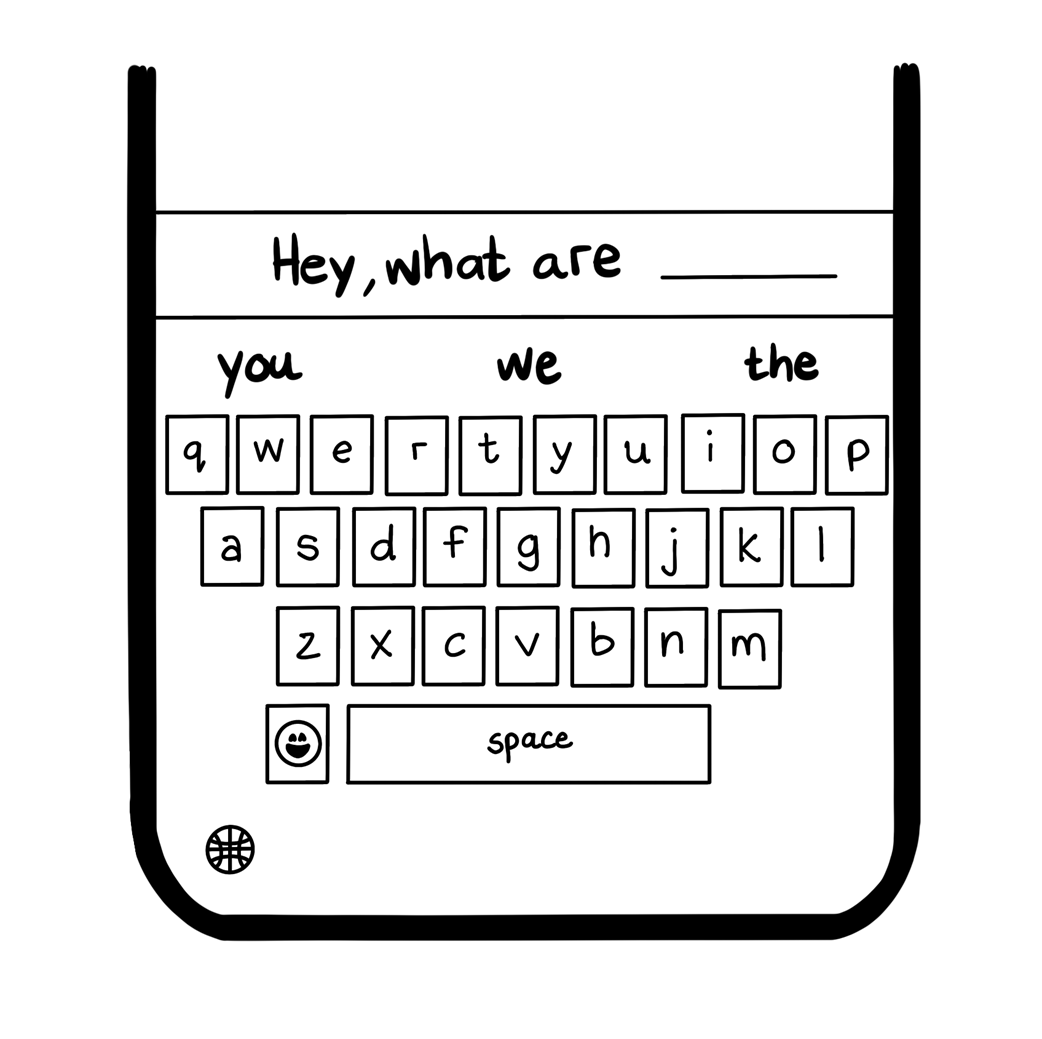
Example of autocomplete as a language model
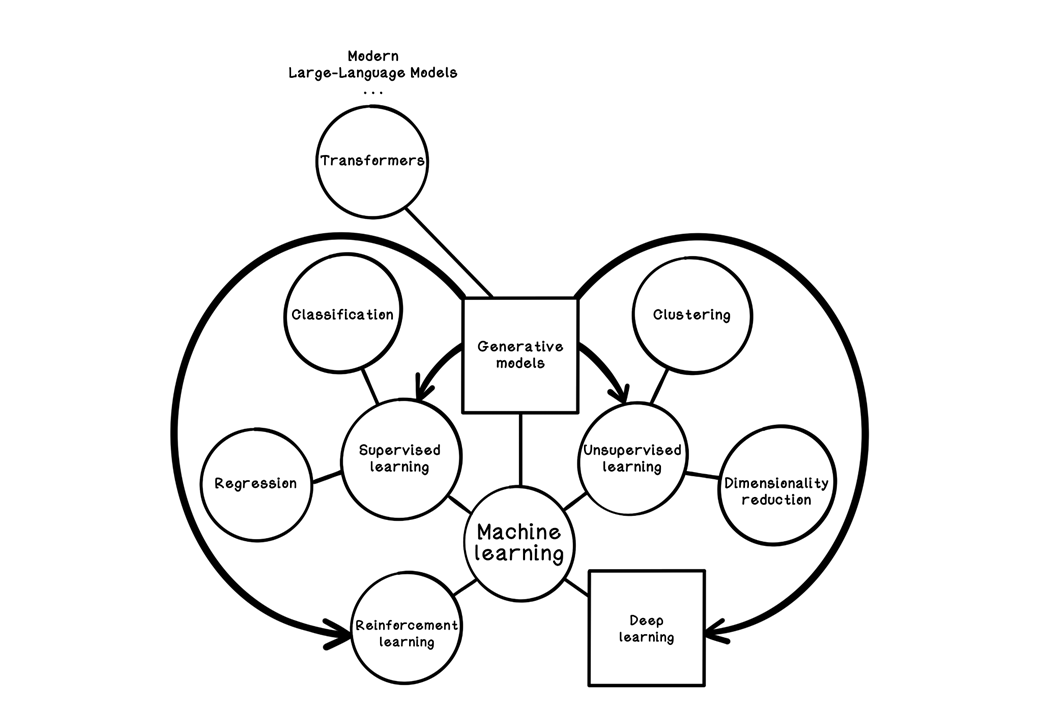
How generative models and Transformers fit into machine learning
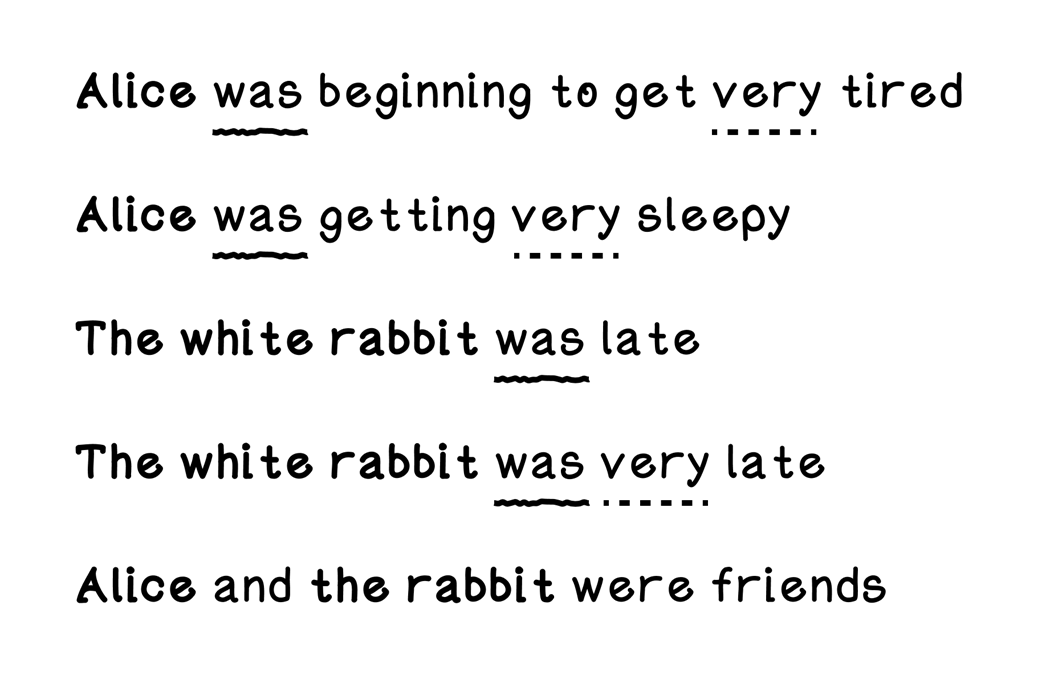
How we subconsciously identify patterns in language
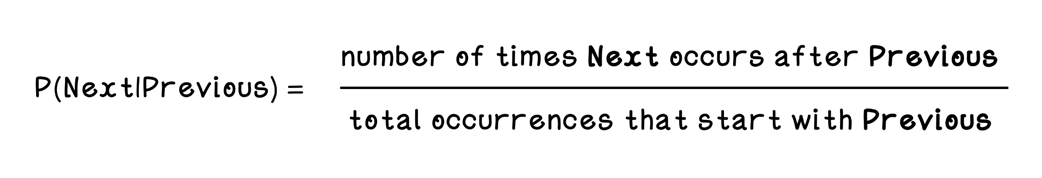
Formula for probability of a word occurring after another word
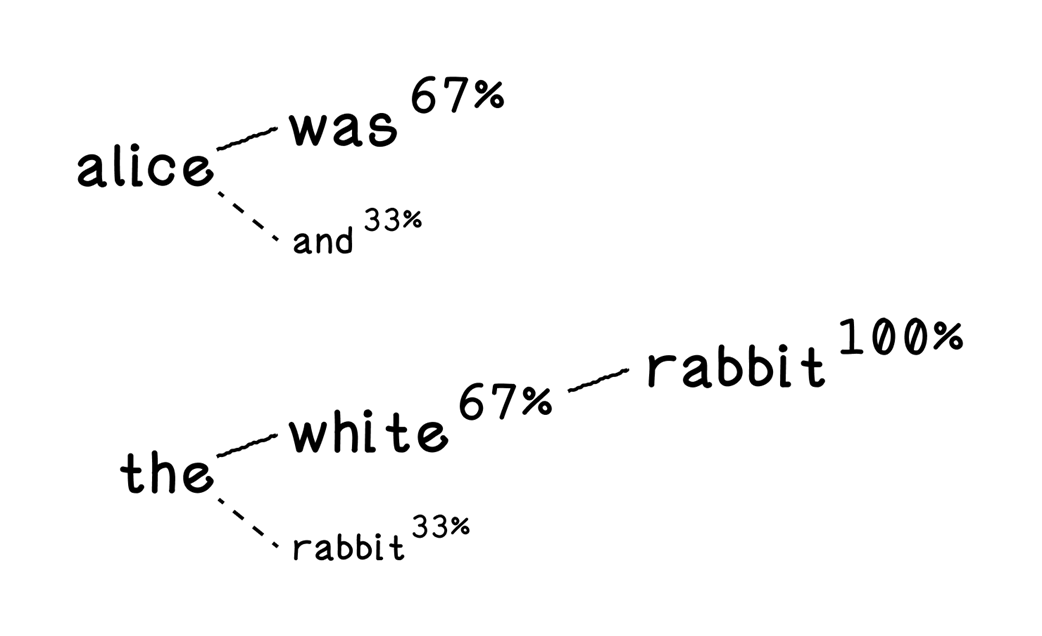
Example of the probability of words occurring
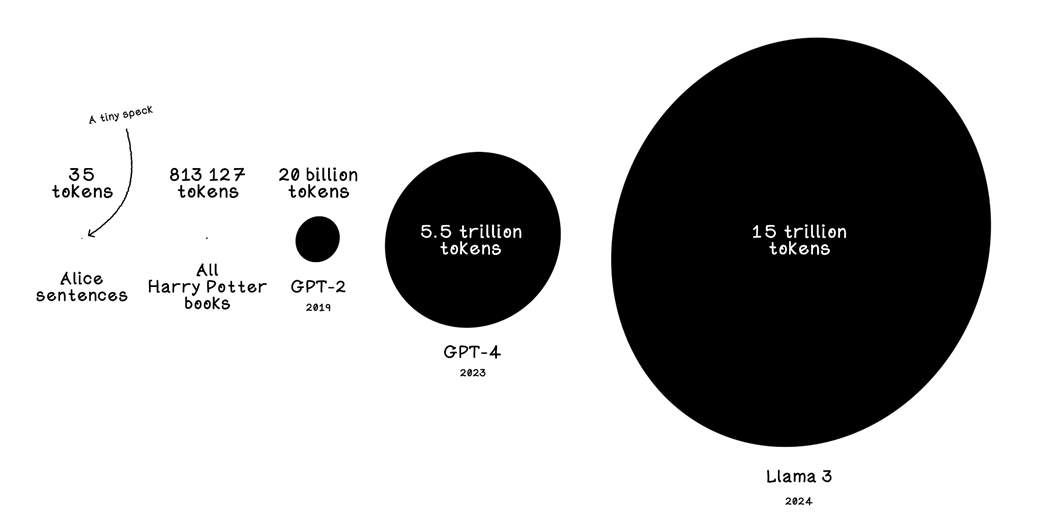
Comparison of size of training sets in popular language models
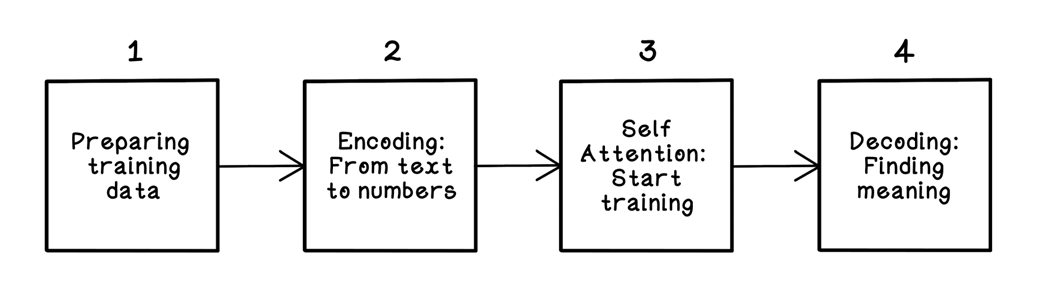
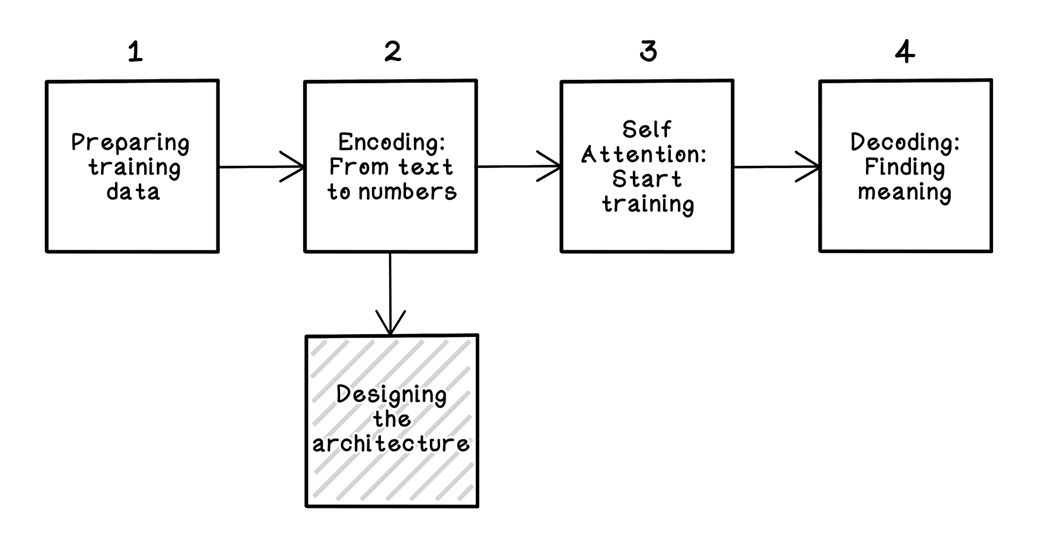
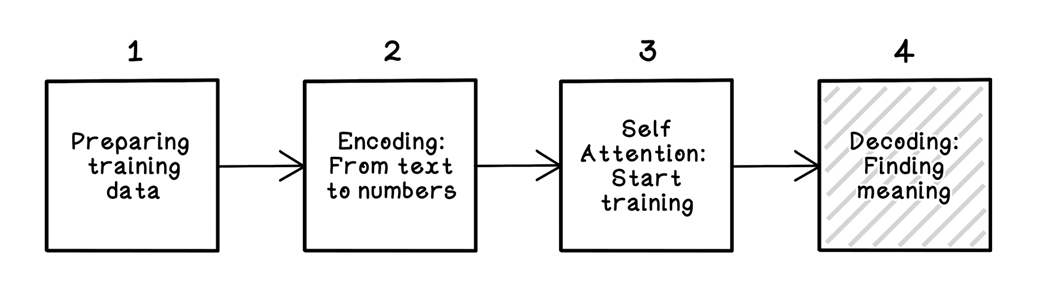
An overview of the LLM training workflow
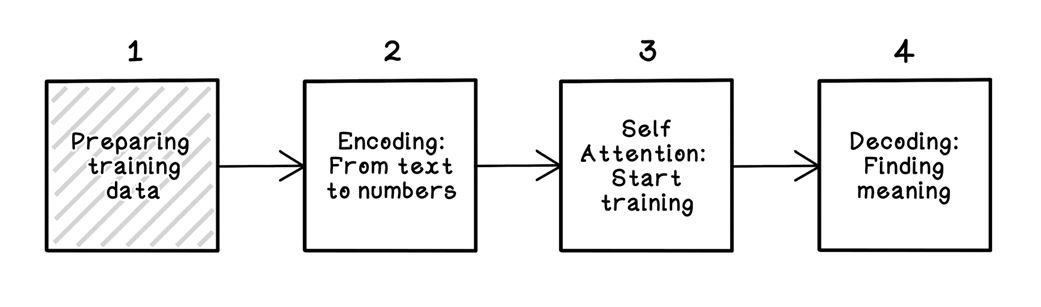
Preparing training data step in the LLM training workflow
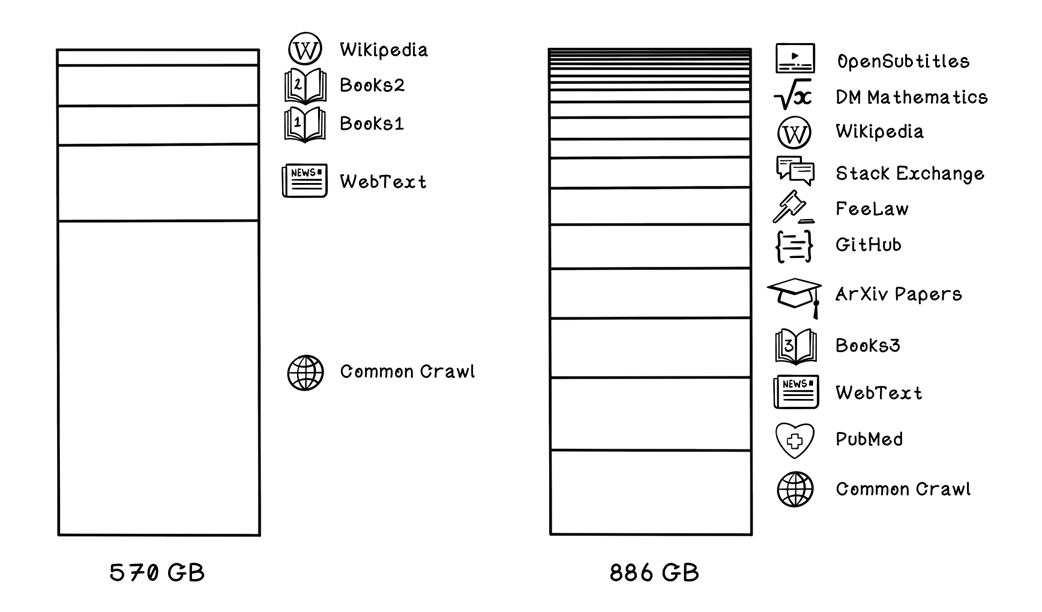
Sample training datasets and their domain composition
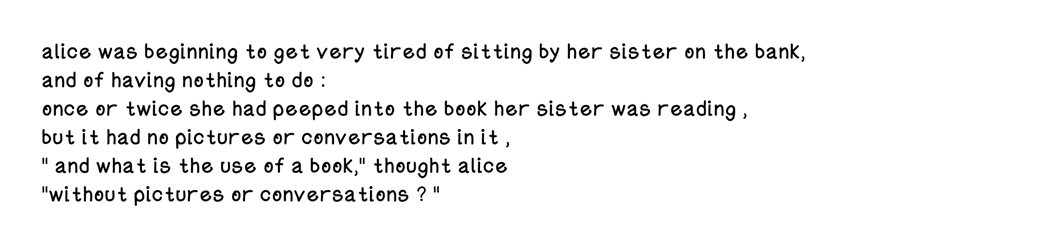
Excerpt of training data from Alice’s Adventures in Wonderland
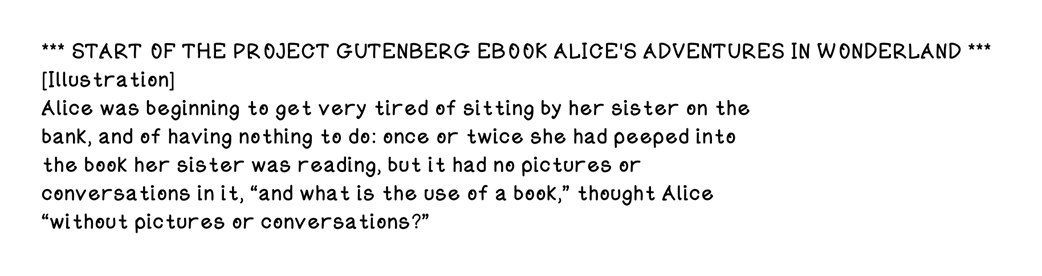
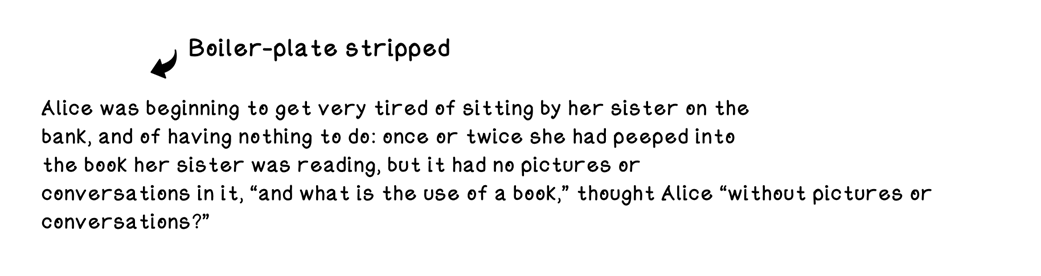
Training data with boiler-plate stipped
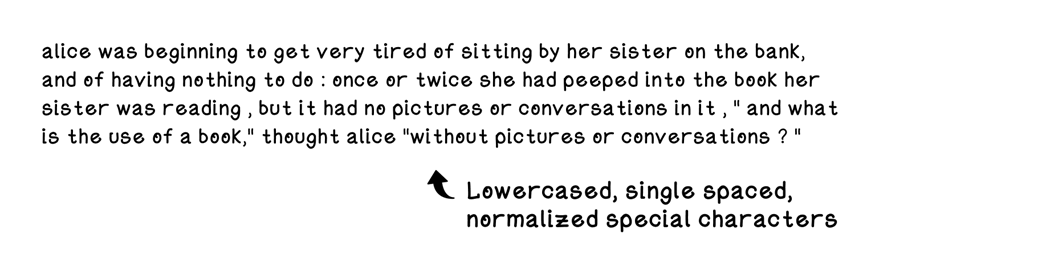
Training data normalized
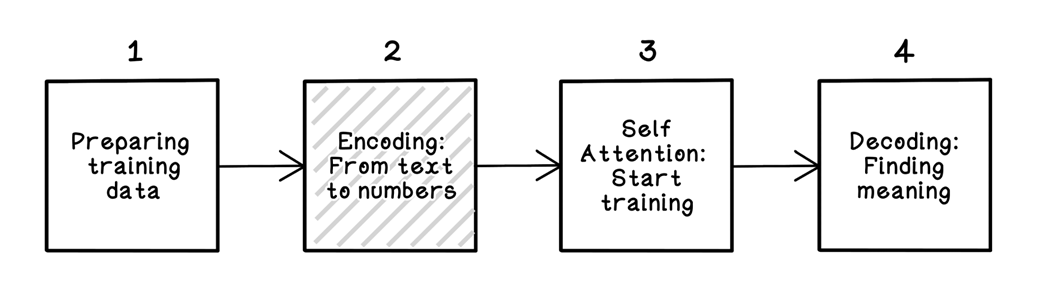
Encoding step in the LLM training workflow
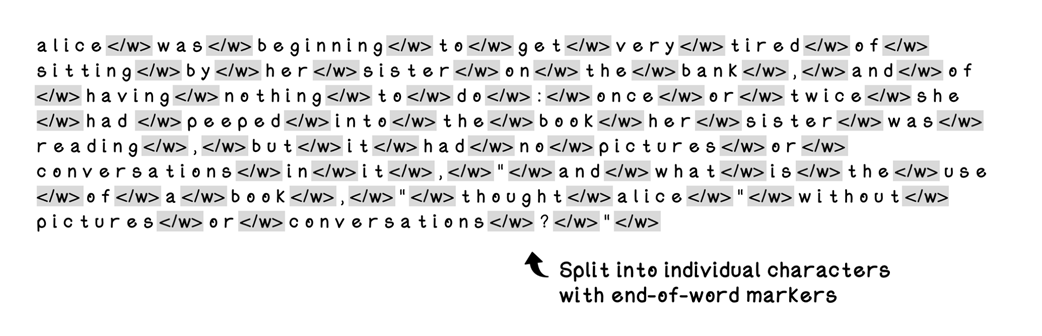
Training data split into characters with end-of-word markers
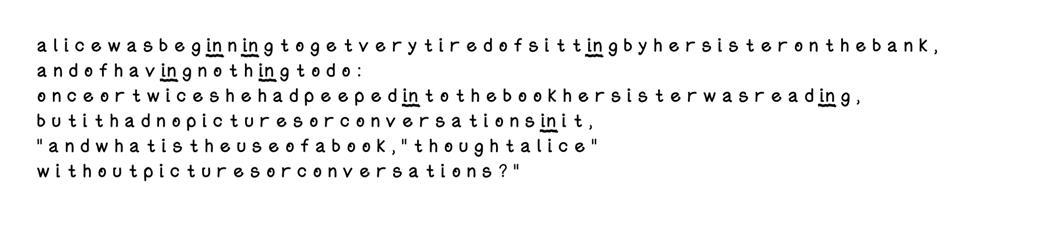
Training data after one iteration of merging with BPE
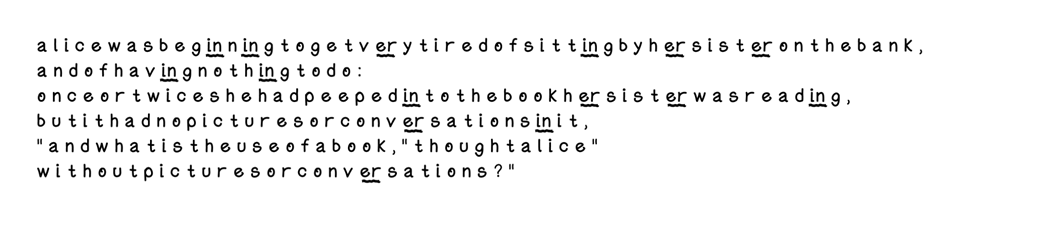
Training data after two iterations of merging with BPE
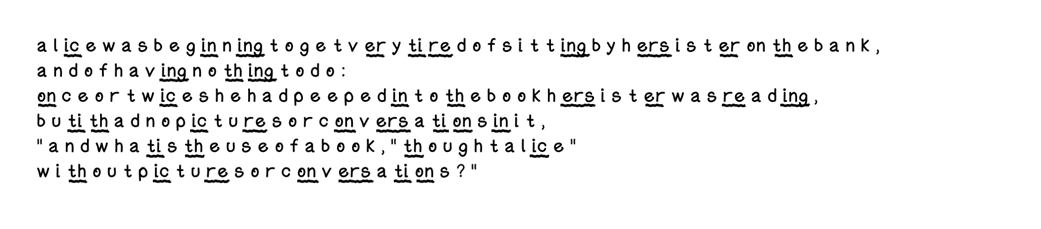
Training data after three iterations of merging with BPE
Original training data
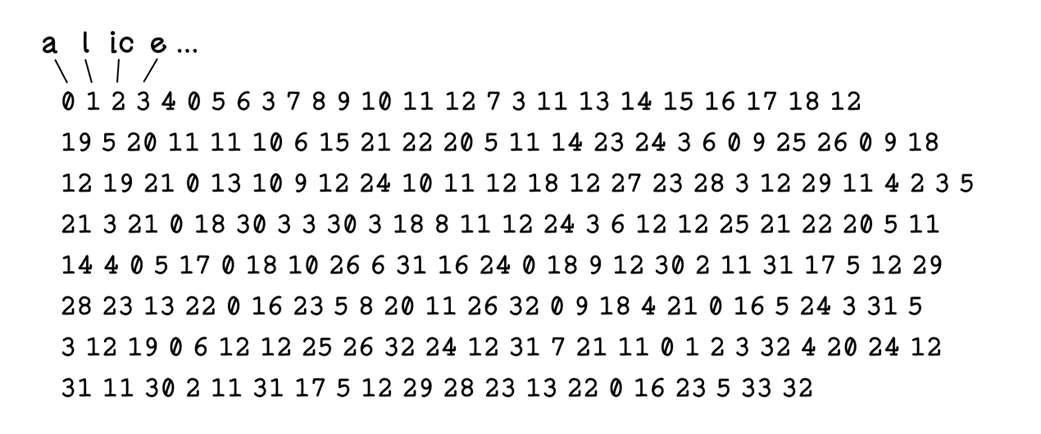
Tokenized training data as a token stream
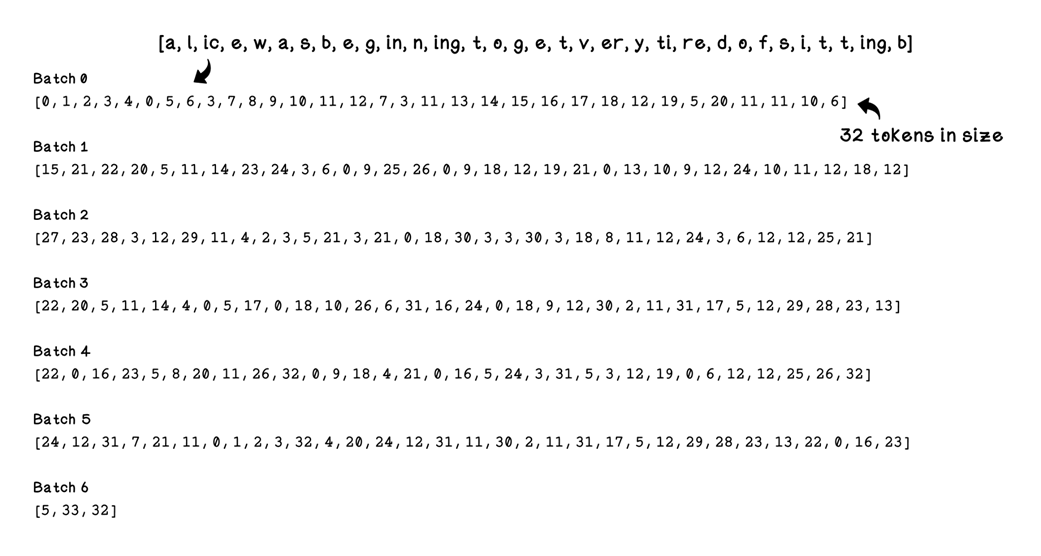
Tokenized training data as training batches
Designing the architecture step in the LLM training workflow
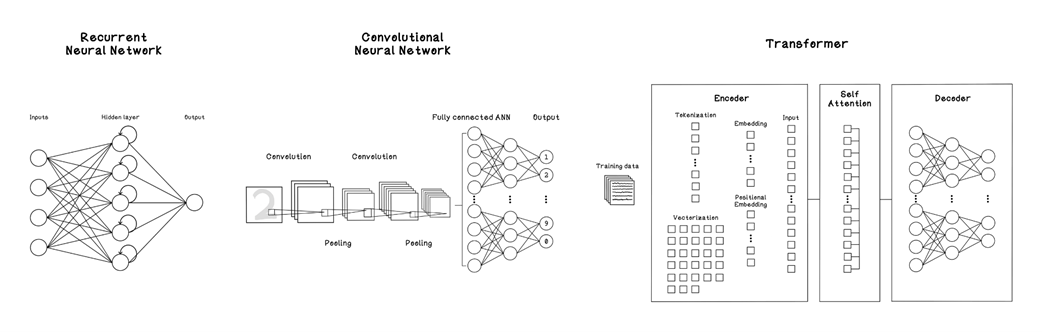
Comparison of different ANN architectures aimed at training LLMs
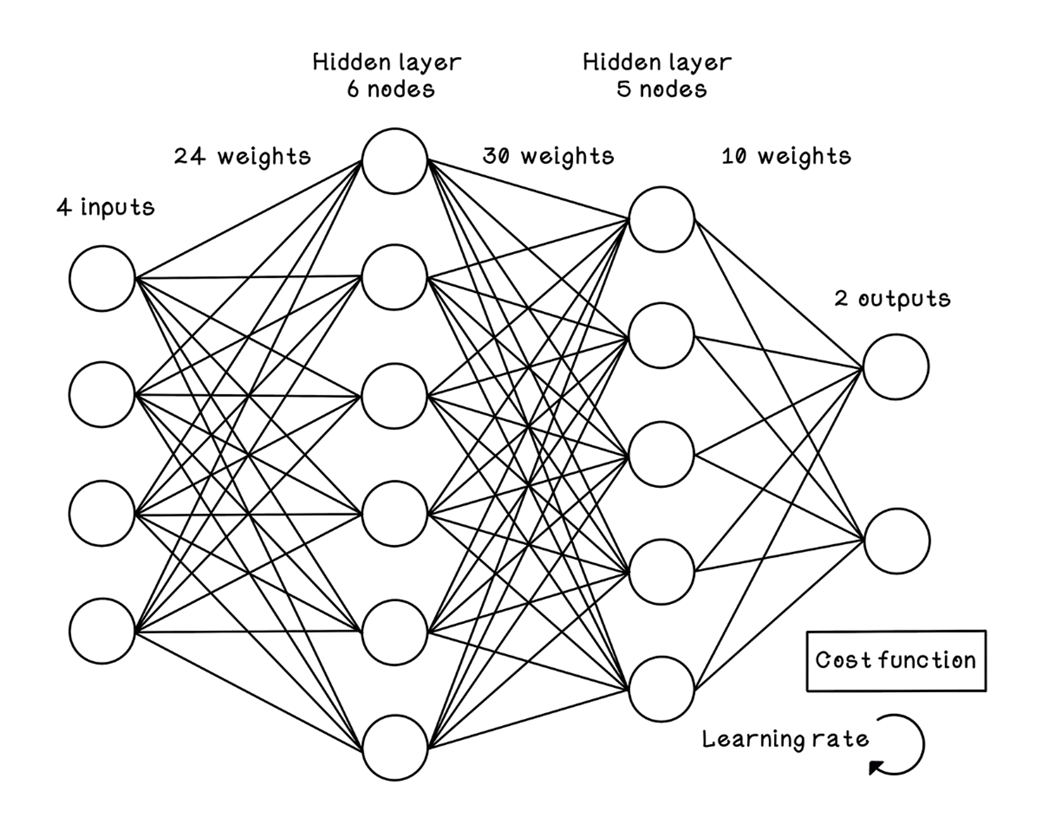
The fundamental composition of an artificial neural network
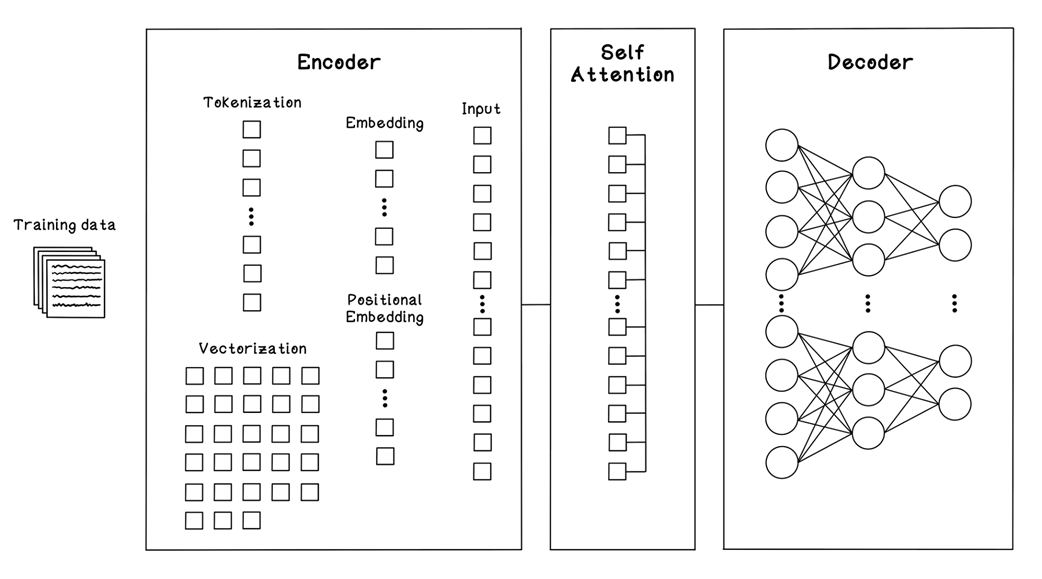
A simplistic overview of the Transformer framework
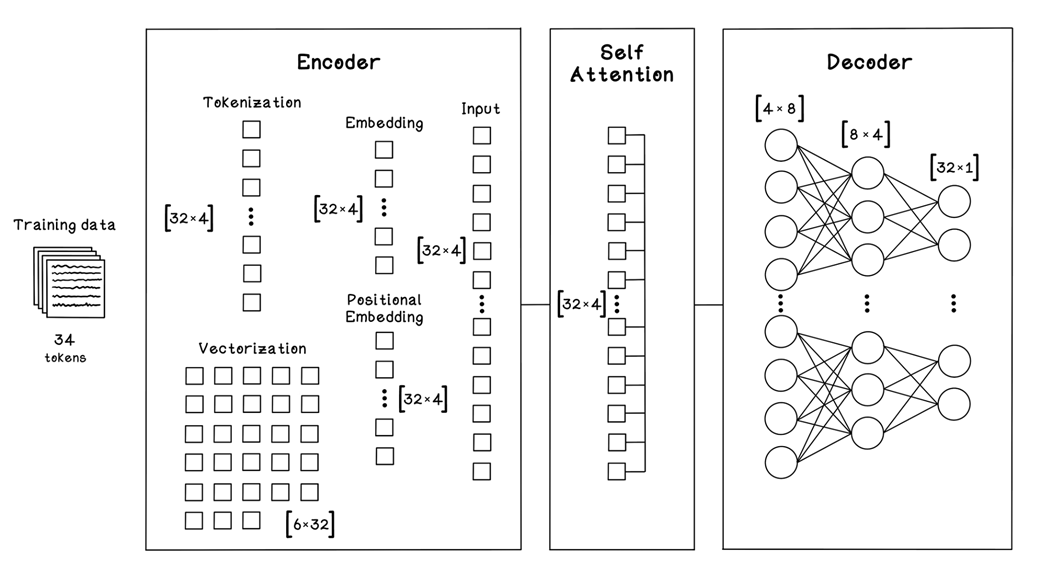
The data shapes for the different components in our Transformer framework
Continuation of the encoding step in the LLM training workflow
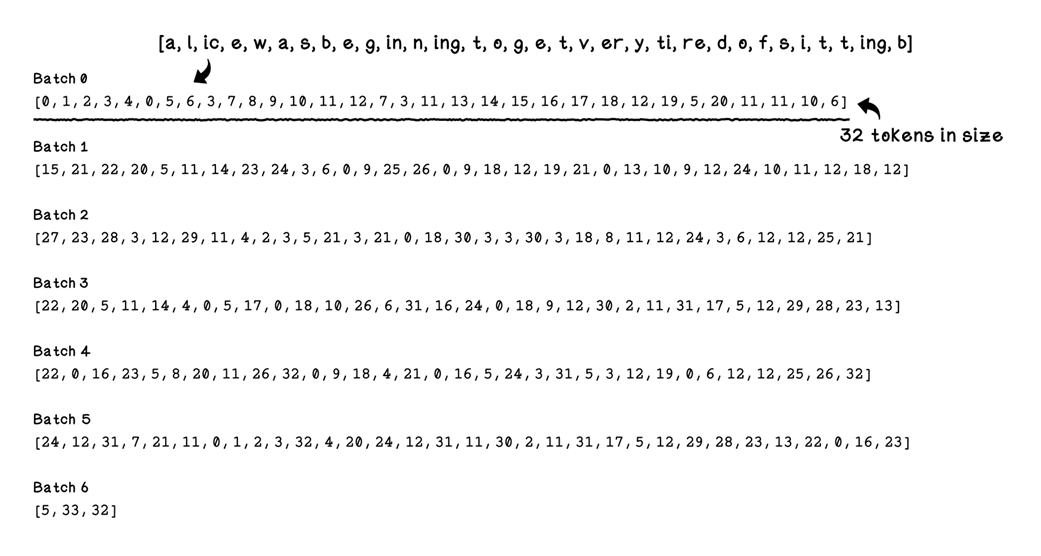
Sampling the first batch of tokens from the training data
A view of how the vocabulary size and width dimensions shape the embedding
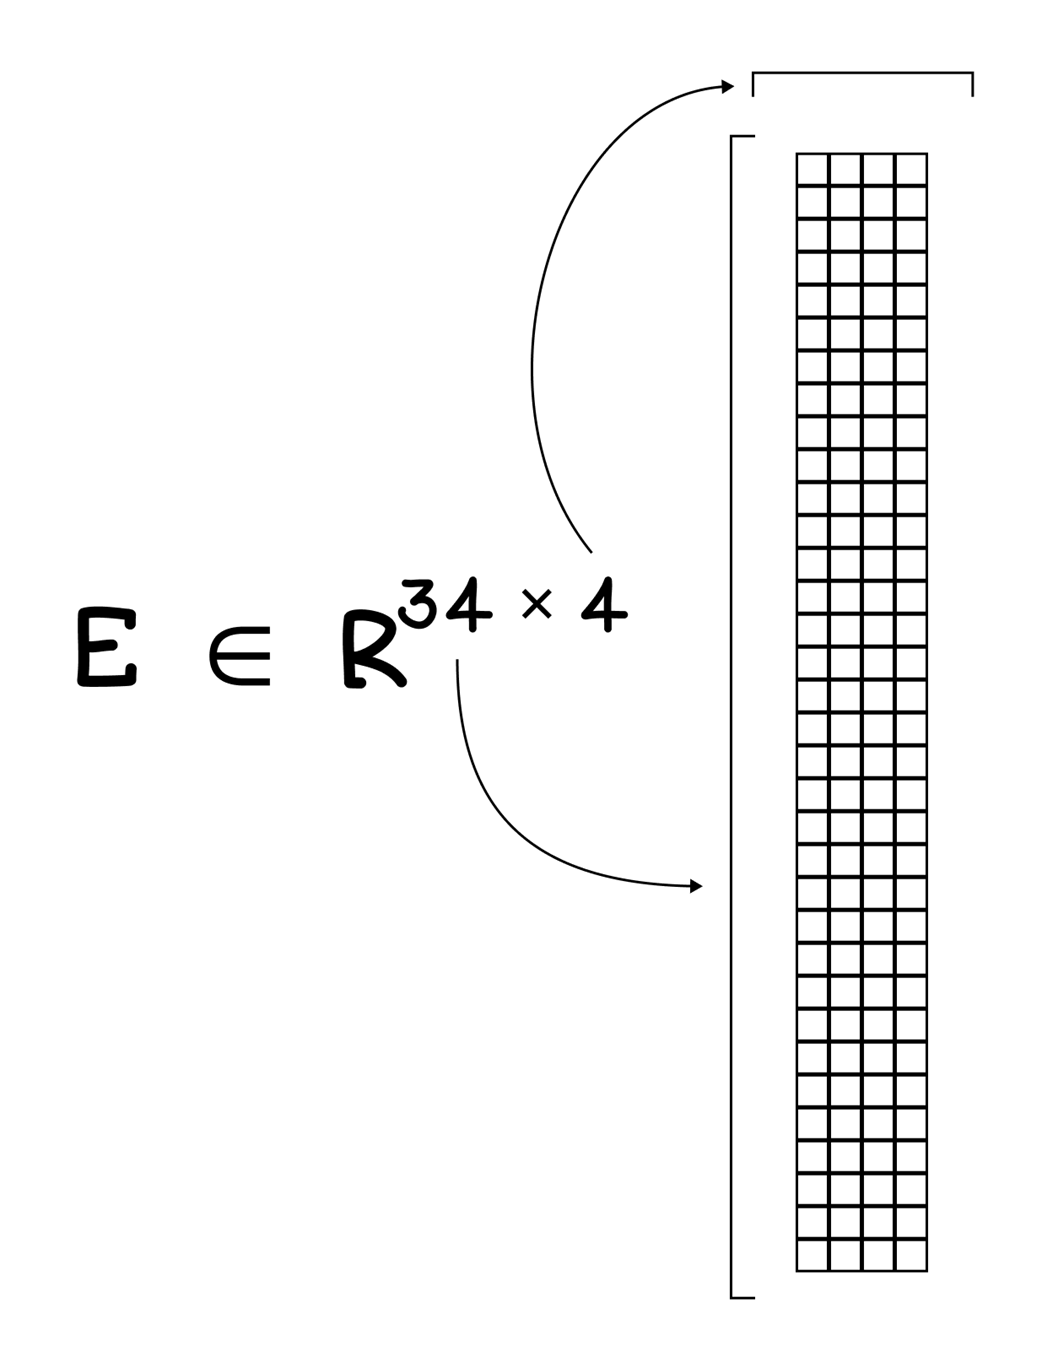
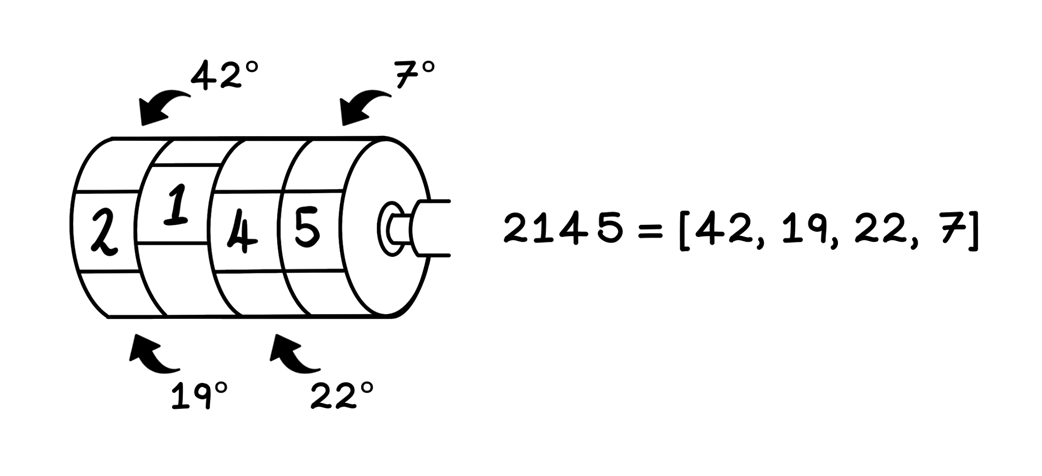
An odometer analogy for how sinusoidal positional encoding works
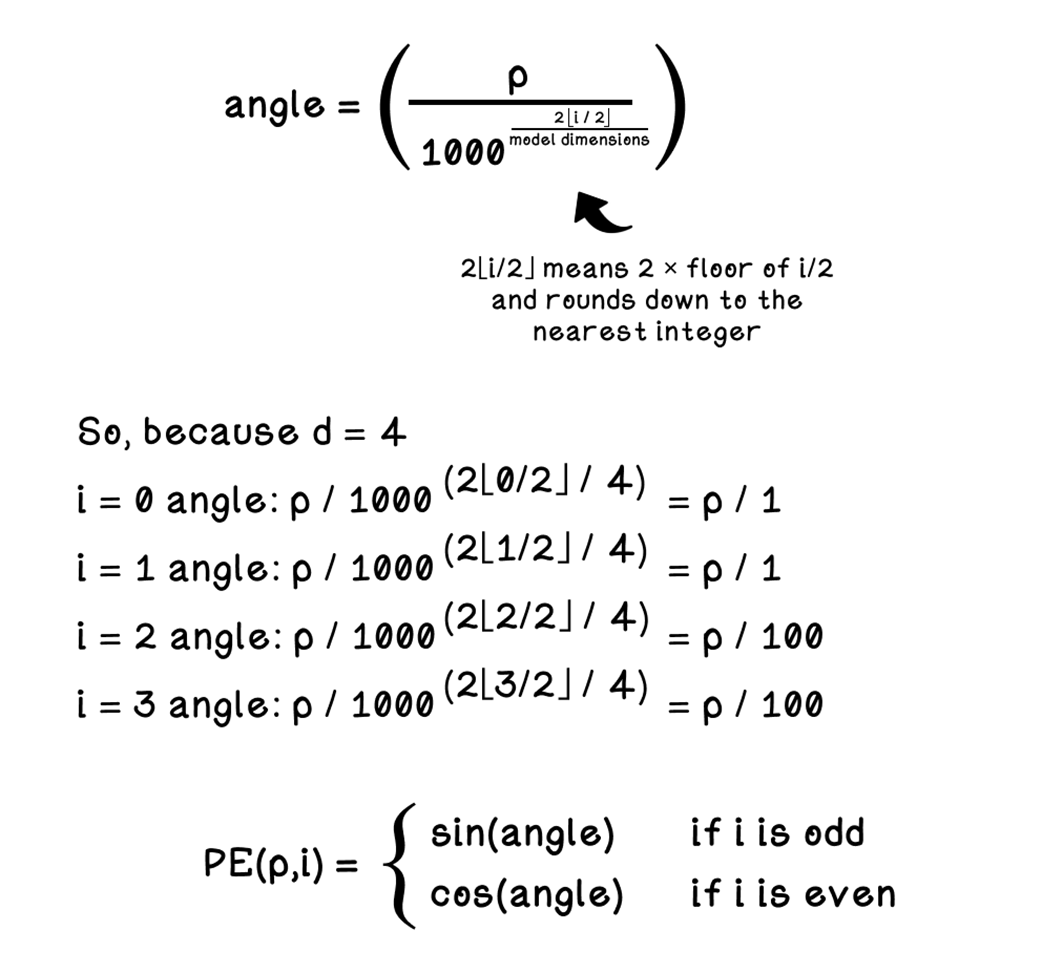
A breakdown of the calculations involved in sinusoidal encoding
A view of the embedding combination step in the encoding stage
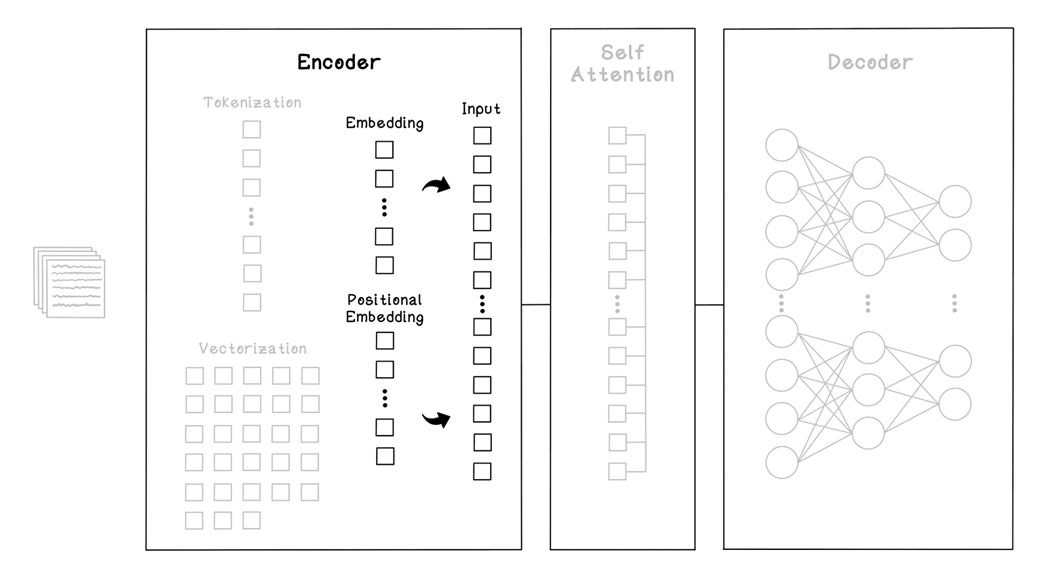
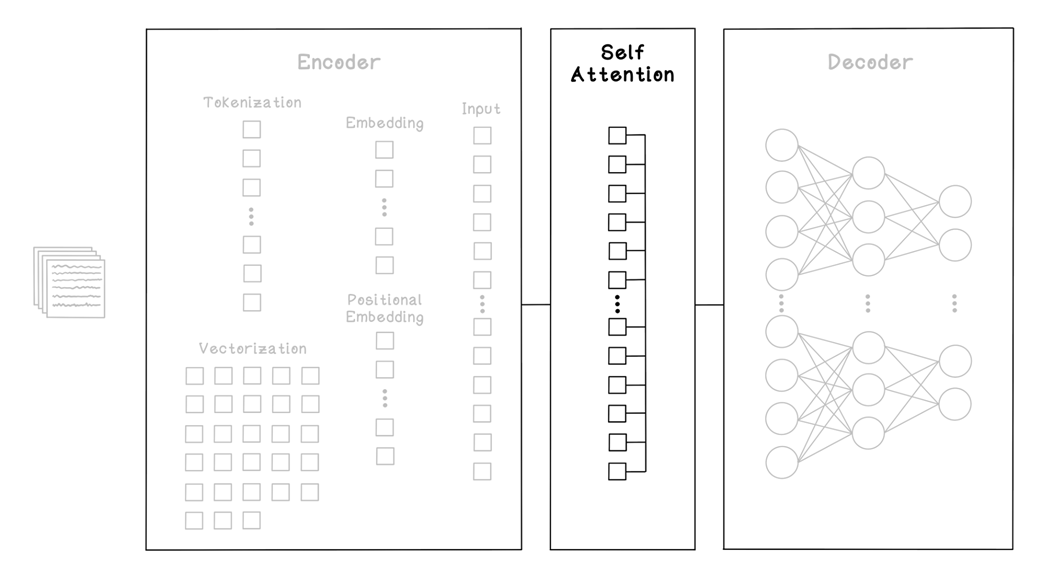
Where self-attention fits into the Transformer framework
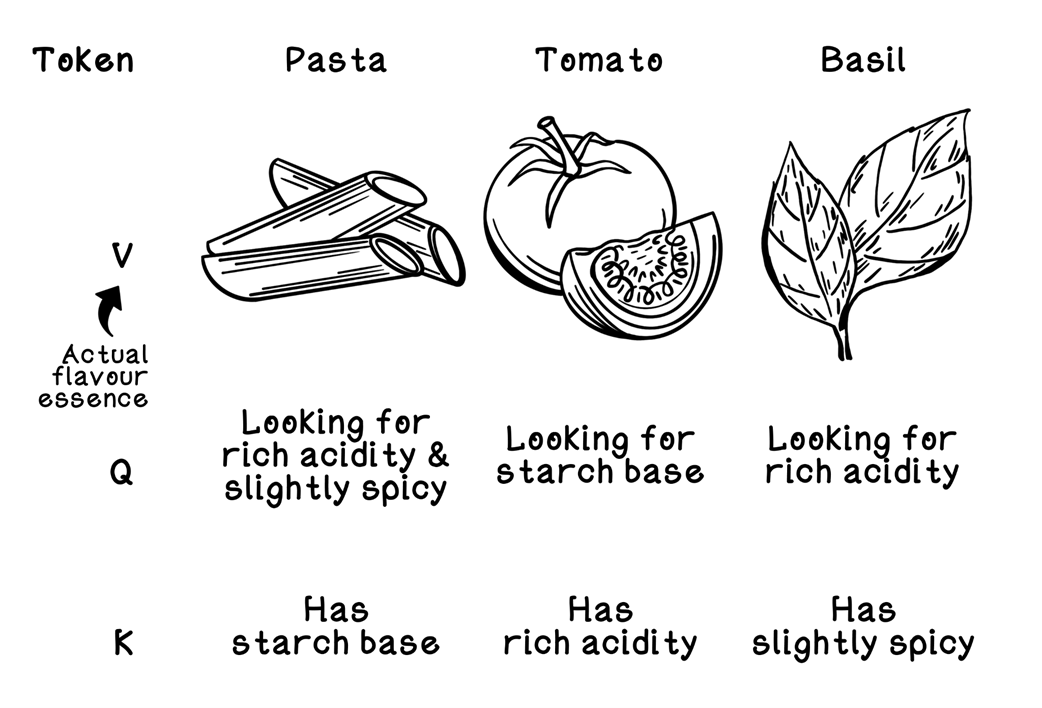
An analogy of the purposes of Query, Key, and Value
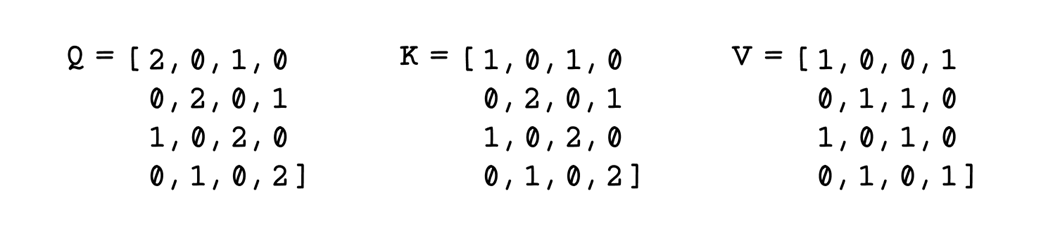
Initialization of the values for Queries, Keys, and Values
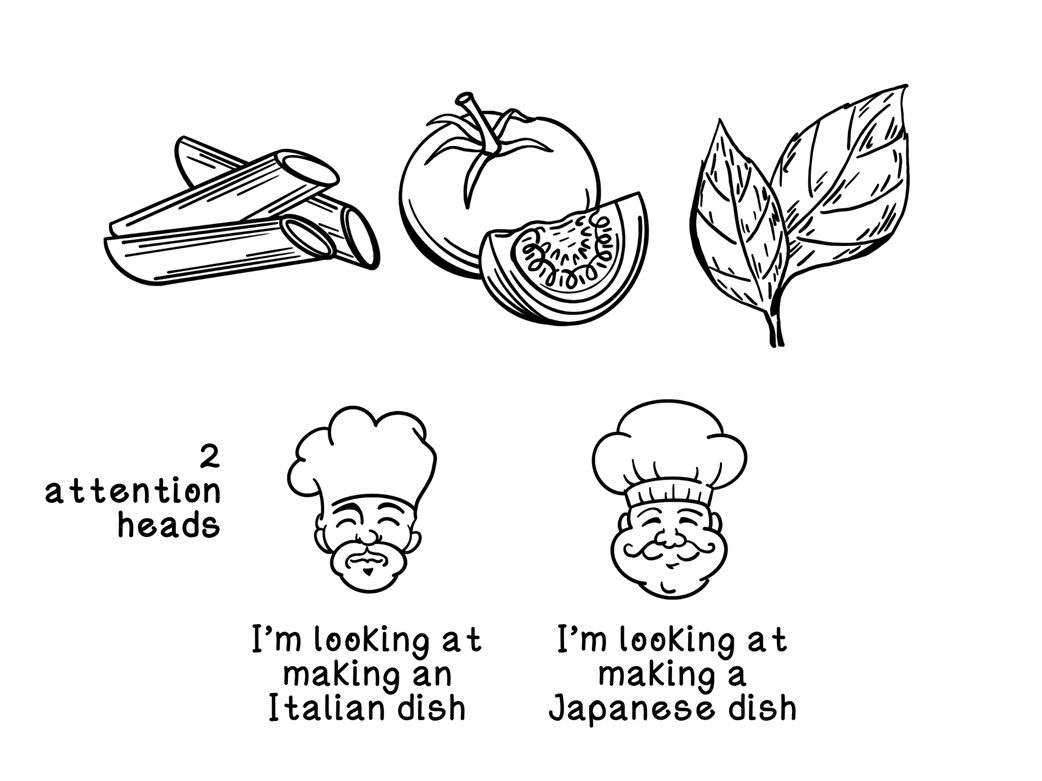
An analogy of how self-attention works
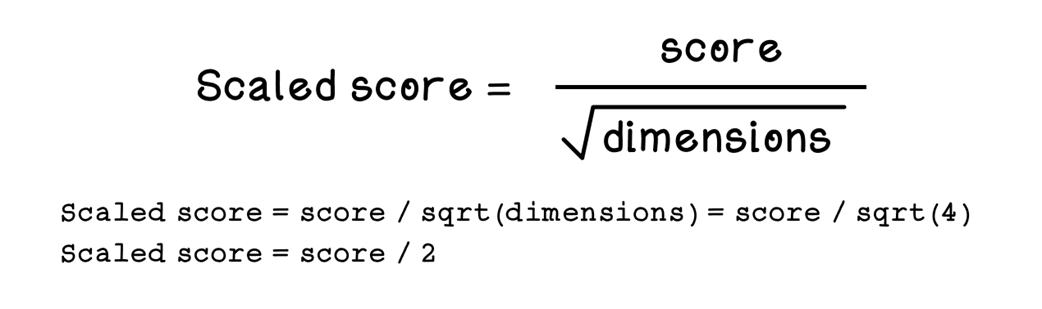
The formula for scaling scores given the score and dimensions
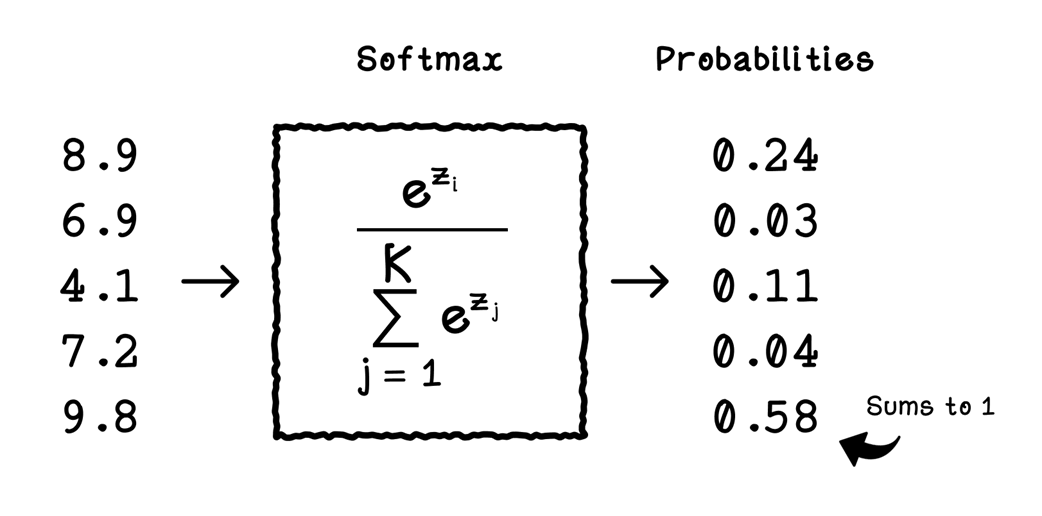
How softmax scales scores to probabilities
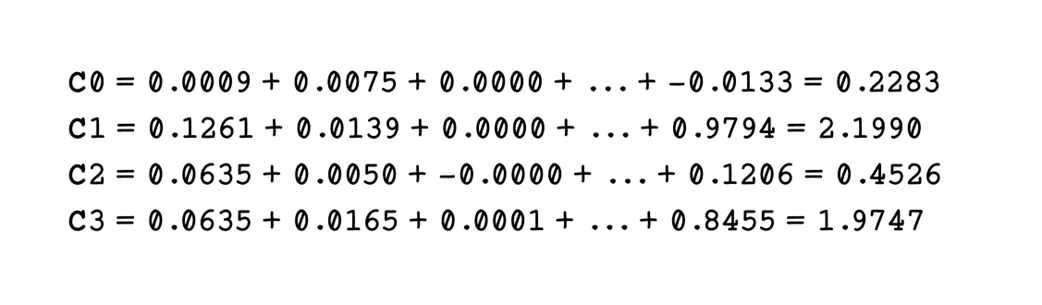
A subset of the context vector calculations
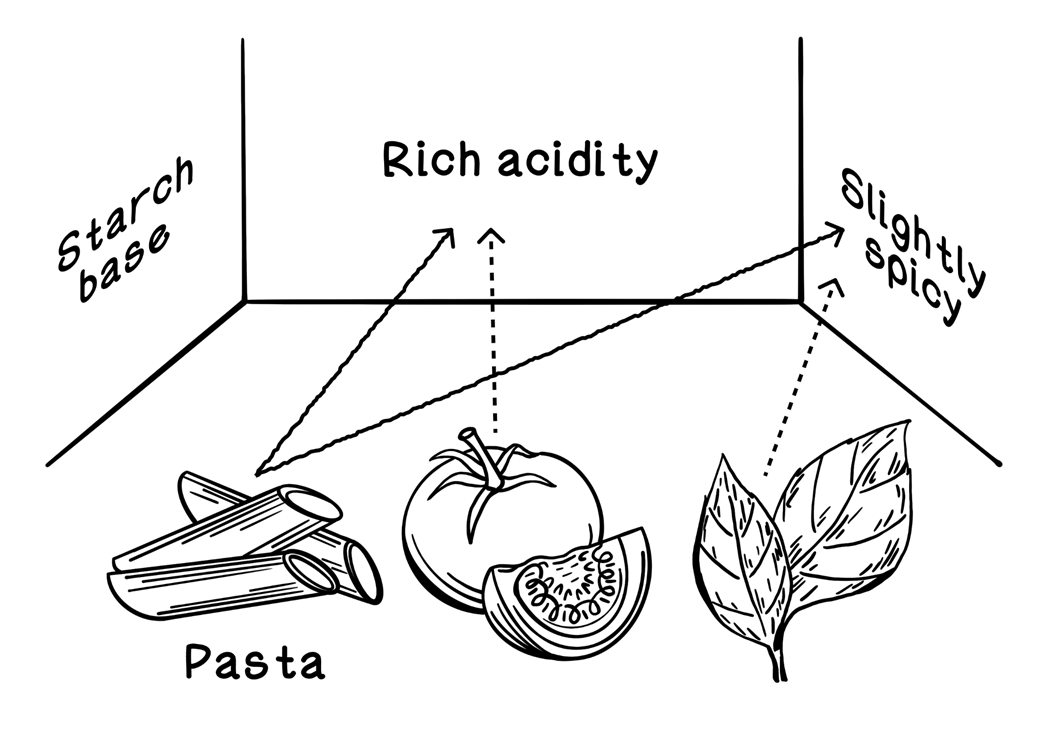
An analogy of the usefulness of multiple attention heads
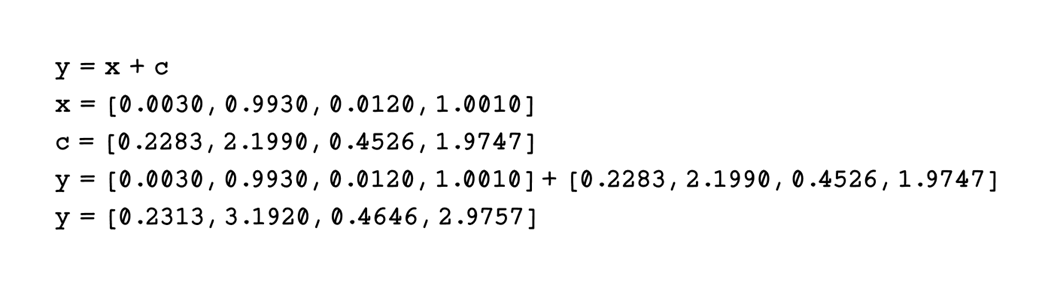
Calculations for the residual connection
The formula for layer normalization
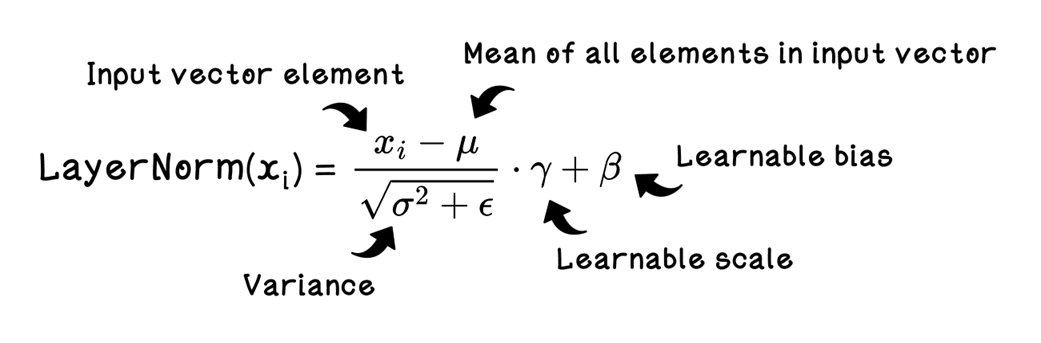
The decoding step in the LLM training workflow
The architecture of the feed-forward network to output token probabilities
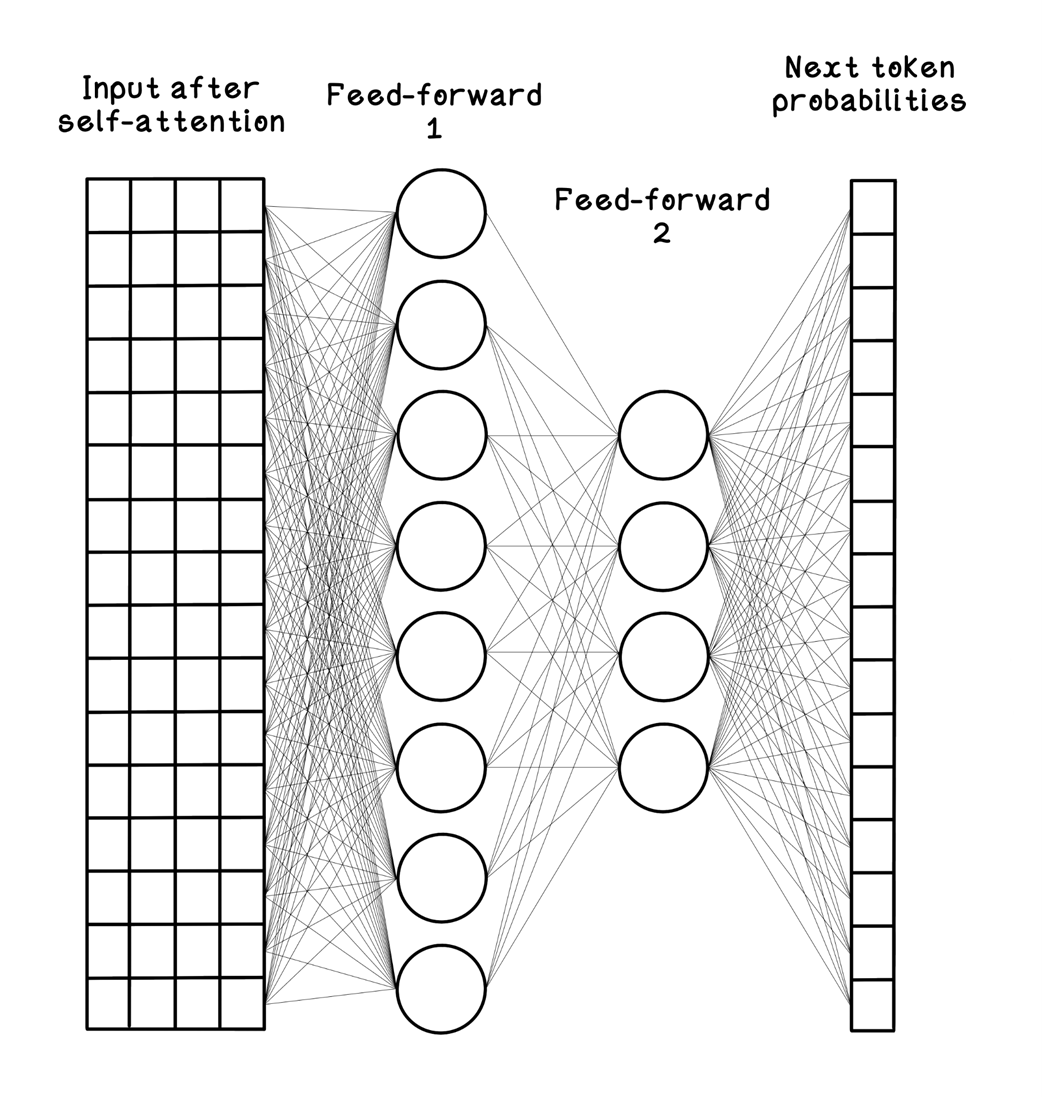
Calculations for feed-forward outputs
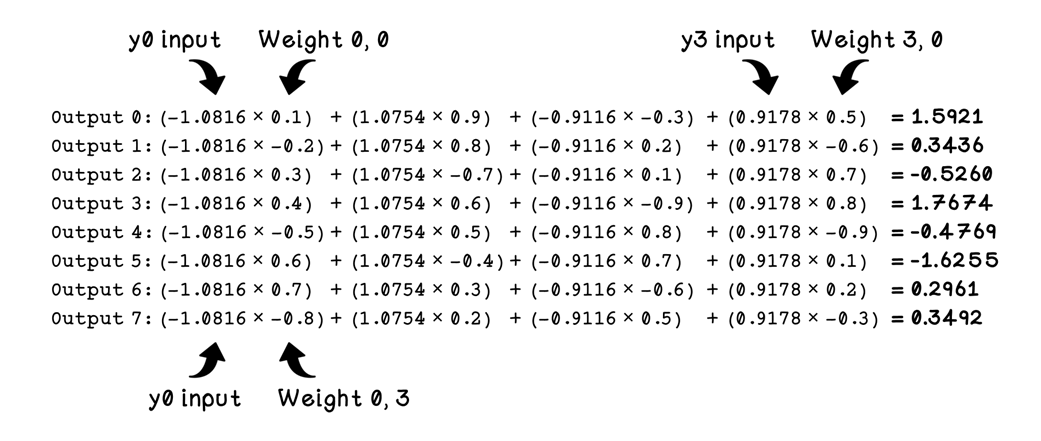
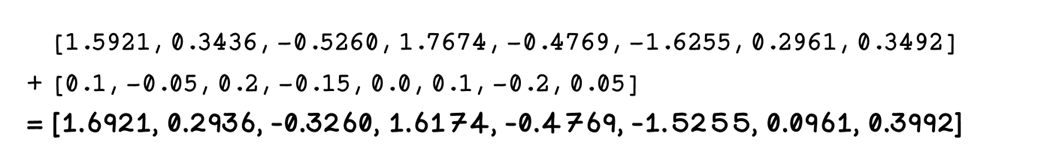
Calculations for adding bias to the output
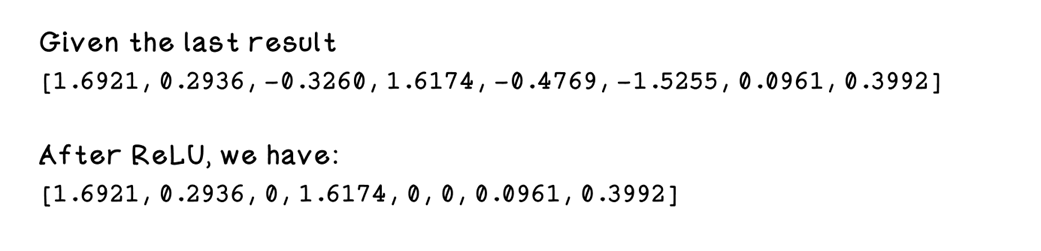
Calculations for applying the ReLU activation function
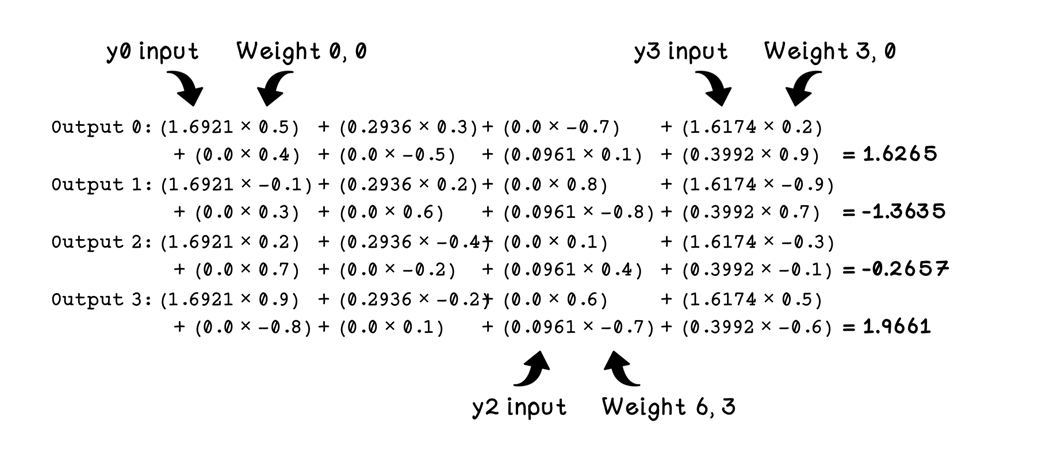
Calculations for the project-down layer output
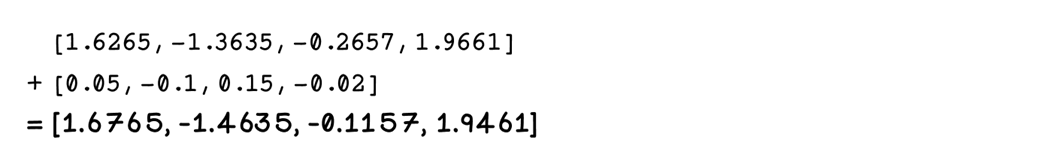
Calculations for adding bias to the output of the project-down layer
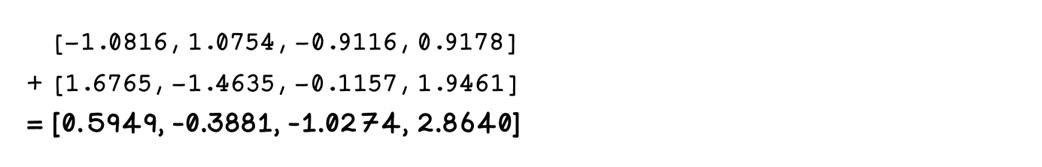
Calculations for adding the residual
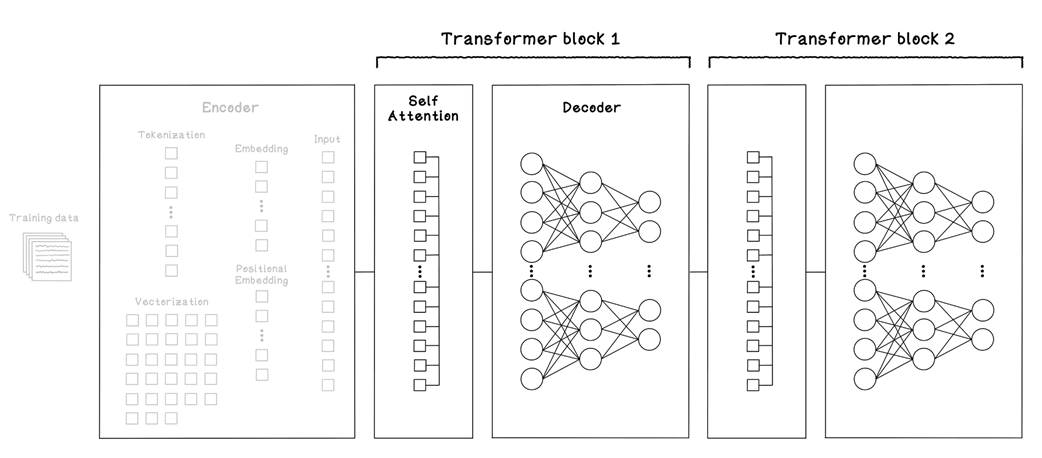
How multiple transformer blocks are stacked
Calculations for logits for tokens
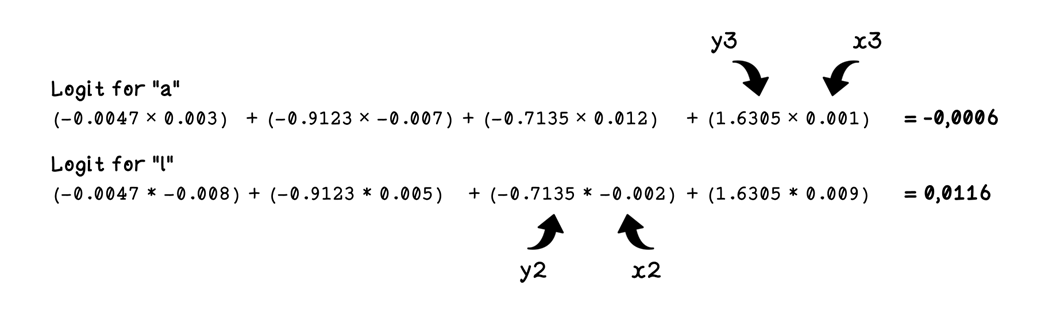
Final prediction for the next token after “a”
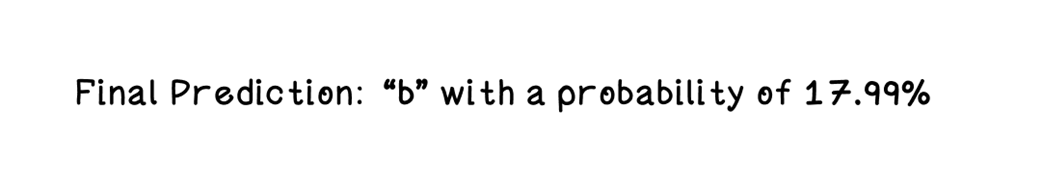
Revisiting the first training batch of tokens
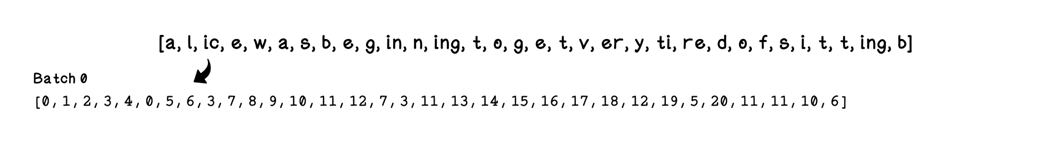
Calculations for new weights given the learning rate and gradient
How epochs repeat in the Transformer framework
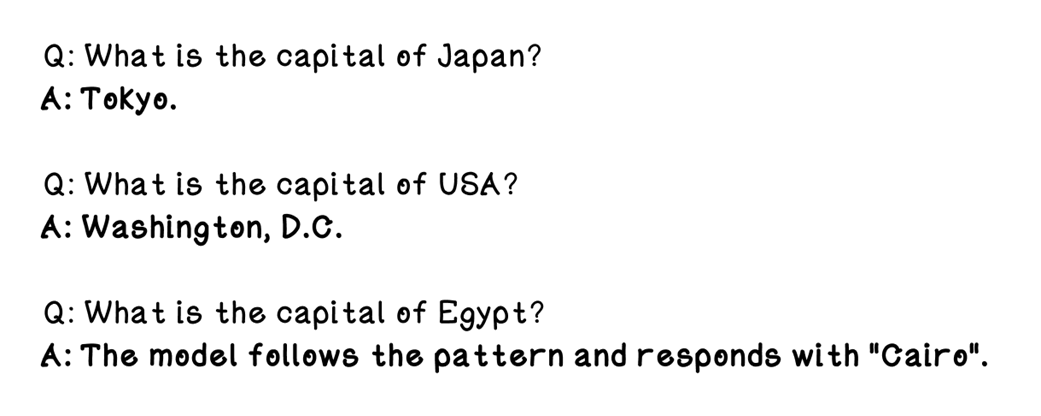
Example of use cases for few-shot learning
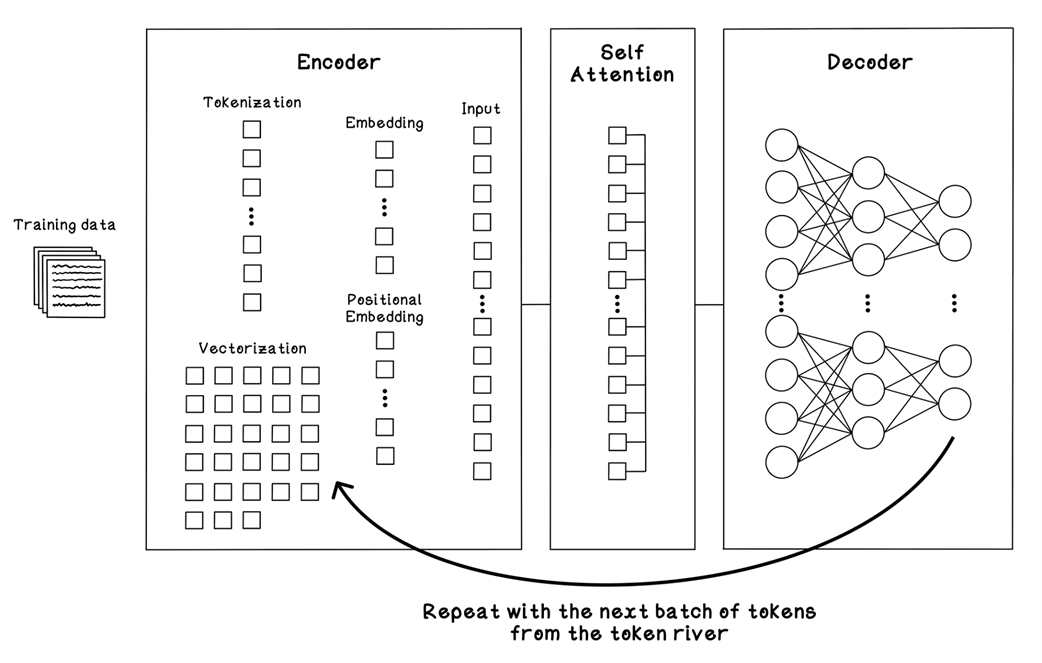
Summary of Large Language Models

FAQ

What is a large language model (LLM) and how does it differ from a simple language model?An LLM is a Transformer-based neural network trained to predict the next token in text. Unlike simple n‑gram tables that memorize short co-occurrence stats, LLMs have billions of parameters, are trained on trillions of tokens from diverse sources, and use self-attention to model long-range context, enabling tasks like generation, translation, and coding.
Why do token counts and parameter sizes matter in LLMs?More tokens expose the model to varied grammar, styles, and facts, improving generalization. More parameters increase capacity to store nuanced patterns (syntax, semantics, style). Modern models train on trillions of tokens and use billions of parameters to capture broad and rare linguistic phenomena.
How should training data be selected and cleaned for an LLM?Combine broad general text with domain-specific corpora relevant to your use case. Clean by removing boilerplate, near-duplicates, markup noise, toxicity/PII, and enforcing language consistency and normalization. Respect licensing: prefer public-domain, permissive licenses, or licensed sources. Audit data quality with metrics (duplicate rate, toxicity, readability, domain balance).
How does tokenization with Byte Pair Encoding (BPE) work?BPE starts with characters (plus end-of-word markers), counts frequent adjacent pairs (bigrams), merges the most frequent pair into a new token, and repeats until a target vocabulary size or frequency threshold is met. This yields subword tokens (e.g., “un”, “believ”, “able”) that handle rare words efficiently and share morphology.
What are embeddings and positional encodings, and why do we need both?Embeddings map discrete token IDs to dense vectors that capture meaning; positional encodings inject order information so the model knows where tokens occur in a sequence. Together (by simple addition), they provide “what” (semantics) and “where” (position), enabling attention to reason over ordered text.
How does self-attention compute which tokens matter?Each input vector is linearly projected into Query (Q), Key (K), and Value (V). Attention scores are dot products of Q with all Ks, scaled by √d, then passed through softmax to obtain weights. The output is a weighted sum of Vs. Multi-head attention repeats this with multiple Q/K/V sets to capture different relationship “perspectives.”
What happens after attention: residuals, normalization, and feed-forward networks?The attention output is added to the original input (residual connection) and layer-normalized. A position-wise feed-forward network (project up → nonlinearity → project down) transforms features, followed by another residual and layer norm. Stacking many such blocks builds progressively richer representations.
How does the model make predictions and learn from mistakes?The final hidden vector is projected to vocabulary-sized logits; softmax converts logits to next-token probabilities. Training uses cross-entropy loss with the true next token, then backpropagation nudges all parameters (embeddings, attention, feed-forward, output head) to lower future loss. This repeats over many batches and epochs.
How do we control training and model behavior (epochs, checkpoints, early stopping, hyperparameters)?- Epochs: iterate over the full dataset; batches fit the context window and hardware limits. - Checkpoints: save weights periodically and/or on best validation loss. - Early stopping: halt when validation loss stops improving (patience). - Hyperparameters: tune learning rate, context window, embedding width, depth, number of heads, feed-forward size—via heuristics, manual tuning, random/grid search, or Bayesian optimization.
What advanced techniques extend LLM capability, and what are common use cases?- In‑context learning: zero‑shot (no examples) and few‑shot (prompted examples) adapt behavior without weight updates. - RLHF: align responses with human preferences via a reward model and reinforcement learning. - MoE: route tokens to specialized “experts” to scale capacity efficiently. - RAG: retrieve external documents and feed them to the model to reduce hallucinations and stay up-to-date. Use cases include content generation, information synthesis, coding assistance, and adding intelligent features to digital products.

pro $24.99 per month

  • access to all Manning books, MEAPs, liveVideos, liveProjects, and audiobooks!
  • choose one free eBook per month to keep
  • exclusive 50% discount on all purchases
  • renews monthly, pause or cancel renewal anytime

lite $19.99 per month

  • access to all Manning books, including MEAPs!

team

5, 10 or 20 seats+ for your team - learn more


choose your plan

team

monthly
annual
$49.99
$499.99
only $41.67 per month
  • five seats for your team
  • access to all Manning books, MEAPs, liveVideos, liveProjects, and audiobooks!
  • choose another free product every time you renew
  • choose twelve free products per year
  • exclusive 50% discount on all purchases
  • renews monthly, pause or cancel renewal anytime
  • renews annually, pause or cancel renewal anytime
  • Grokking AI Algorithms, Second Edition ebook for free

choose your plan

team

monthly
annual
$49.99
$499.99
only $41.67 per month
  • five seats for your team
  • access to all Manning books, MEAPs, liveVideos, liveProjects, and audiobooks!
  • choose another free product every time you renew
  • choose twelve free products per year
  • exclusive 50% discount on all purchases
  • renews monthly, pause or cancel renewal anytime
  • renews annually, pause or cancel renewal anytime
  • Grokking AI Algorithms, Second Edition ebook for free