1 Starting a fabulous adventure
This chapter introduces the book’s guiding idea: data structures and algorithms are “fabulous” when they help solve real problems in surprising, elegant, or conceptually powerful ways. It frames algorithms as finite procedures for solving problems, data structures as organized ways to store information, and complexity as the relationship between problem size and the resources needed to solve it. The chapter also emphasizes that good programming is not just about mechanism, but about writing code that captures meaning, scales appropriately, and can even feel inventive or fun.
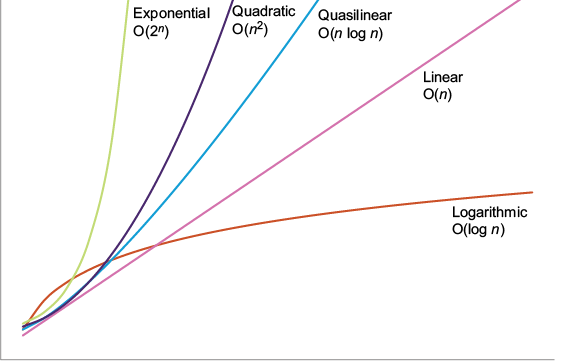
The chapter then gives a concise overview of complexity analysis using big O notation, ranging from constant-time and logarithmic growth to linear, quasilinear, quadratic, exponential, and factorial behavior. It explains how these growth rates affect practical performance, why the size measure for a problem must be clear, and why time is not the only cost that matters, since memory and best-, average-, and worst-case behavior can all be relevant. It also warns that asymptotically better algorithms are not always better in practice, especially when inputs are small or typical usage patterns do not stress the worst case.
To make these ideas concrete, the chapter builds an immutable linked list in C# and examines its design choices and performance characteristics. It shows how to create and reverse such a list by repeatedly pushing values onto a new list, preserving the original structure while producing a reversed copy in linear time and space. Along the way, it highlights subtle pitfalls such as null handling, recursive equality, and accidentally quadratic string concatenation, then closes by previewing the book’s broader journey into persistent data structures, unusual list techniques, search and transformation algorithms, and tools for probability and statistical reasoning.
A graph comparing the growth curves for logarithmic, linear, quasilinear, quadratic, and exponential growth. The logarithmic curve is the shallowest, growing slowly, and the exponential curve is the fastest.
Summary
- There are lots of books about standard data structures, such as lists, trees, and hash tables, and the algorithms for sorting and searching them. Lots of implementations of them are already in class libraries. In this book, we’ll look at the less well-known, more off-the-beaten-path data structures and algorithms that I had to learn about during my career. I chose the topics that I found the most fabulous: the ones that are counterintuitive or seemingly magical or that push the boundaries of languages.
- I had to learn about almost all the topics in this book when I needed a new tool in my toolbox to solve a job-related problem. I hope that this book saves you from having to read all the abstruse papers I had to digest if you too have such a problem to solve.
- More important to me, all these fabulous adventures gave me a deeper appreciation for what computer programmers are capable of doing. They changed how I think about the craft of programming. I had a lot of fun along the way, and I hope you do too.
- Asymptotic complexity measures how well a solution scales with the size of the problem you’re throwing at it. You generally want algorithms to be better than quadratic if you want them to scale to large problems.
- Complexity analysis can be subtle. It’s important to remember that time is not the only resource users care about; they might also have opinions about whether avoiding a bad worst-case scenario is more or less important than achieving excellent average performance.
- If problems are always small, asymptotic complexity matters less.
- Reversing a linked list is straightforward if you have an immutable list. Chapter 2 looks at other kinds of immutable lists.

 Fabulous Adventures in Data Structures and Algorithms ebook for free