5 What’s up with you, Directed Acyclic Word Graph?
The chapter opens with the practical problem of searching large word lists quickly, especially for tasks like autocomplete and Scrabble-style word generation. It compares several representations of a dictionary of words through an abstract interface that supports checking whether a word exists and enumerating all words with a given prefix. A hash set is rejected because it handles exact lookup well but cannot support prefix search efficiently, while a sorted list works reasonably well with binary search but still leaves prefix queries tied to repeated string checks and logarithmic search cost.
The chapter then introduces prefix trees, or tries, as a better fit because they share common prefixes instead of storing them repeatedly. It explains how trie nodes can be represented with a word-ending flag and outgoing edges stored in a character-to-node dictionary, then shows how to build a trie from a sorted word list by reusing common prefixes and appending only the new suffix. This yields faster exact lookup and prefix enumeration, both essentially linear in word length, but the memory savings are limited by the large number of repeated leaf nodes and the overhead of many separate objects.
To push further, the chapter reframes tries as finite-state automata and shows how to eliminate not just shared prefixes but also shared suffixes, producing a Directed Acyclic Word Graph. The DAWG-building algorithm works incrementally on sorted words by optimizing the previously added suffix before extending the next word, using node equivalence tests and a hash set of canonical nodes to merge identical subgraphs safely. The result is a much smaller structure that preserves the same search capabilities as a trie, delivering the same asymptotic build cost while dramatically reducing node count and memory use on large English word lists.
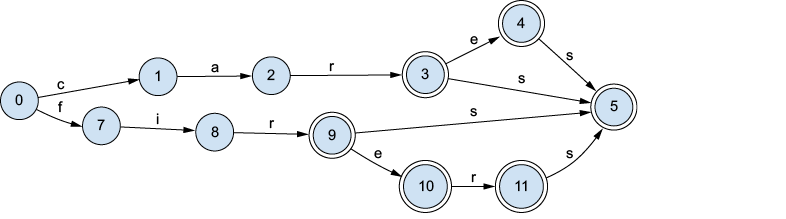
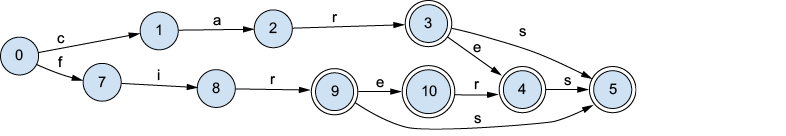
The trie for a nine-word list, laid out here left to right and in alphabetical order from top to bottom. Node numbers aren’t data in the tree; they’re included only so I can refer to them in the discussion that follows. Double-circle nodes represent ends of words.
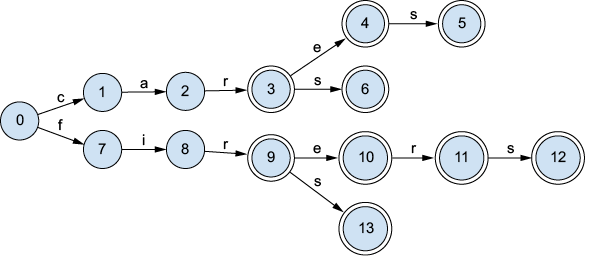
The trie for the word list car
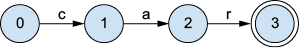
The trie for the word list car, care
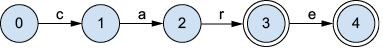
A trie with nine words: car, care, cares, cars, fir, fire, firer, firers, and firs
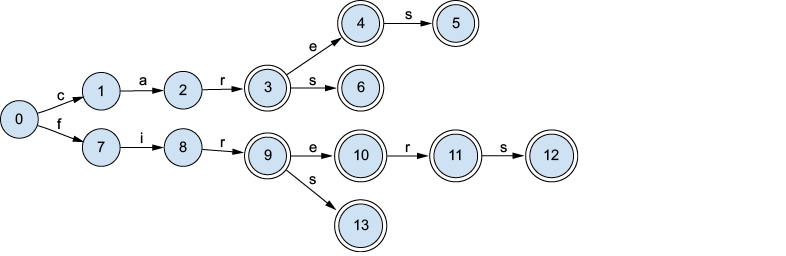
Deduplicating all the leaves of the trie produces an equivalent word graph.
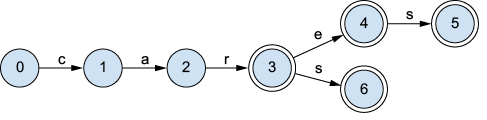
We’ve added car, care, cares, and cars. The graph is optimized for everything except for cars. Node 6 is identical to node 5, but because node 6 is in cars, we haven’t fixed it yet.
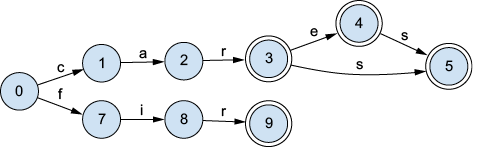
After fir is added, the graph is optimized for every word except for fir. Node 9 could be replaced by node 5, so this graph is not optimized for the final word.
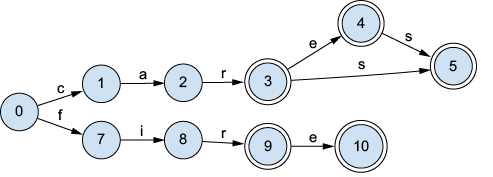
Do you notice anything odd about this graph after fire is added?
After firer and firers are added, the nodes for firers still aren’t optimized.
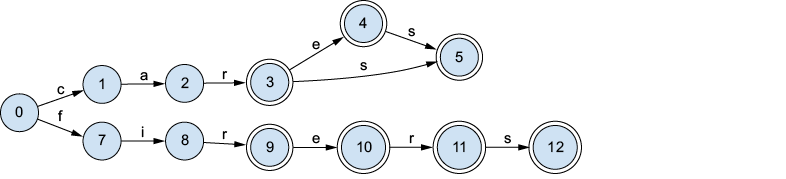
We look for optimizations by moving backward from the end of the previous word added and first discover that node 12 is redundant. Node 11 should have an edge to node 5 instead.
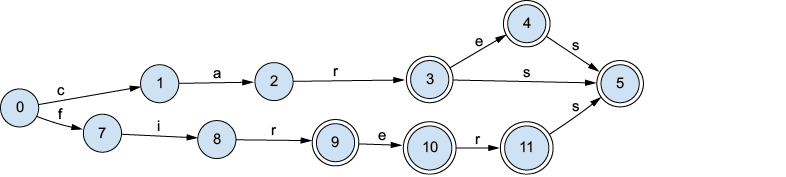
figure 5.11 Now we’ve fully optimized the ers portion of firers and are ready to add firs.
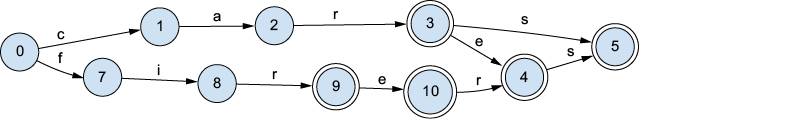
Now firs is added, and everything is optimized except node 13, which is redundant to node 5.
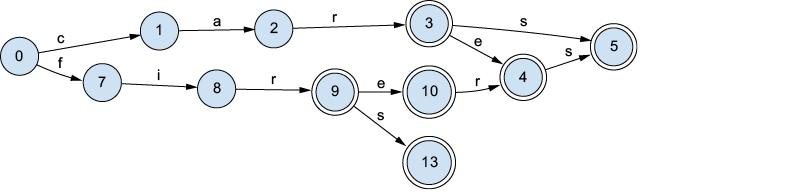
The smallest possible DAWG representing those nine words
Summary
- Storing n words of average length m in a list so that we can generate all the words matching a particular prefix is a common problem. The number of words can be quite large.
- Hash sets are great at determining whether a given word is contained in a set but not at generating completions from a prefix.
- We can get O(m log n) search performance by using binary search on a sorted list, which is probably acceptable, but this solution uses a surprisingly large amount of memory if we use off-the-shelf parts.
- We can get O(m) search performance by using a trie to deduplicate prefixes, but the number of redundant nodes is potentially enormous.
- By noticing that tries are a special case of FSAs, we can use any of many algorithms that minimize FSAs without changing the language they recognize. But starting with the huge, space-inefficient trie in memory and running an expensive, difficult minimization algorithm isn’t ideal. We really want to build an optimized DAWG one word at a time.
- Efficiently detecting when two nodes are redundant and can be safely merged is a key subproblem in graph minimization. If we’re careful not to mutate a node after it’s in the canonical set of optimized nodes, we can do so efficiently.
- We can make DAWGs very small in memory if we have to, which is what game developers did back in the day.
FAQ
What problem does a word-list data structure need to solve in this chapter?
It needs to support fastContains checks and efficient StartsWith prefix searches while using as little memory as practical.Why are hash sets a poor choice for prefix searching?
Hash sets are good forContains, but they do not support StartsWith efficiently because similar words are intentionally spread across different buckets.What is the advantage of storing words in a sorted list?
A sorted list supportsContains with binary search and allows StartsWith by finding the first matching position and then scanning forward.What is the main limitation of the sorted-list approach?
StartsWith can still be expensive because after the binary search it may need to check many matching words, and each prefix check costs time.What is a trie?
A trie, or prefix tree, is a structure where each edge represents a character and paths from the root spell out words, sharing common prefixes.How does a trie node represent information?
Each node stores whether it ends a word, the labels of outgoing edges, and the nodes reached by those edges.How is a trie built from a sorted word list?
Words are added one by one, reusing any shared prefix already in the trie and creating new nodes only for the remaining suffix.Why does a trie improve search performance over a sorted list?
BothContains and StartsWith can be done in O(m) time, where m is the word length, instead of O(m log n) for a sorted list.
 Fabulous Adventures in Data Structures and Algorithms ebook for free
