5 Fundamentals of machine learning
This chapter frames machine learning around the central tension between optimization and generalization, showing why overfitting is universal and how to reason about it. It explains that deep networks can fit almost anything, yet generalize because real-world data concentrate on low‑dimensional, structured manifolds; gradient descent learns smooth mappings that approximate these manifolds well enough to enable interpolation between seen points. Generalization therefore depends more on the structure and quality of data than on model cleverness: dense coverage of the input manifold, informative features, and low noise are paramount. The chapter also details common overfitting triggers—noisy or mislabeled samples, ambiguous regions of the feature space, and rare features that create spurious correlations—and motivates feature selection to remove distracting signals.
Because you can only improve what you can measure, the chapter formalizes robust evaluation. It advocates splitting data into training, validation, and a strictly held‑out test set to prevent information leaks that arise during hyperparameter tuning. When data are scarce or variance is high, it recommends K‑fold and iterated K‑fold validation, and urges establishing trivial, common‑sense baselines to ensure progress is real. It highlights pitfalls that can invalidate results—nonrepresentative splits, temporal leakage in time‑dependent problems, and redundancy across splits—and positions evaluation as the instrument panel for navigating the underfit/overfit trade‑off.
To improve model fit, start by making training work reliably: tune learning rate and batch size, pick suitable optimizers and initializations, and leverage architecture priors matched to the data modality; then raise model capacity until you can clearly overfit. To improve generalization, prioritize dataset curation (more and better data, cleaner labels, feature selection) and thoughtful feature engineering to make the latent manifold simpler and smoother. Capture the best model state with early stopping, and regulate memorization with capacity control, weight regularization (L1/L2), and especially dropout. The overarching lesson is that deep learning generalizes by interpolating over well‑sampled, well‑structured data manifolds; when more data aren’t available, careful evaluation, regularization, and better features make that interpolation more reliable.
Canonical overfitting behavior
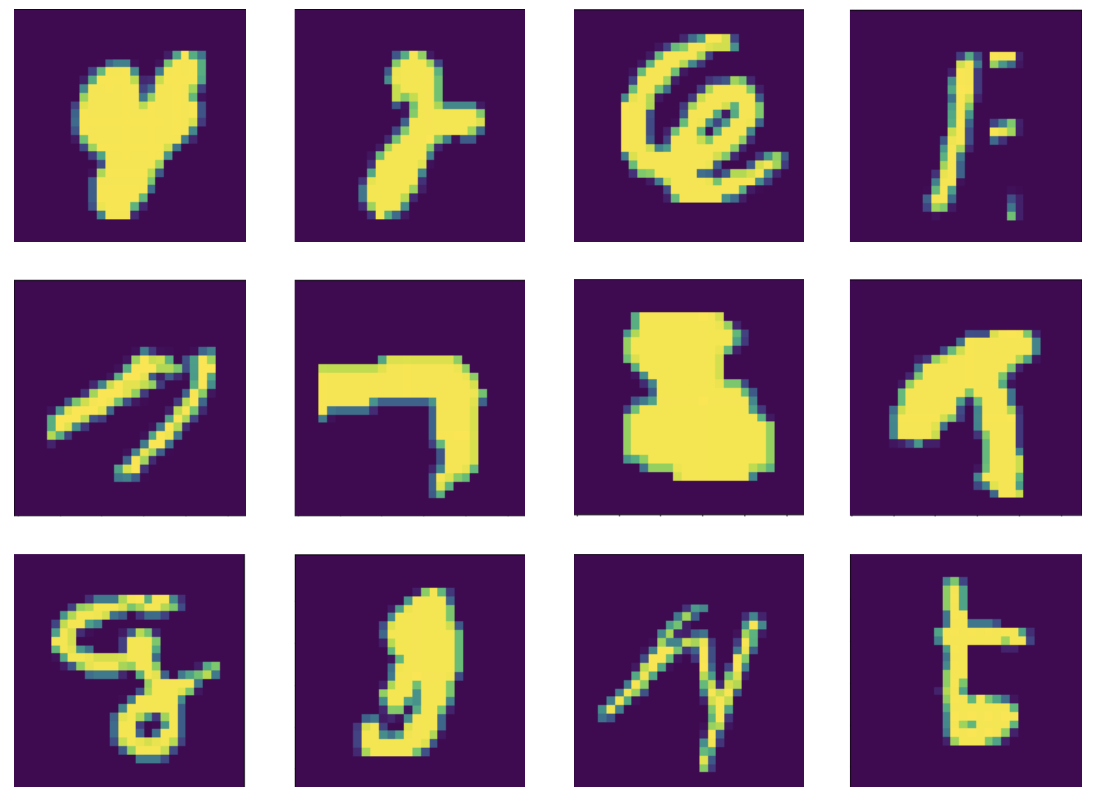
Some pretty weird MNIST training samples
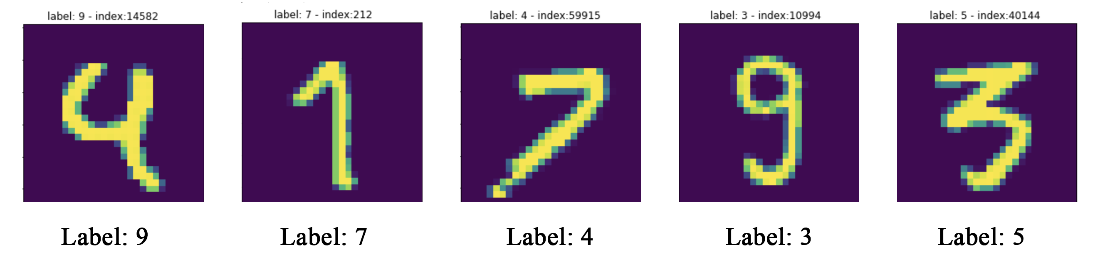
Mislabeled MNIST training samples
Dealing with outliers: robust fit vs. overfitting
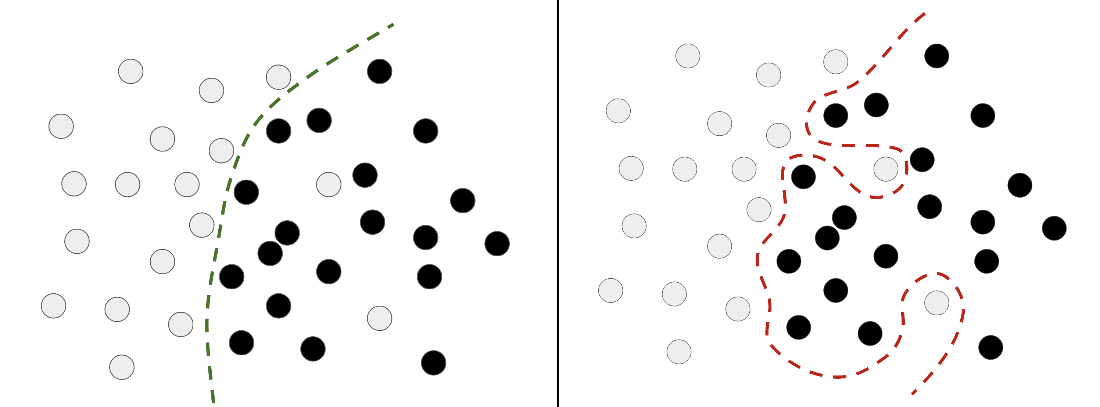
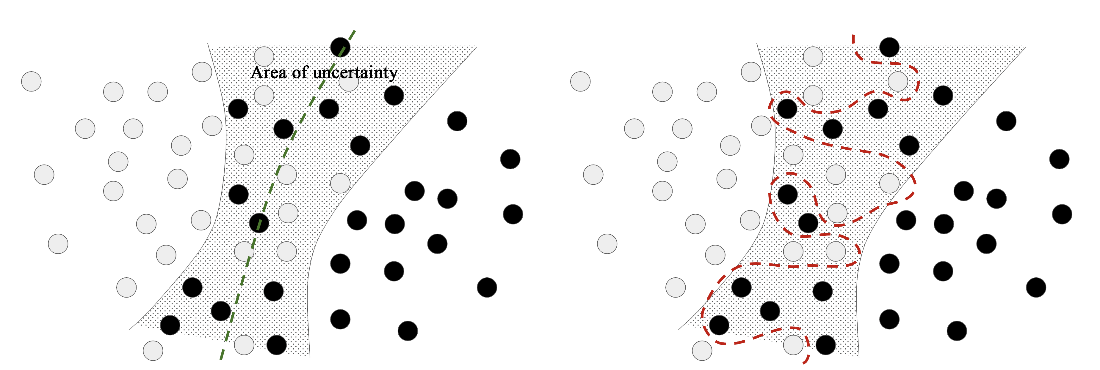
Robust fit vs. overfitting giving an ambiguous area of the feature space
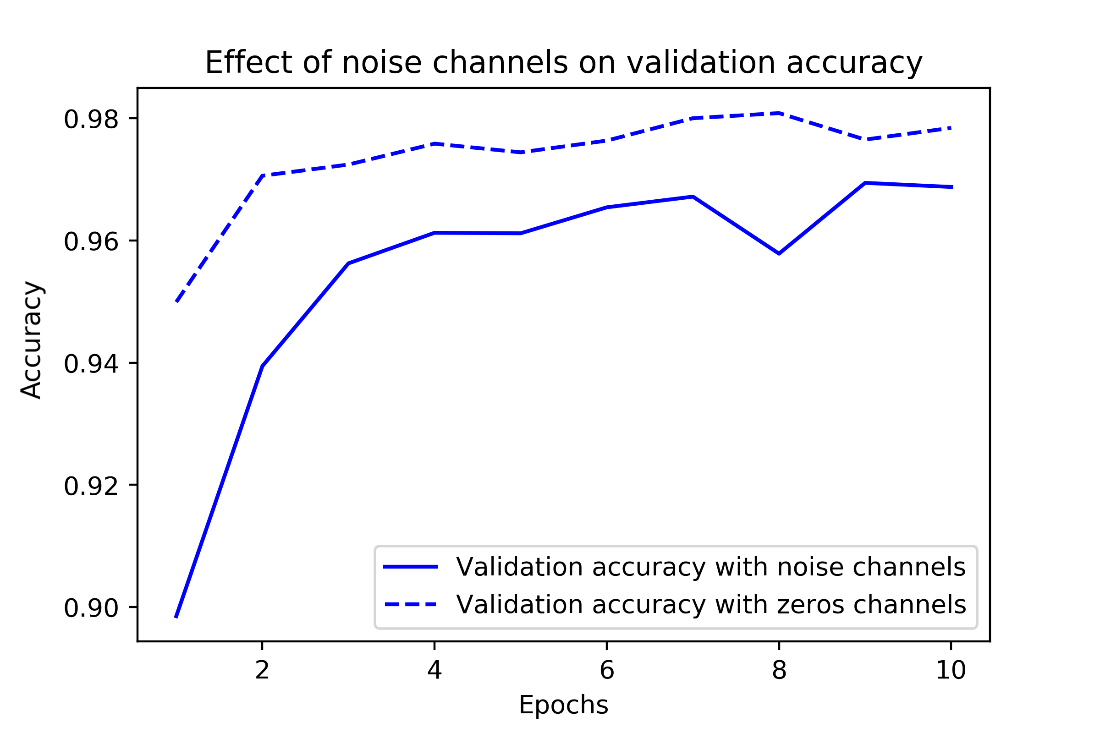
Effect of noise channels on validation accuracy
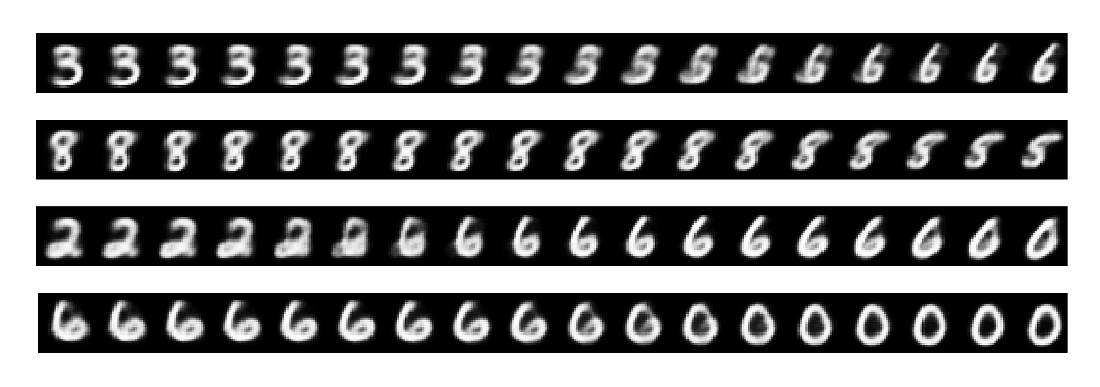
Different MNIST digits gradually morphing into one another, showing that the space of handwritten digits forms a “manifold”. This image was generated using code from Chapter 17.
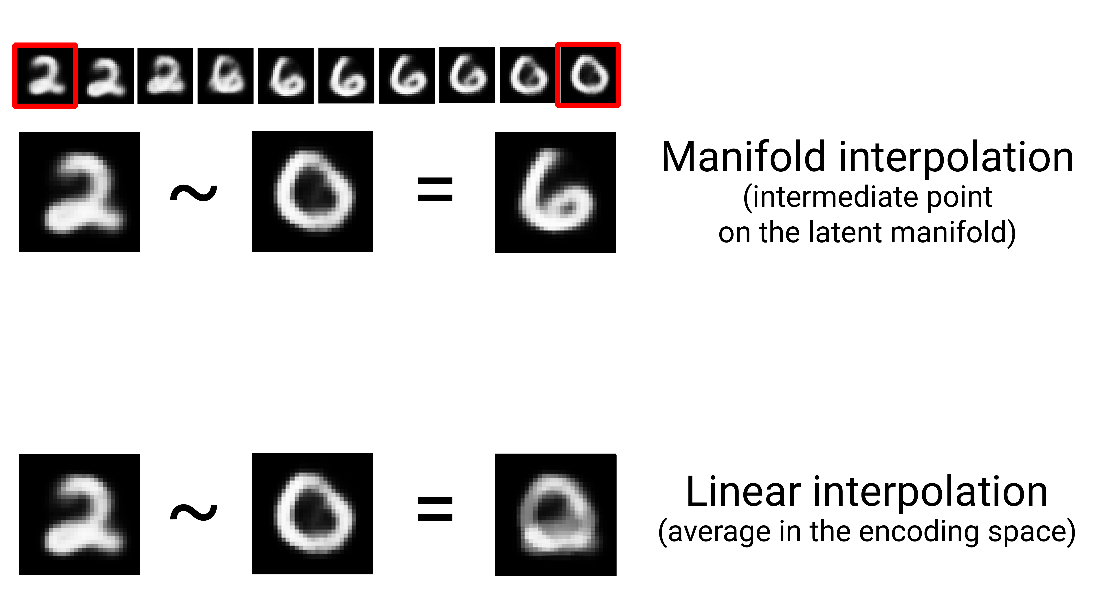
Difference between linear interpolation and interpolation on the latent manifold. Every point on the latent manifold of digits is a valid digit, but the average of two digits usually isn’t.
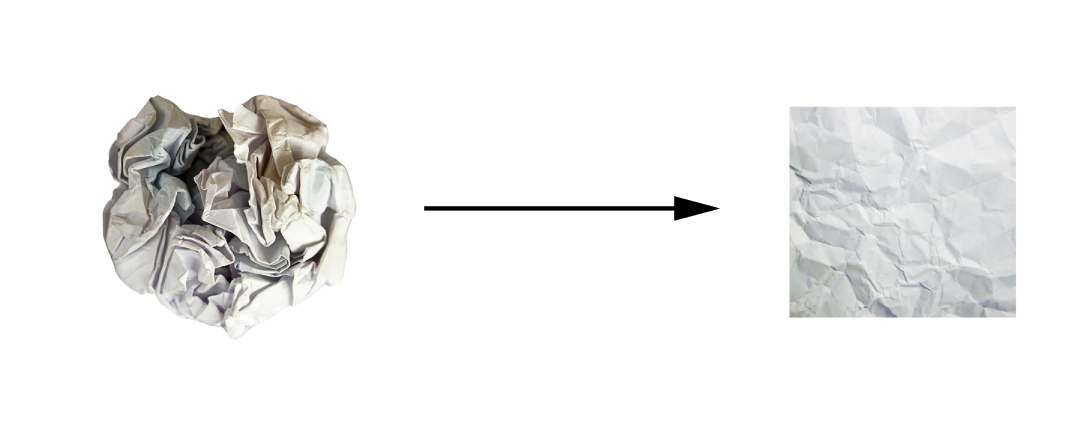
Uncrumpling a complicated manifold of data
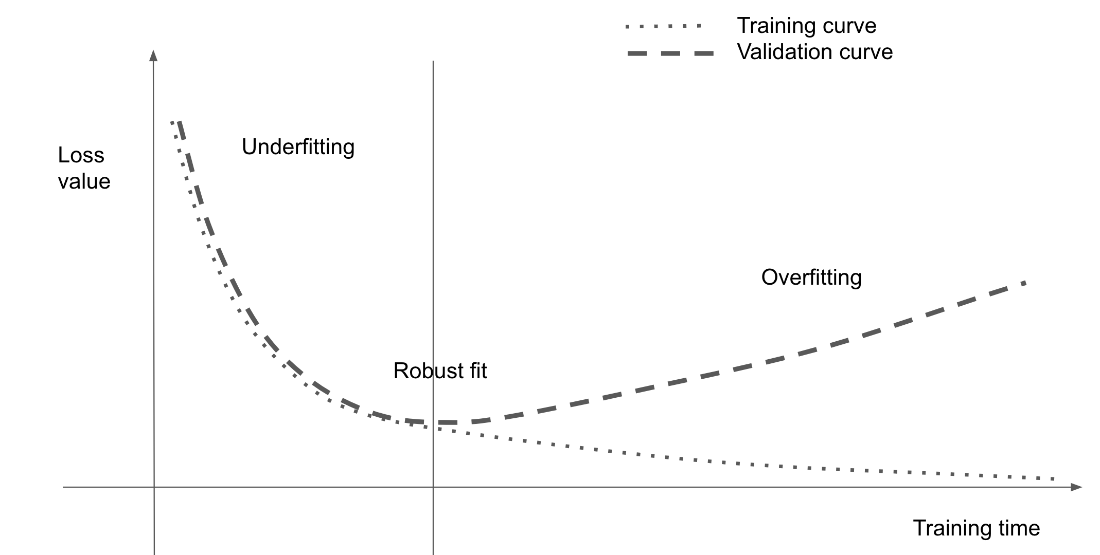
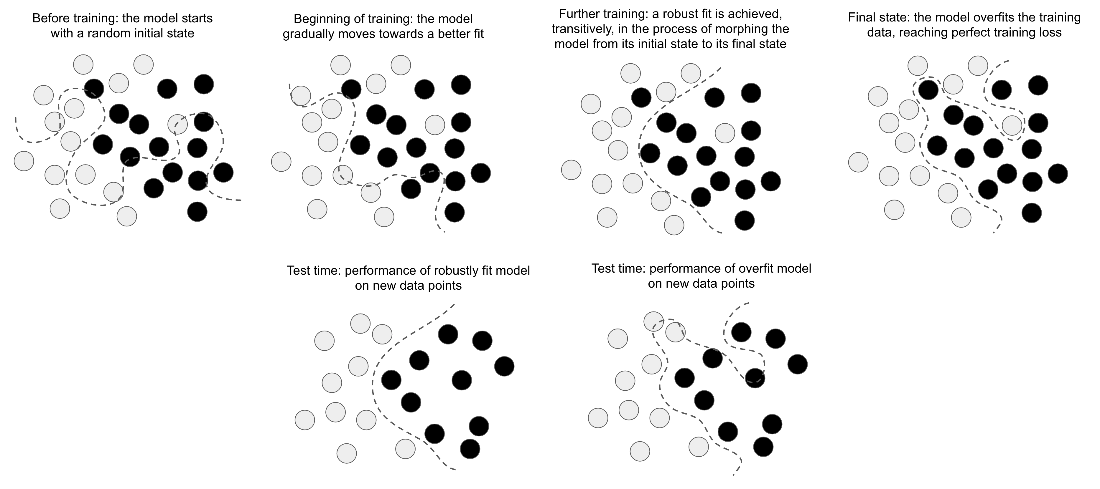
Going from a random model to an overfit model, and achieving a robust fit as an intermediate state
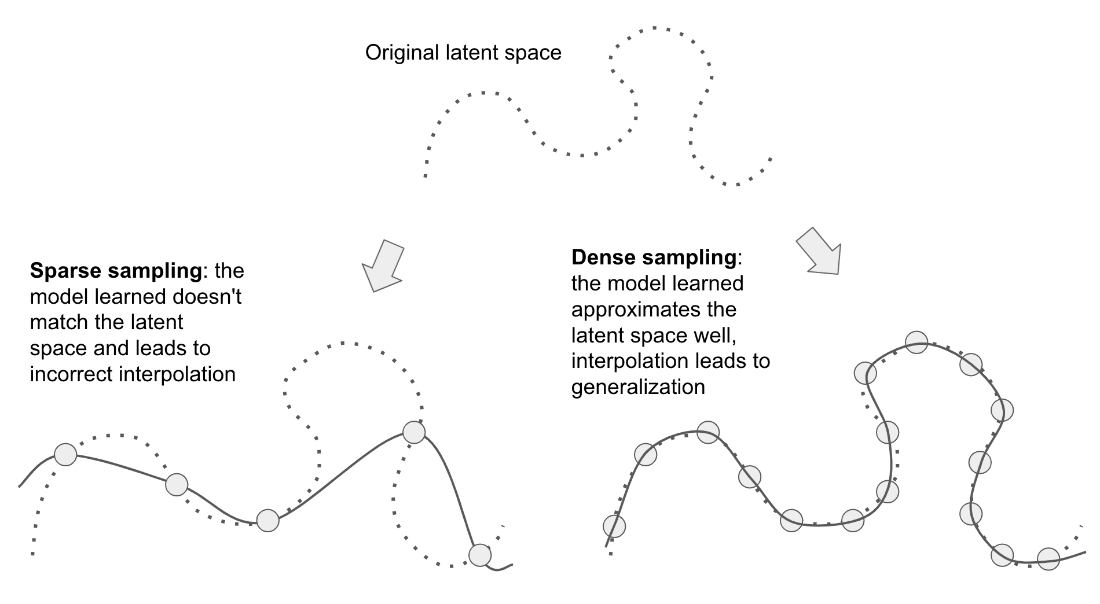
A dense sampling of the input space is necessary in order to learn a model capable of accurate generalization.
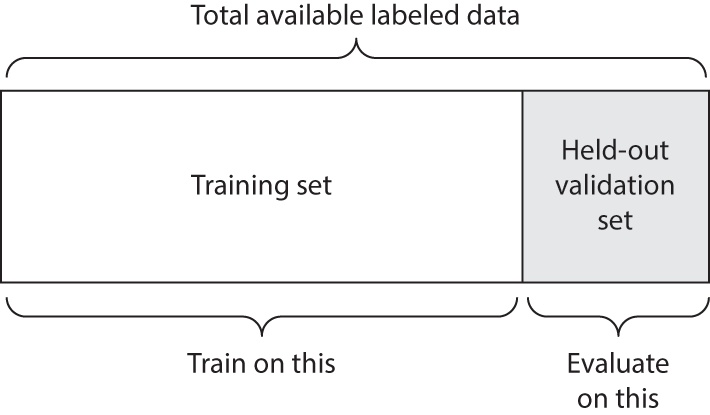
Simple hold-out validation split
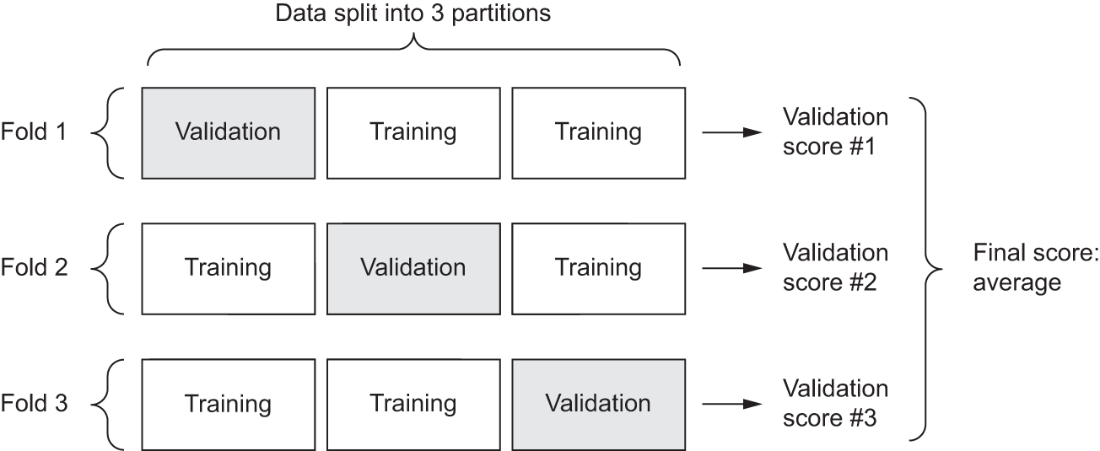
Three-fold validation
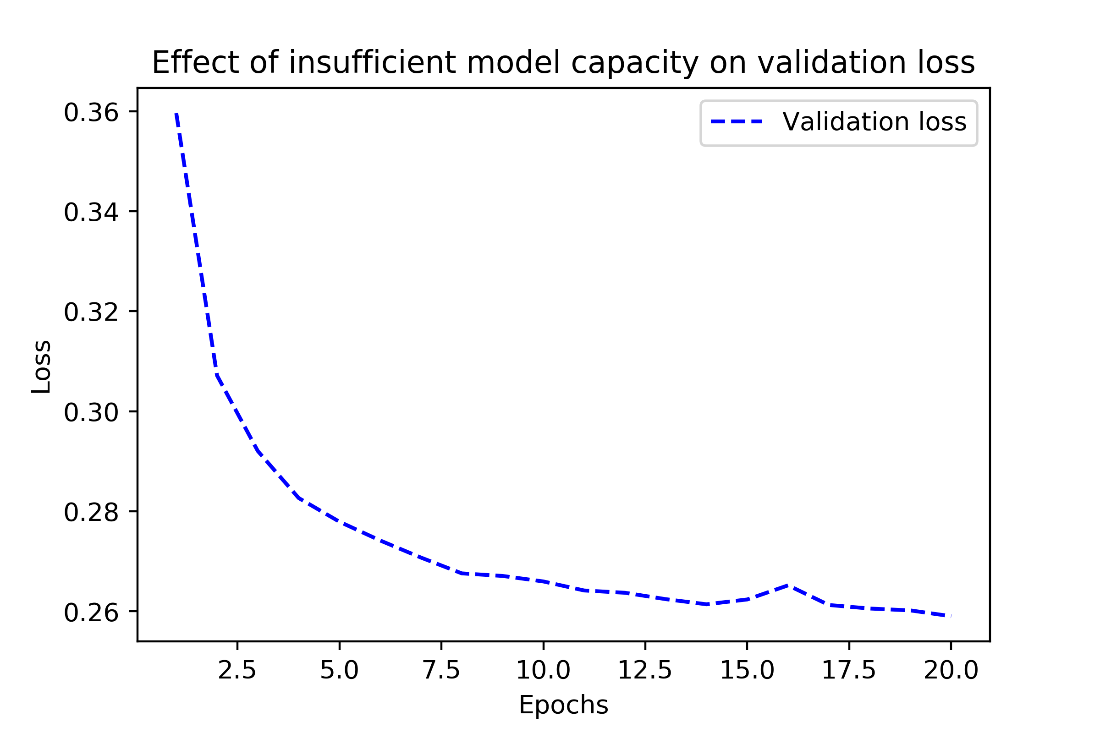
Effect of insufficient model capacity on loss curves
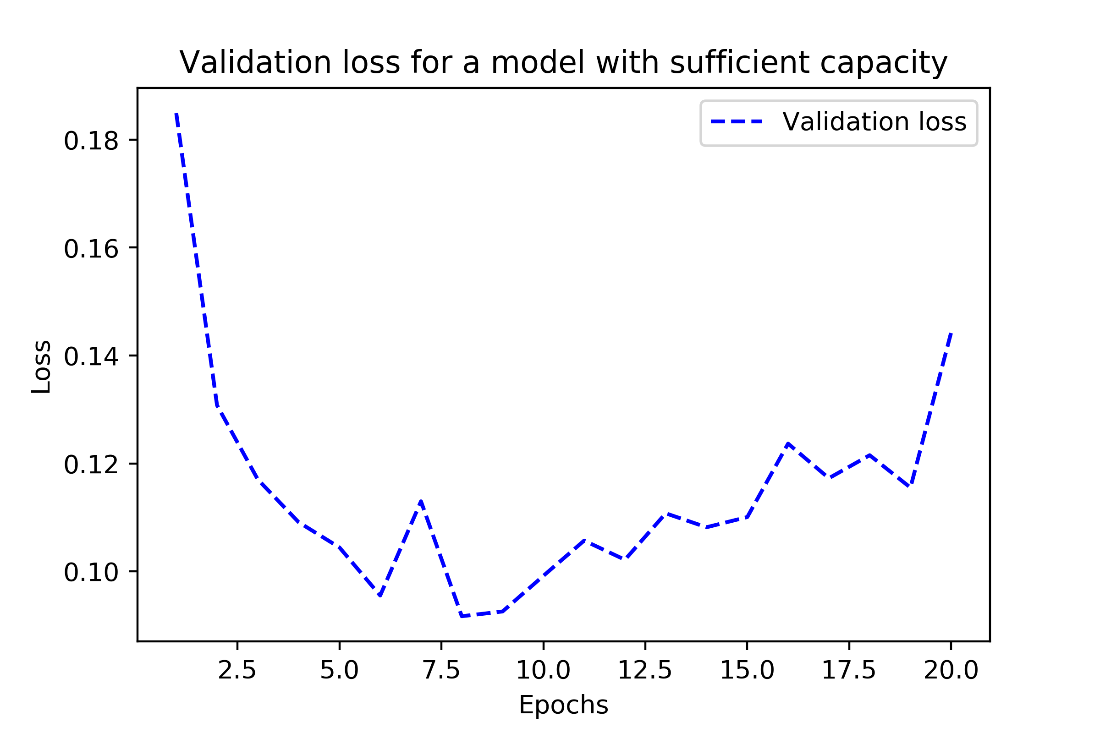
Validation loss for a model with appropriate capacity
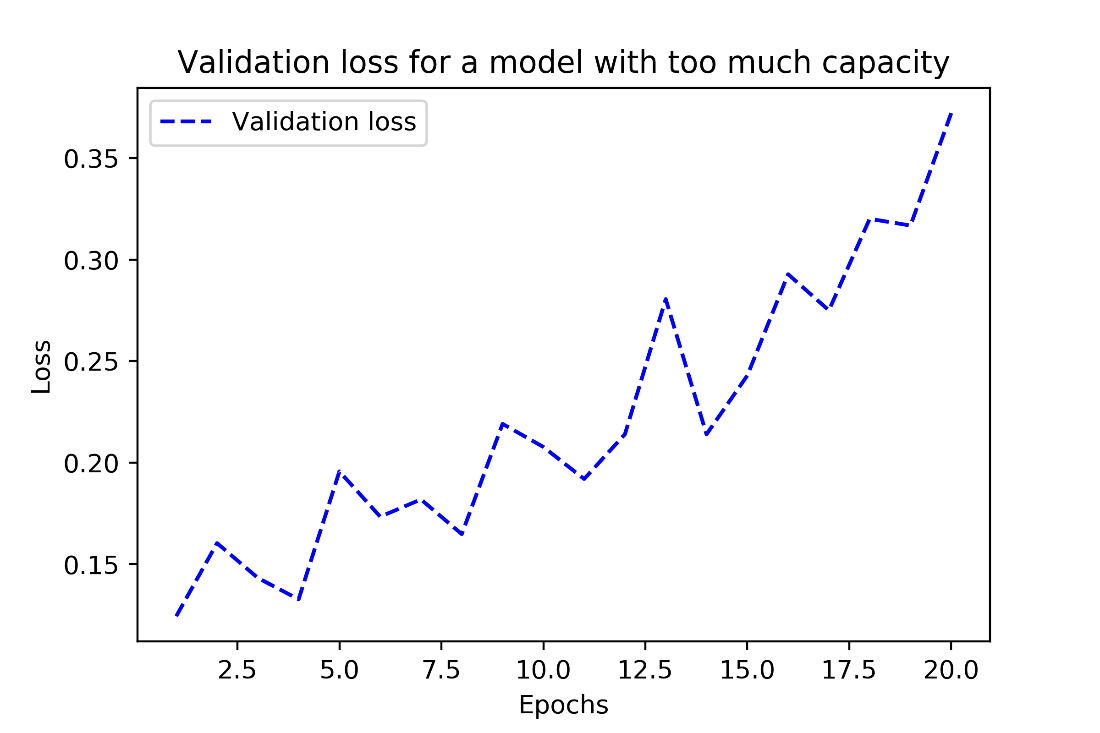
Effect of excessive model capacity on validation loss
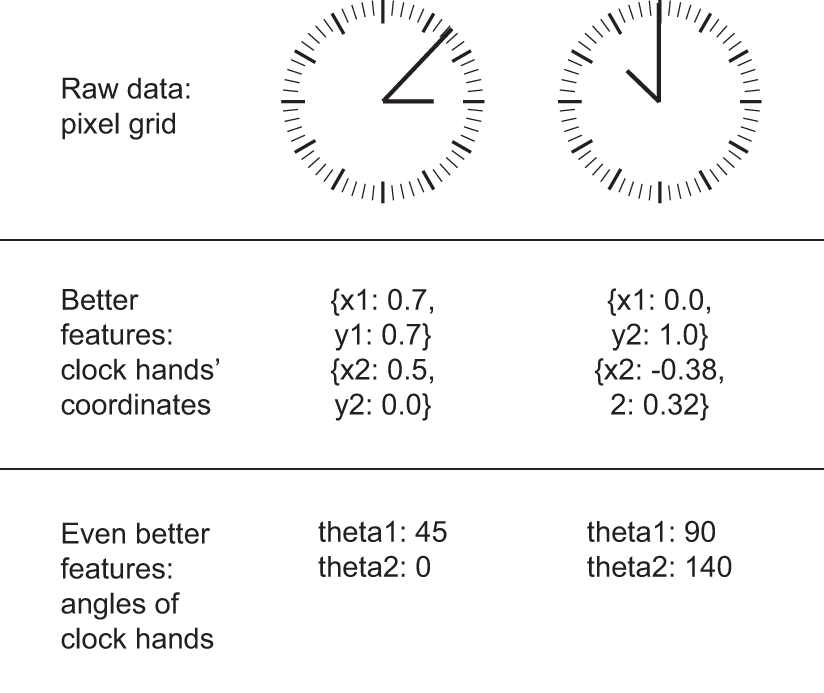
Feature engineering for reading the time on a clock
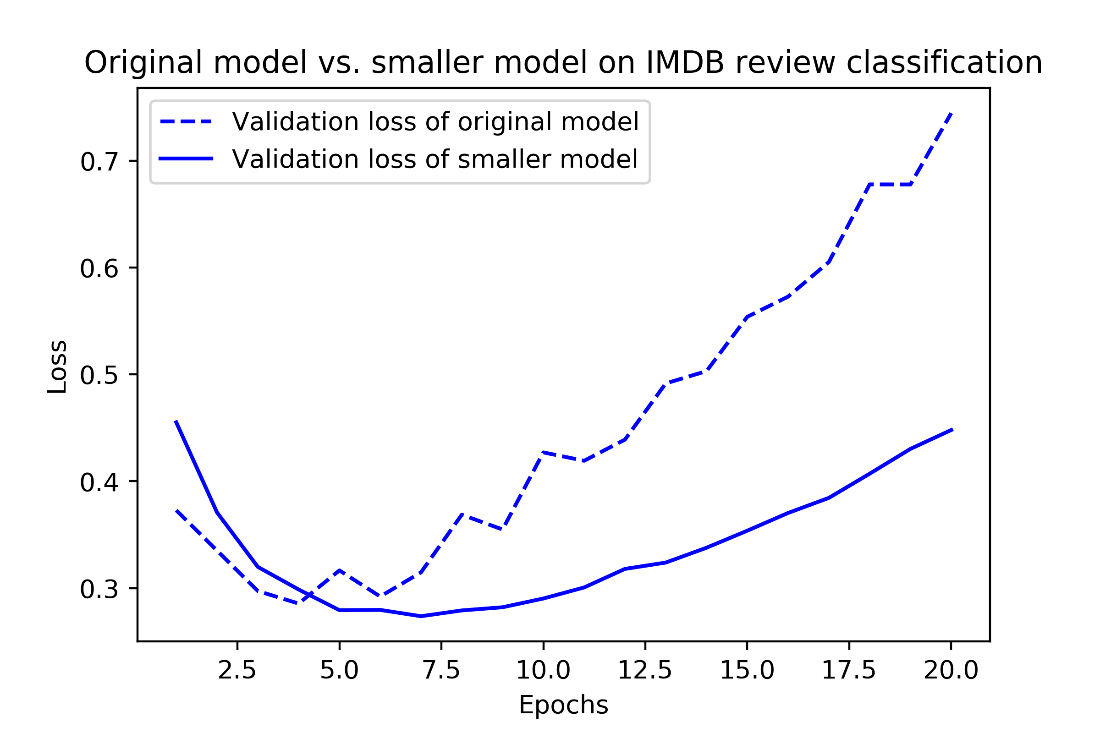
Original model vs. smaller model on IMDB review classification
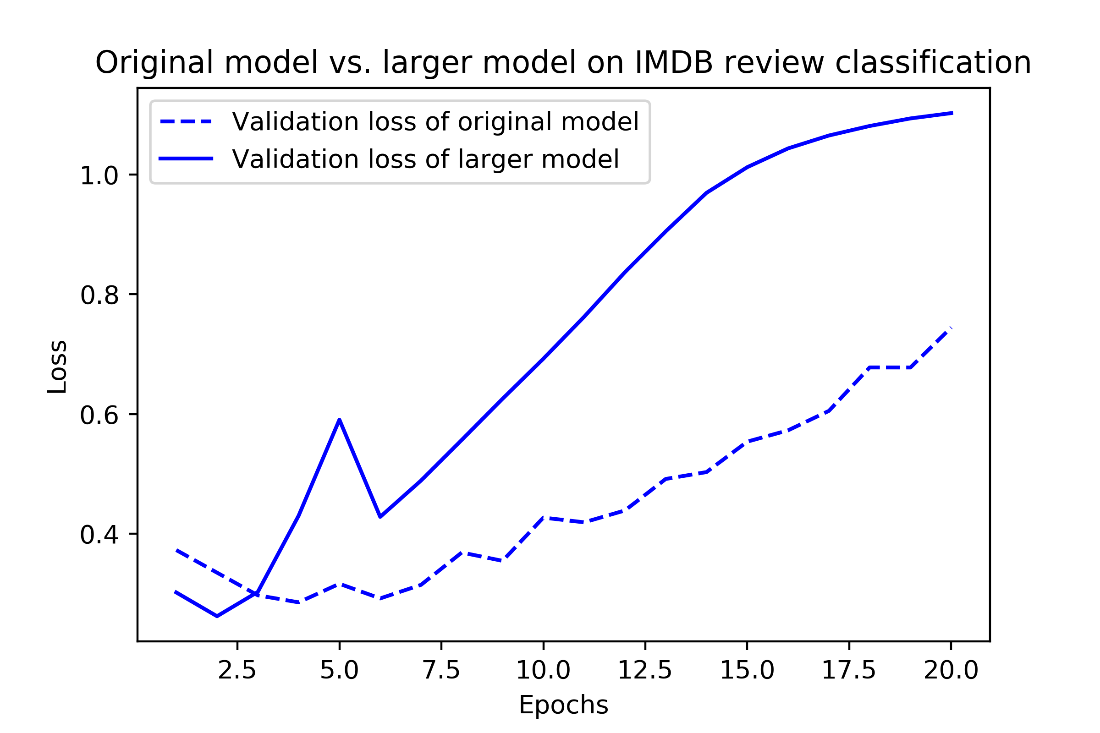
Original model vs. much larger model on IMDB review classification
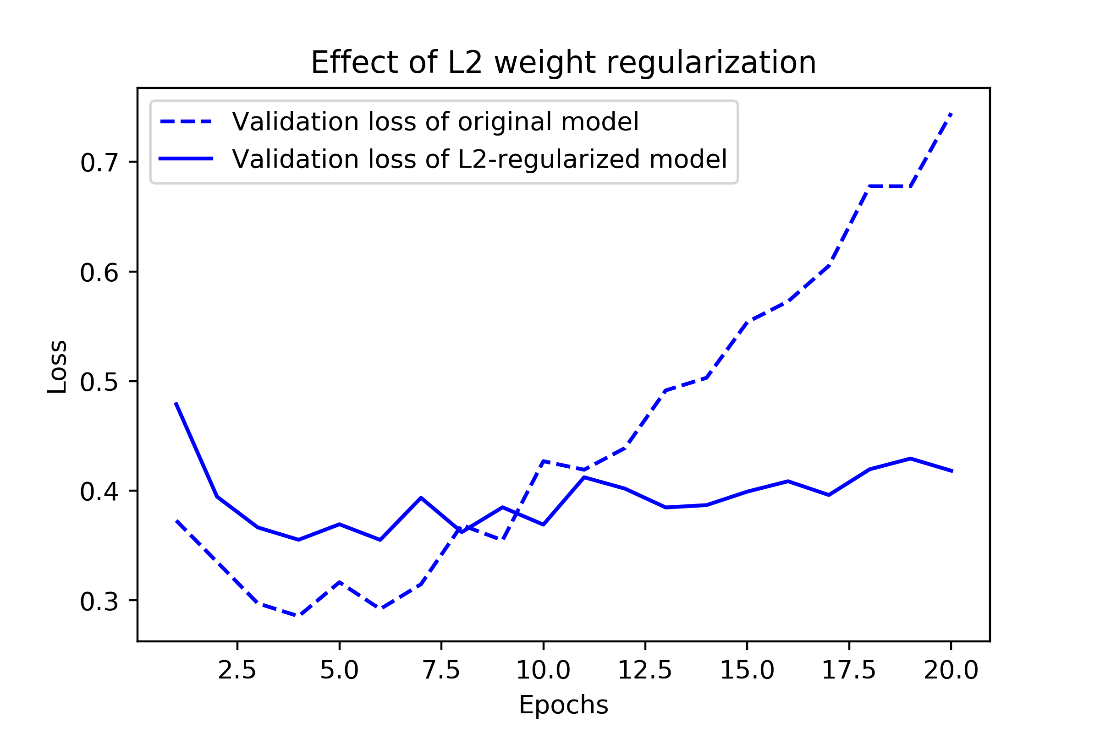
Effect of L2 weight regularization on validation loss
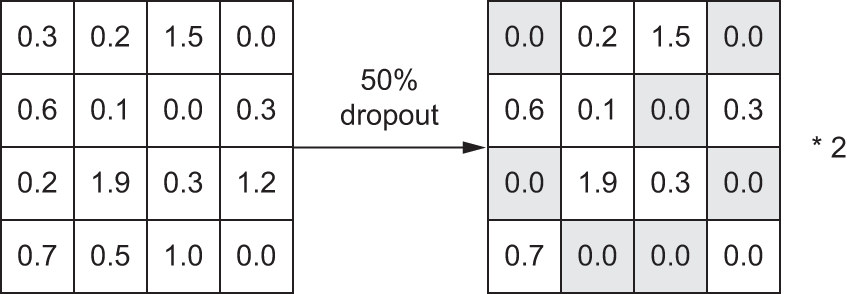
Dropout applied to an activation matrix at training time, with rescaling happening during training. At test time, the activation matrix is unchanged.
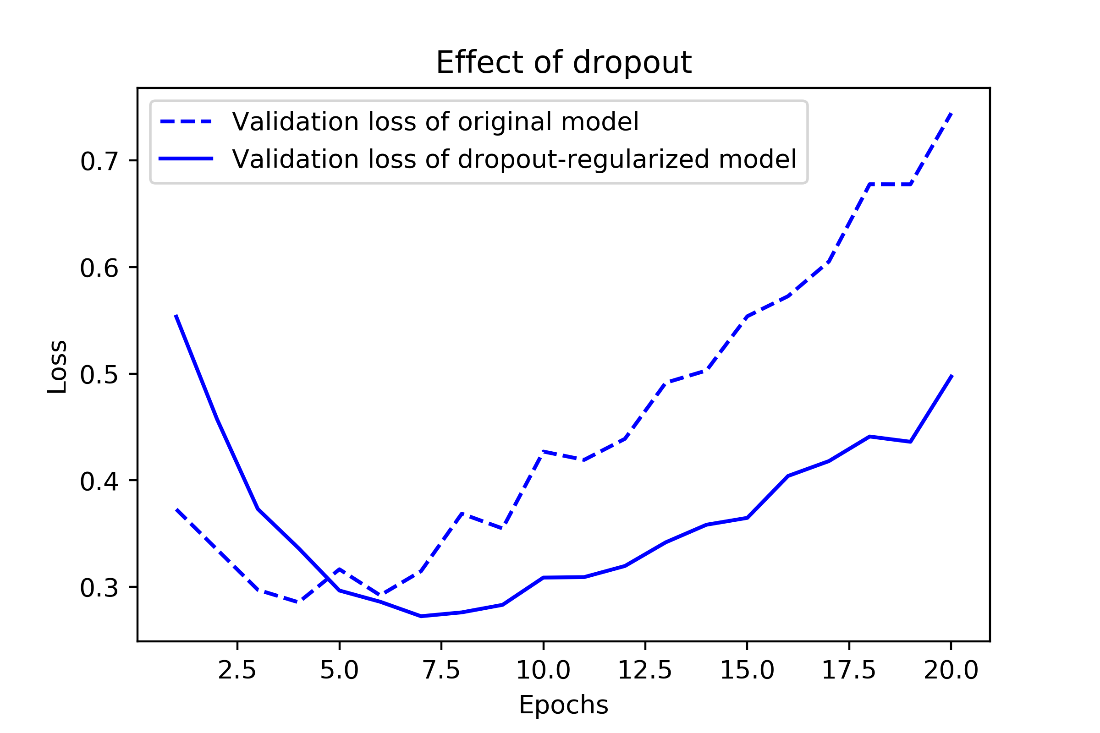
Effect of dropout on validation loss
Chapter summary
- The purpose of a machine learning model is to generalize: to perform accurately on never-seen-before inputs. It’s harder than it seems.
- A deep neural network achieves generalization by learning a parametric model that can successfully interpolate between training samples – such a model can be said to have learned the latent manifold of the training data. This is why deep learning models can only make sense of inputs that are very close to what they’ve seen during training.
- The fundamental problem in machine learning is the tension between optimization and generalization: to attain generalization, you must first achieve a good fit to the training data, but improving your model’s fit to the training data will inevitably start hurting generalization after a while. Every single deep learning best practice deals with managing this tension.
- The ability of deep learning models to generalize comes from the fact that they manage to learn to approximate the latent manifold of their data, and can thus make sense of new inputs via interpolation.
- It’s essential to be able to accurately evaluate the generalization power of your model while you’re developing it. You have at your disposal an array of evaluation methods, from simple hold-out validation, to K-fold cross-validation and iterated K-fold cross-validation with shuffling. Remember to always keep a completely separate test set for final model evaluation, since information leaks from your validation data to your model may have occurred.
- When you start working on a model, your goal is first to achieve a model that has some generalization power and that can overfit. Best practices to do this include tuning your learning rate and batch size, leveraging better architecture priors, increasing model capacity, or simply training longer.
- As your model starts overfitting, your goal switches to improving generalization through model regularization. You can reduce your model’s capacity, add dropout or weight regularization, and use early stopping. And naturally, a larger or better dataset is always the number one way to help a model generalize.
FAQ
What is the difference between optimization and generalization in machine learning?
Optimization is improving performance on training data by adjusting model parameters. Generalization is how well a trained model performs on unseen data. If you optimize “too well,” the model starts modeling idiosyncrasies of the training set (overfitting), and performance on new data degrades. The goal is not the lowest training loss, but the best validation/test performance.How can I tell if my model is underfitting or overfitting?
Watch training and validation curves over epochs. Early in training, both improve together (underfitting). After a point, validation metrics plateau and then worsen while training metrics keep improving—this is overfitting. If validation never rises above a trivial baseline, you’re not generalizing. If validation improves but never peaks or the gap to training stays small, you may be under-capacity.What data issues commonly cause overfitting?
- Noisy or mislabeled samples (outliers get memorized).- Ambiguous/uncertain regions of the feature space (model becomes overconfident locally).
- Rare features and spurious correlations (e.g., infrequent words acquiring exaggerated weights).
- Extra irrelevant features (noise channels) that the model can latch onto.
Mitigate via data cleaning, better labeling, robust features, and feature selection.
What is the manifold hypothesis and why does it matter?
The hypothesis states that natural data (images, speech, text, etc.) lives on a low‑dimensional, smooth, connected subspace (manifold) within the high‑dimensional input space. Deep models succeed because they learn smooth mappings that approximate these manifolds. This enables interpolation between nearby samples on the manifold, providing a primary source of generalization.If deep nets can fit random labels, why do they generalize on real data?
They generalize because real data has structure: it lies on low‑dimensional manifolds. Gradient descent learns smooth functions, and midway through training the model approximates the data manifold well enough to interpolate between samples. Architecture priors (e.g., for images or sequences) help too. Crucially, dense, high‑quality, low‑noise training data is paramount—generalization follows the data, not magic in the model.How should I split data into training, validation, and test sets, and why do I need all three?
- Train on the training set, tune hyperparameters using validation performance, and report final results on a held‑out test set that the model has never influenced.- Using only train/test invites “validation leakage” if you tune on the test set: you’ll overfit to it and misestimate generalization.
- Keep the test set untouched until the end.
What evaluation protocols help when data is limited?
- Simple hold‑out: train/validate on a split; test once at the end.- K‑fold cross‑validation: average performance across K different validation folds to reduce variance from a single split.
- Iterated K‑fold with shuffling: repeat K‑fold multiple times for an even more stable estimate (computationally expensive).
- Always compare against a common‑sense baseline (e.g., majority class, random guess) to ensure you’re learning signal.
Training won’t start or stalls—what should I tune?
It’s usually gradient‑descent configuration:- Adjust the learning rate (too high overshoots; too low looks stalled).
- Increase batch size (reduces gradient variance).
- Keep optimizer/initialization constant while sweeping LR and batch size; you should always be able to make loss decrease.
My model won’t overfit or overfits instantly—how do I adjust capacity and architecture?
- Can’t overfit: increase capacity (more/larger layers) or use architectures with better priors for your modality (e.g., CNNs for images, RNN/Transformers for sequences).- Overfits immediately: reduce capacity, add regularization, or get more/better data.
- Use models aligned with the problem structure; mismatched architectures often fail to generalize.
What are the most effective ways to improve generalization?
- Get more or cleaner data; ensure dense coverage of the input manifold and reduce label noise.- Do feature engineering when it simplifies the problem (better representations, fewer distractions).
- Use early stopping to stop at the peak validation performance.
- Regularize: reduce model size, add weight penalties (L2/L1) for smaller models, and use dropout (highly effective at scale).
- Continuously validate with proper splits and strong baselines.

 Deep Learning with Python, Third Edition ebook for free
