Object detection localizes and categorizes objects in an image by predicting labeled bounding boxes, enabling use cases like counting, tracking across video frames, and cropping regions of interest. While instance segmentation can provide even richer, pixel-level information, it is more computationally expensive and costly to label; bounding boxes are simpler and faster. Consequently, when pixel precision isn’t required, object detection offers a practical balance of accuracy, speed, and annotation effort.
There are two major detector families: two-stage models (R-CNN variants) that first propose regions and then classify them, and single-stage models (YOLO, SSD, RetinaNet) that directly predict classes and boxes in one pass. Two-stage systems can be accurate but are often too slow for real-time or resource-constrained settings, where single-stage approaches shine. To demystify single-stage detection, the chapter builds a simplified YOLO from scratch on COCO: images and boxes are normalized, then mapped to a grid where each cell predicts class probabilities and a box (x, y, w, h, confidence). A pretrained ResNet backbone feeds a small prediction head, data are prepared to align boxes with grid cells, and a tf.data pipeline streams batched, preprocessed images for training and visualization.
Training hinges on a custom loss that combines squared error on box position and size (using a signed square root for width/height), with a confidence target based on Intersection over Union: zero for empty cells, IoU for occupied ones. Loss terms are reweighted to emphasize box placement and to prevent “no object” confidence from dominating. Initial results show emerging localization and recognition, with clear avenues for improvement (longer training, full COCO, augmentation, overlapping-box handling, multiple boxes per cell, finer grids). The chapter then demonstrates a pretrained RetinaNet, which employs a feature pyramid network to capture multi-scale features, delivering strong, robust detections—even on out-of-distribution images—illustrating the practical advantages of modern single-stage detectors and when to favor detection over segmentation.
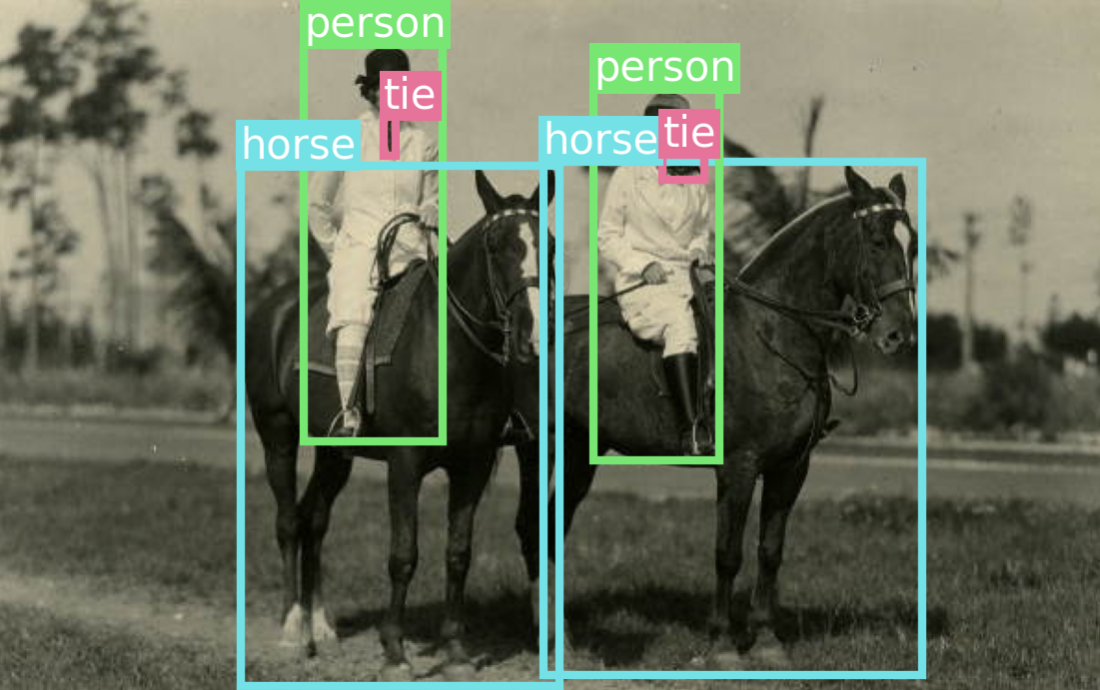
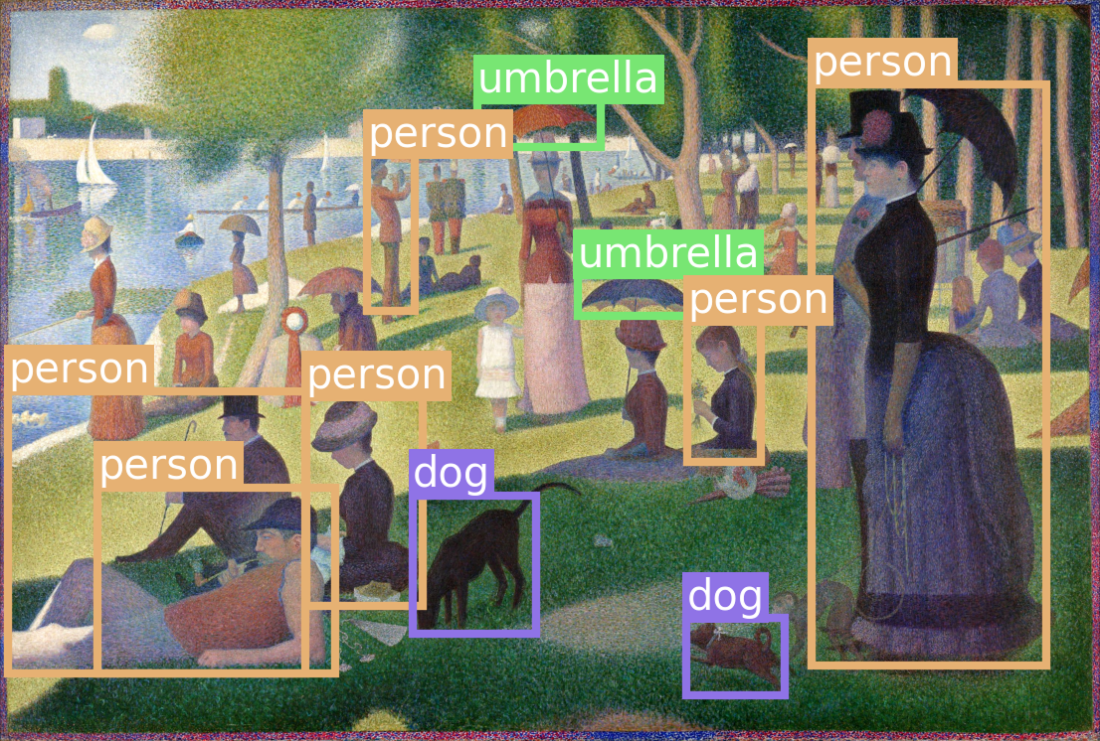
Object detectors draw boxes around objects in an image and label them.
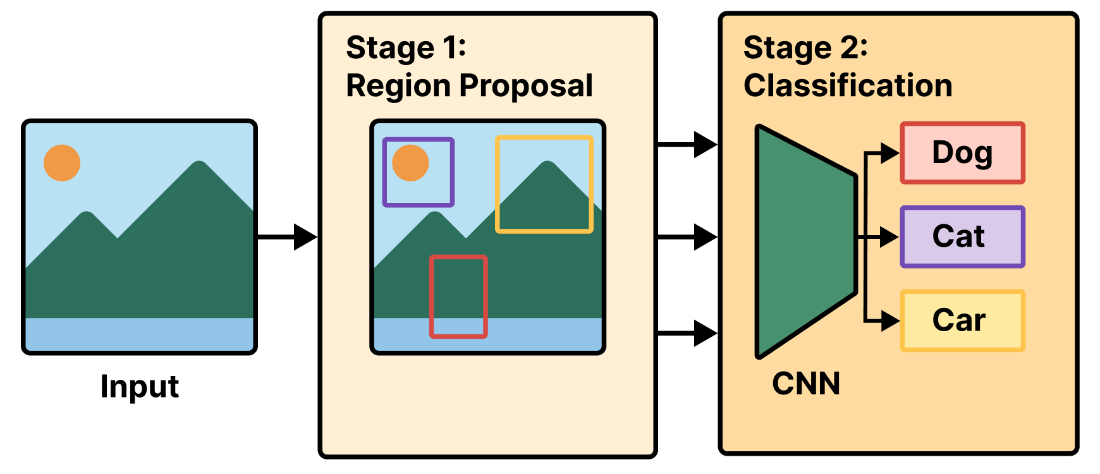
An R-CNN first extracts region proposals, then classifies the proposals with a convnet (a CNN).
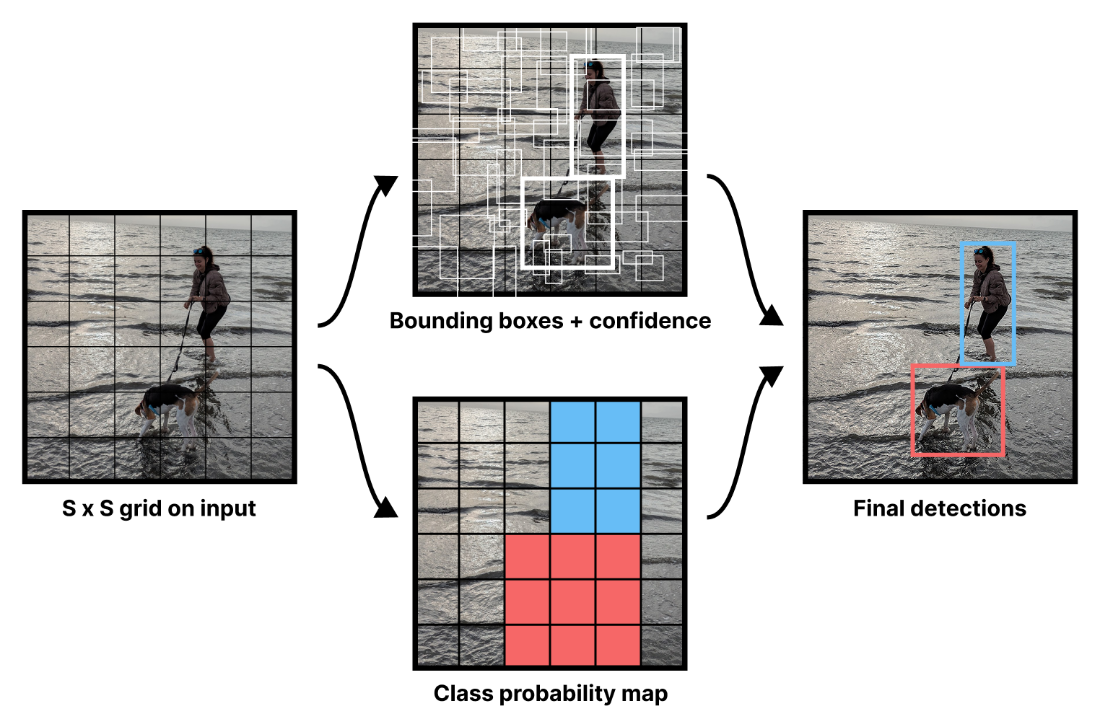
YOLO outputs a bounding box prediction and class label for each image region. [2]
YOLO outputs as visualized in the first YOLO paper.
YOLO outputs a bounding box prediction and class label for each image region. [4]
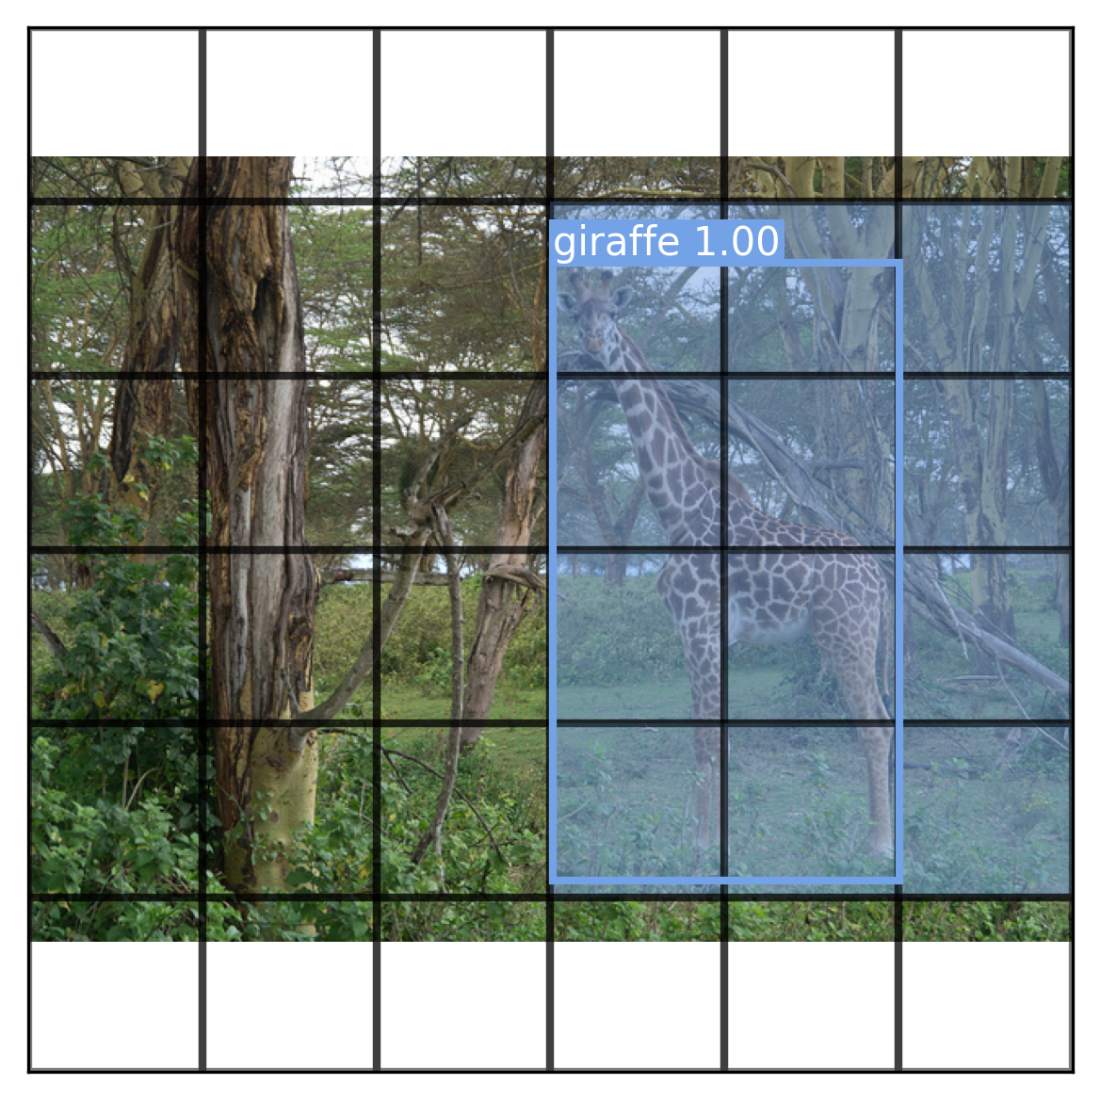
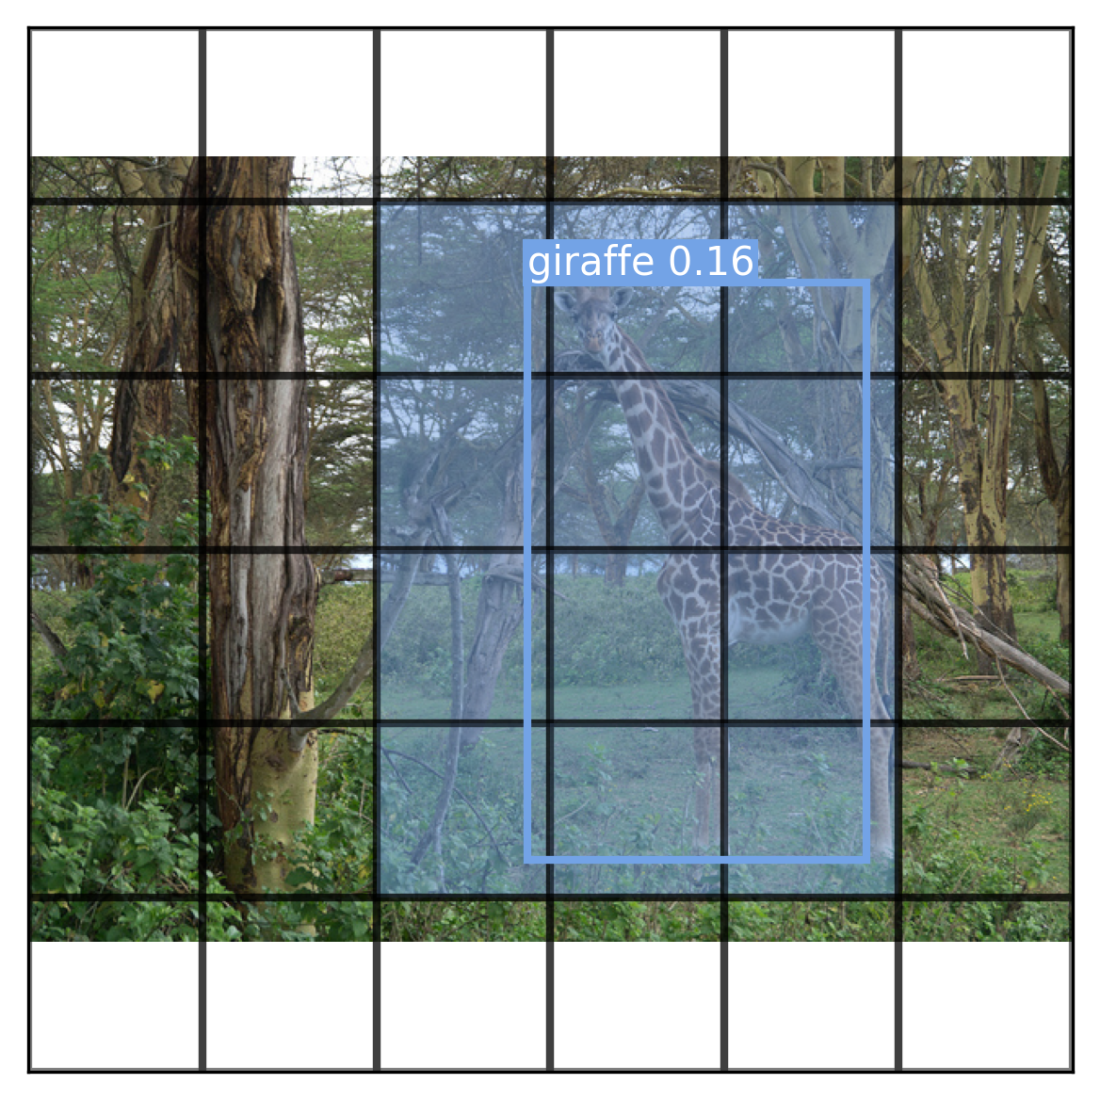
Predictions for our sample image.
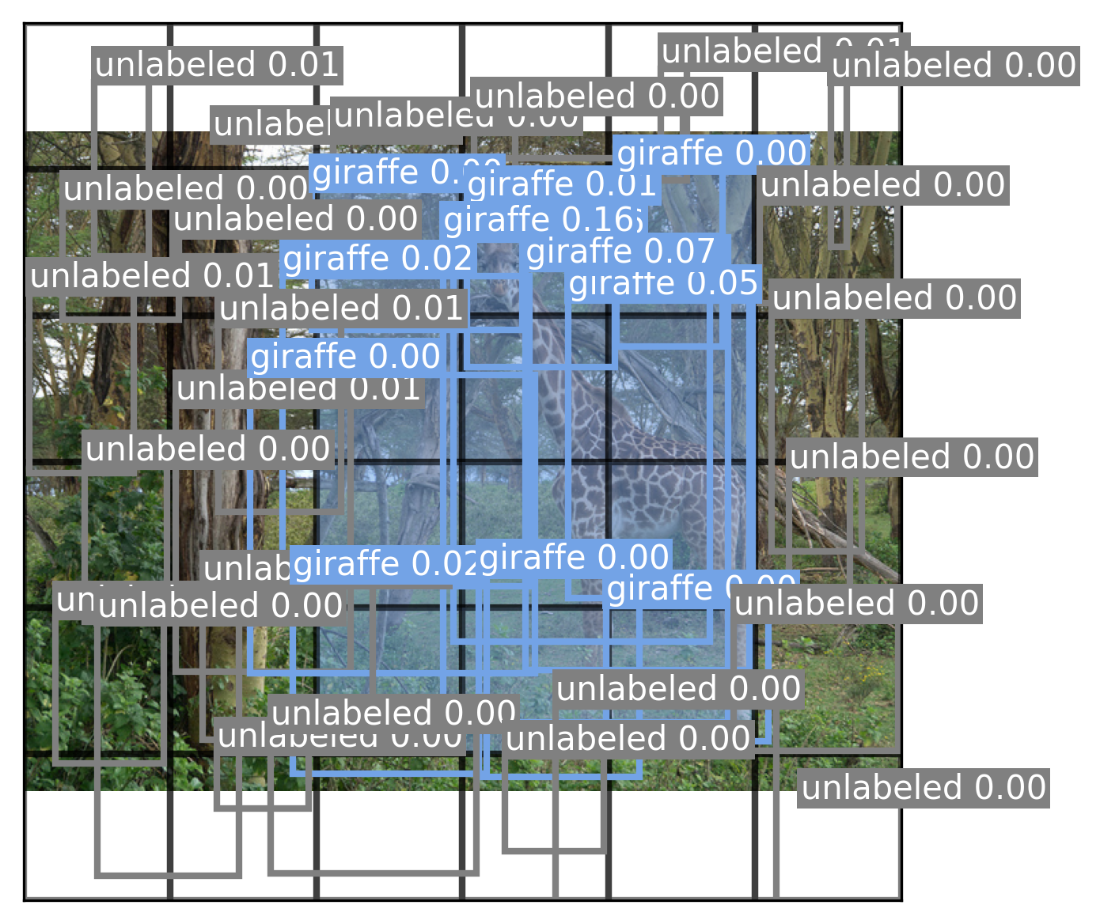
Every bounding box predicted by the YOLO model.
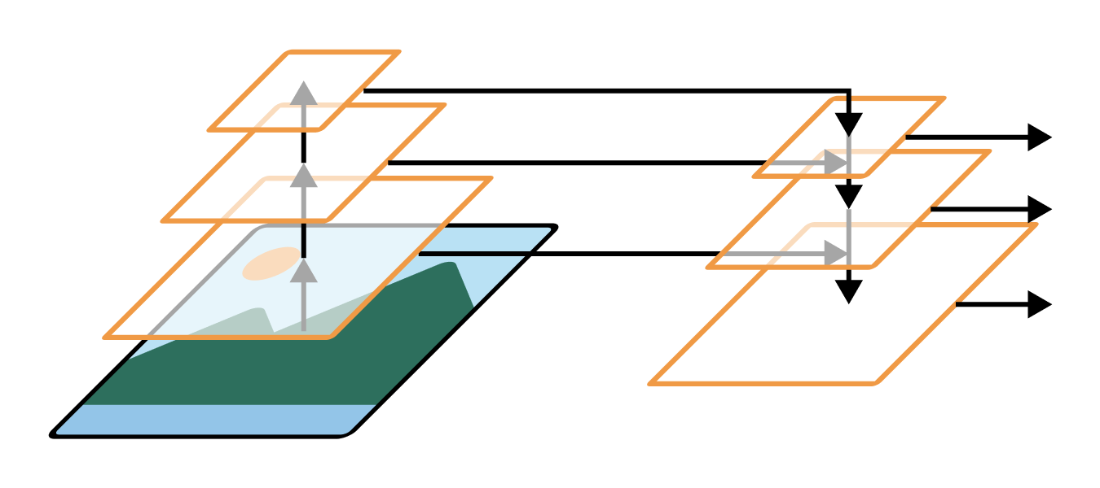
A feature pyramid network creates semantically interesting feature maps at different scales.
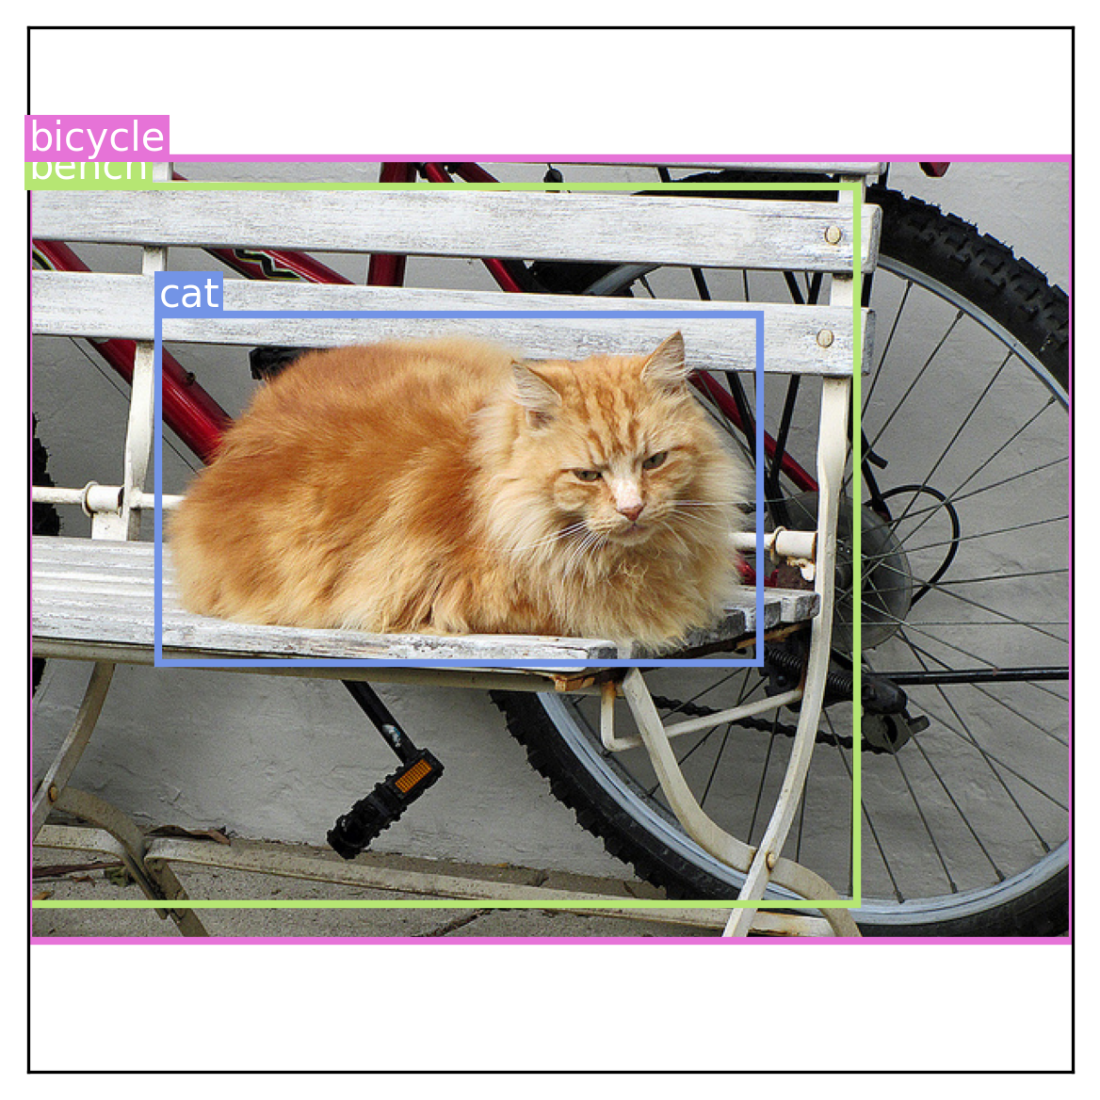
Predictions on a test image from the RetinaNet model.
Chapter summary
Object detection identifies and locates objects within an image using bounding boxes. It’s basically a weaker version of image segmentation, but one that can be run much more efficiently.
There are two primary approaches to object detection:
Region-based Convolutional Neural Networks (R-CNNs), which are two-stage models that first propose regions of interest and then classify them with a convnet.
Single-stage detectors (like RetinaNet and YOLO), which perform both tasks in a single step. Single-stage detectors are generally faster and more efficient, making them suitable for real-time applications (e.g., self-driving cars).
YOLO computes two separate outputs simultaneously during training – possible bounding boxes and a class probability map.
Each candidate bounding box is paired with a confidence score, which is trained to target the Intersection over Union of the predicted box and the ground truth box.
The class probability map classifies different regions of an image as belonging to different objects.
RetinaNet builds on this idea by using a feature pyramid network (FPN), which combines features from multiple convnet layers to create feature maps at different scales, allowing it to more accurately detect objects of different sizes.
FAQ
What is object detection and what can you do with it?Object detection locates and labels objects in an image by drawing bounding boxes around them. Typical uses include:
- Counting: how many instances of a class are present.
- Tracking: running detection frame-by-frame to follow motion.
- Cropping/region-of-interest: extracting relevant patches for downstream models (e.g., OCR).When should I use object detection instead of segmentation?Use detection when you don’t need pixel-precise object outlines. Compared to segmentation:
- Detection runs faster at inference time.
- Bounding boxes are far cheaper to label than per-pixel masks.
- If you only need object presence, counts, or coarse location, detection is usually preferable.What’s the difference between two-stage and single-stage detectors?
- Two-stage (R-CNN family): generate region proposals first, then classify/refine each proposal. Often more accurate but slower.
- Single-stage (YOLO, RetinaNet, SSD): directly predict boxes and classes in one pass. Much faster and more efficient, suitable for real-time and embedded scenarios.How do R-CNN two-stage detectors work, and what are their trade-offs?
- Stage 1: create thousands of object-like region proposals (early versions used Selective Search; Faster R-CNN uses a learned Region Proposal Network).
- Stage 2: classify each proposal and refine boxes; discard low-scoring regions.
- Trade-offs: strong results but computationally heavy (classifying thousands of patches per image); often unsuitable for real-time or constrained devices.How does the simplified YOLO model in the chapter make predictions?
- The image is divided into a grid (e.g., 6×6).
- At each grid cell, the model predicts: (x, y, w, h, confidence) for one box and a class-probability distribution over labels.
- x, y are the box center within the cell; w, h are relative to the image; confidence should be high when an object resides in that cell.How are COCO bounding boxes prepared for training?
- Boxes come as x, y, width, height from the image’s top-left corner.
- Coordinates are normalized to the [0, 1] range using image dimensions, enabling consistent handling across image sizes.
- During visualization, letterboxing-style padding aligns images into a unit square so boxes remain correct on display.How are YOLO training targets constructed for this model?
- Class target: a grid-sized map where cells overlapping an object are marked with that object’s label; the center cell also gets the label.
- Box target: for the cell containing a box’s center, store (x, y within cell, w, h) plus confidence=1; all other cells have confidence=0.
- Utility functions convert between image-relative boxes and grid-relative coordinates.What loss function is used to train the YOLO model?
- Box placement loss: sum of squared errors on center (x, y) and on sqrt-transformed width/height to balance small vs large boxes.
- Confidence loss: for empty cells target is 0; for object cells target is IoU between predicted and true box (encourages better localization).
- Heuristics: upweight box terms (×5) and downweight confidence on empty cells (×0.5); compute box losses only where objects exist.Why are early results low-confidence, and how can performance be improved?
- With few epochs and a reduced dataset, the model hasn’t learned consistent localization yet, so confidences are low.
- Improvements: train longer, use the full COCO set, apply data augmentation, handle overlapping boxes better, predict multiple boxes per cell, and/or use a finer grid.What is RetinaNet and how does a Feature Pyramid Network (FPN) help?
- RetinaNet is a single-stage detector that uses an FPN to build multi-scale, semantically rich feature maps.
- FPN upsamples deep features and fuses them with earlier, higher-resolution features via lateral connections, improving detection of small and large objects.
- Pretrained RetinaNet (e.g., via KerasHub) outputs boxes, confidences, and labels; using rel_xywh box format makes it easy to reuse your drawing utilities.
pro $24.99 per month
access to all Manning books, MEAPs, liveVideos, liveProjects, and audiobooks!

 Deep Learning with Python, Third Edition ebook for free
