1 Setting the stage for offline evaluations
Offline evaluations are introduced as a practical way to measure an AI model’s likely impact before it reaches users. The text argues that models can look strong in research or benchmarks yet still fail on messy real-world data, edge cases, system constraints, or product-specific goals. Because of that, evaluation is framed as essential to responsible AI development, helping teams catch weak candidates early and reduce the risk of harming user experience or product metrics.
The chapter then places offline evaluation inside the broader product development lifecycle. Models typically move from ideation to offline testing, then to online experimentation if results look promising, with offline work serving as a fast and inexpensive feedback loop. This stage relies on historical data, validation and holdout splits, and sometimes synthetic data, with metrics chosen to fit the task and product context. The text emphasizes that metric selection is not just technical but a product decision, since the right measure might be ranking quality, classification accuracy, groundedness, task success, diversity, or another signal depending on how the model is used.
Finally, the chapter shows how offline evaluations support iteration, monitoring, and experimentation, while also noting their limits. They can help narrow candidates for A/B tests, monitor production drift, and reveal failure patterns through canonical checks and deeper diagnostic analysis. But they cannot fully capture feedback loops, UX effects, or the true impact of live user behavior, so online testing remains necessary. The main takeaway is that strong offline evaluation builds a better foundation for deployment, but it works best as part of a balanced evaluation strategy involving production data, collaboration across teams, and real-world validation.
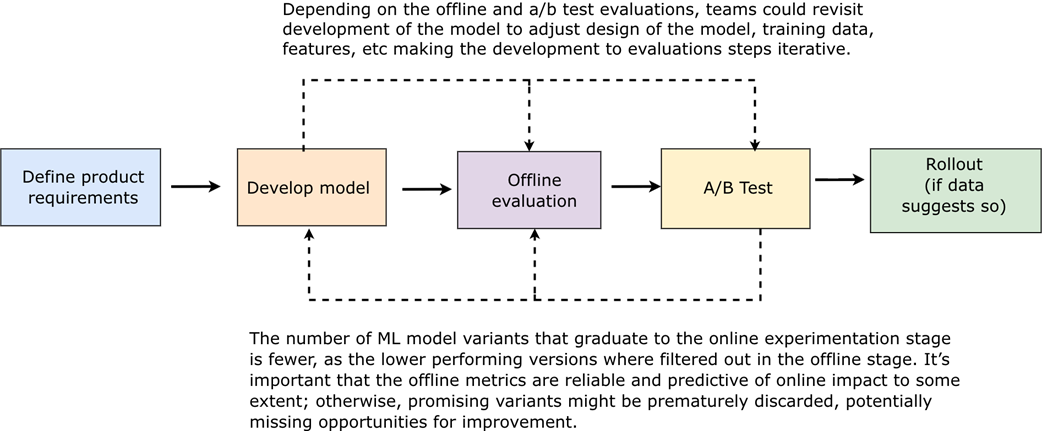
What the development lifecycle looks like in practice for a feature that relies on an AI model. The process moves left to right through five stages: defining product requirements, developing the model, offline evaluation, A/B testing, and a conditional rollout. However, it is rarely as linear as it appears. Notice that evaluation is not a single event: offline evaluation lets teams iterate quickly using historical data, catching problems cheaply before deployment, while the A/B test validates whether those improvements translate to real user impact. The final stage being conditional on data ('if data suggests so') reflects how seriously teams should treat online results as a go/no-go signal.
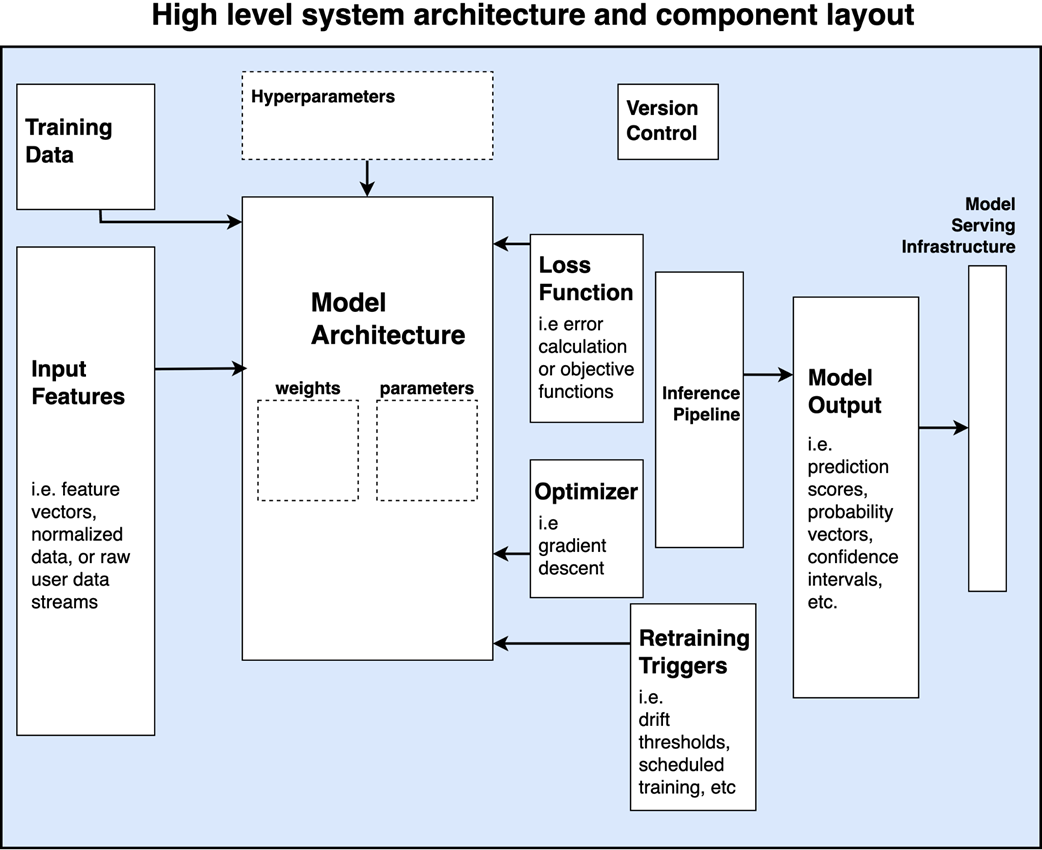
A high level conceptual overview of AI systems in an industry setting. The diagram illustrates the key components typically required to build and deploy an AI model. Starting from left to right, input features and training data are closely linked, as both are fed into the model. The model architecture, which is the core of the system, includes trainable weights and other configuration parameters. Hyperparameters, which are not trainable, are used to define the learning process. The loss function guides model training by measuring error, while the optimizer (e.g., gradient descent) updates the weights based on this feedback. Operational and deployment components include the inference pipeline, model output (such as prediction scores and confidence intervals), version control, and model serving infrastructure.
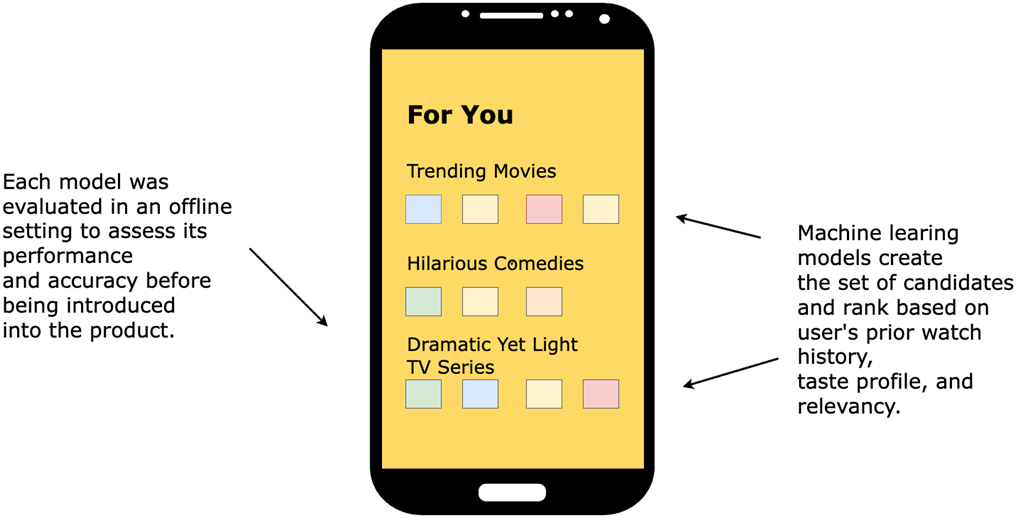
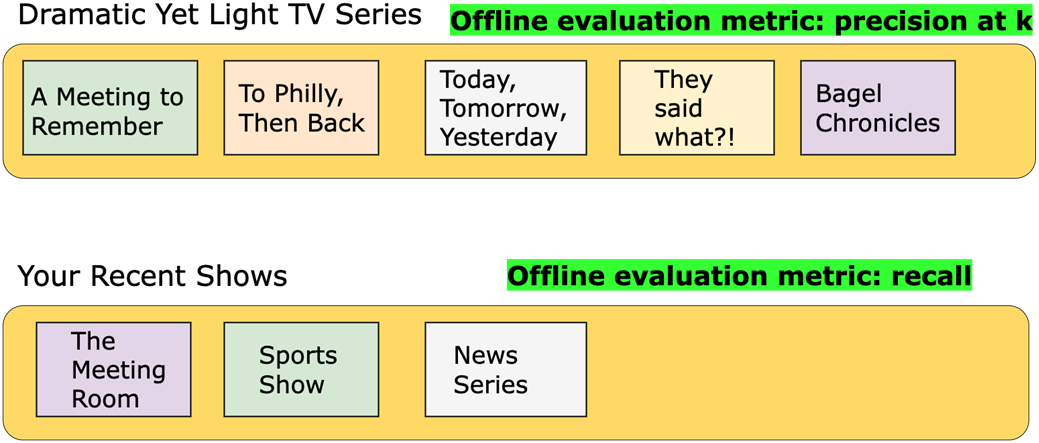
Streaming app utilizing machine learning models to recommend the most relevant content for a user to watch. Each model is evaluated offline using metrics that can assess accuracy, relevancy and overall performance of the items and rank produced by the model.
Differing offline metrics for each recommendation scenario. The Dramatic Yet Light Movies recommendation model uses Precision at K (P@K) to ensure that the top movies in the list are highly relevant movies for the user. The Your Recent Shows model relies on recall as the metric to optimize in an offline setting, as it focuses on ensuring the system retrieves all relevant past TV shows to give customers a complete and personalized experience.
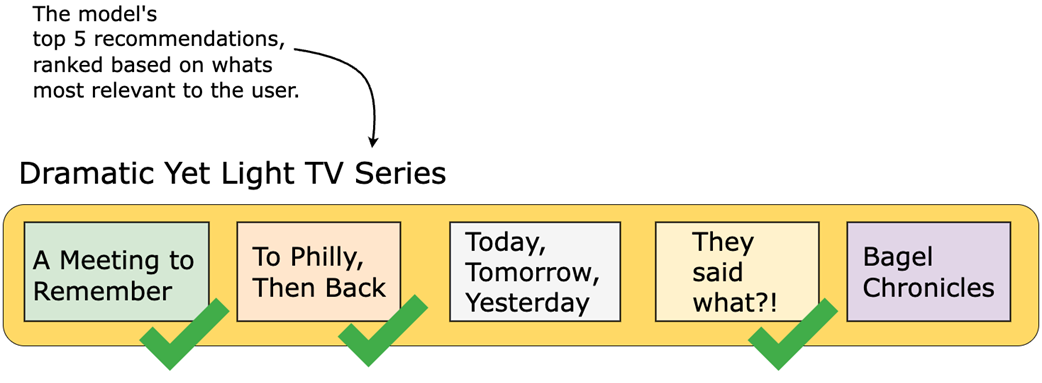
Which metric to optimize toward depends on the use case. Consider Precision@K, a common offline evaluation metric for ranking applications. In this example, five TV shows are recommended to a user, and three of them are considered relevant based on prior watch history or labeled preference data. The Precision at 5, or P@5, would be 3/5, or 60%.
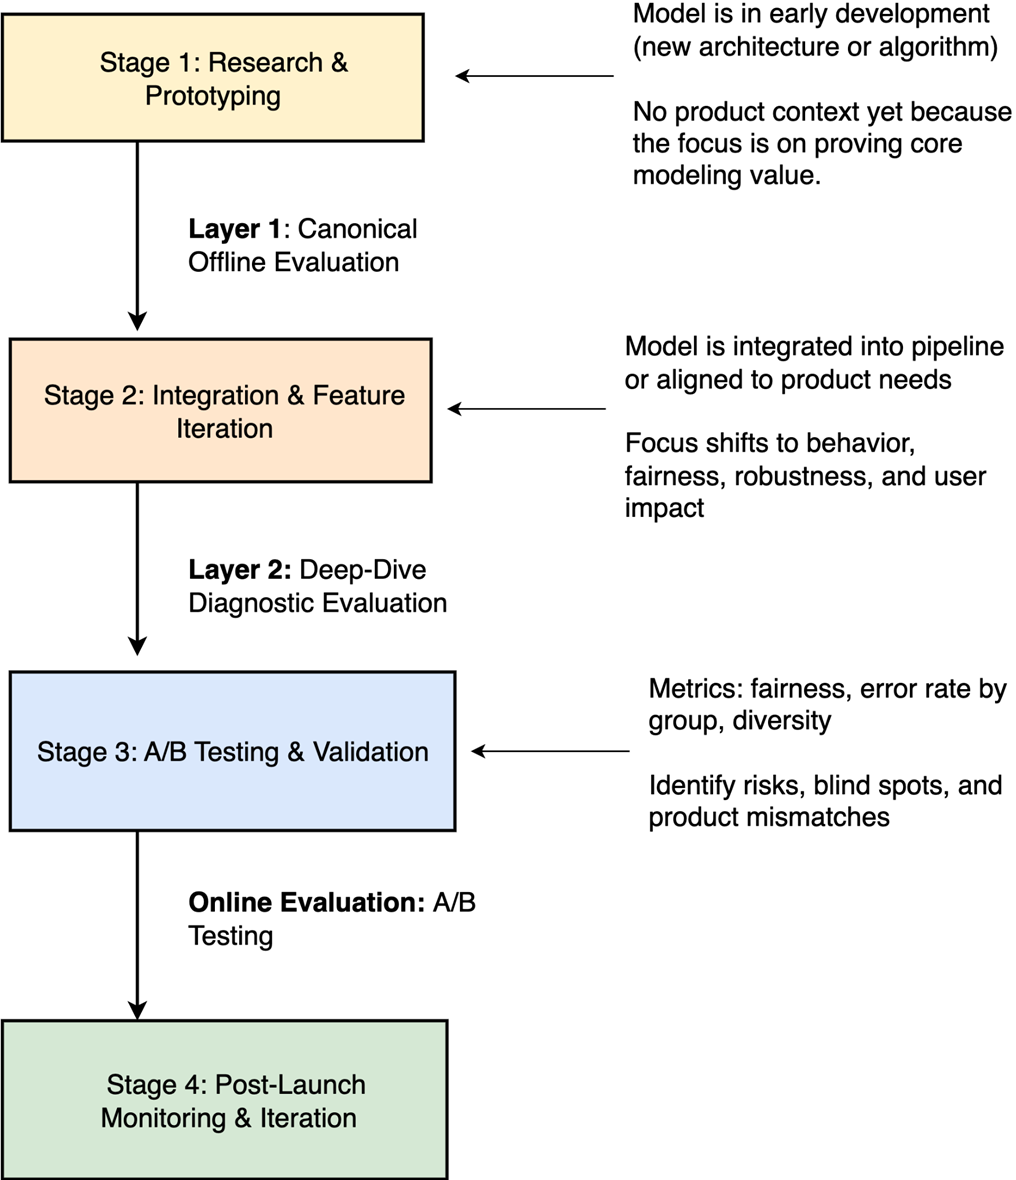
Illustrates how canonical offline evaluations, deep-dive diagnostics, and A/B testing each align with different stages of the model development lifecycle, from early prototyping to post-launch iteration. Each layer plays a distinct role in validating both the technical soundness and real-world impact of machine learning models.
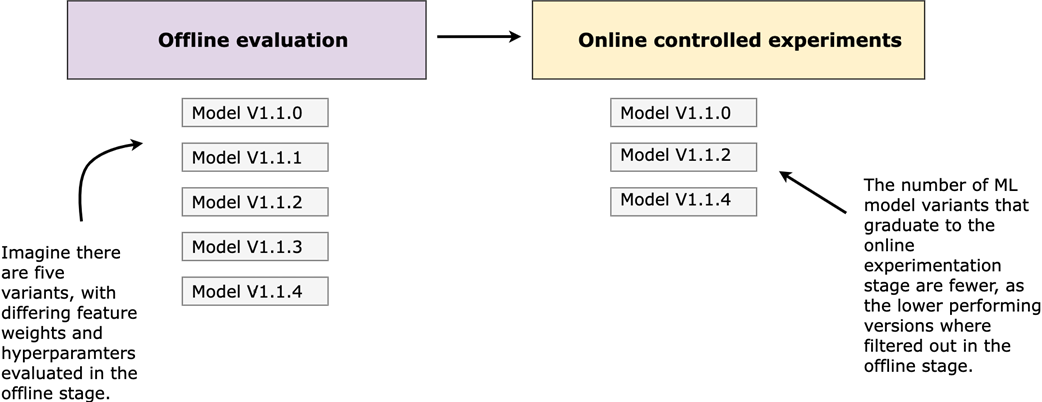
Leveraging offline evaluations to inform online experimentation strategy results in considerable optimizations. By reducing the number of model variants that graduate to the online experimentation stage, you're reducing the sample size for the A/B test, freeing up testing capacity for other A/B tests to run on the product and being more strategic with the changes you're exposing users to.
Summary
- Offline evaluations involve testing and analyzing a model's performance using historical or pre-collected data without exposing the model for real users to engage with in a live production environment.
- When iterating on a machine learning model, it's so important to gain as much insight into the impact or effect as possible before it's available in a product-user-facing setting. This is exactly what offline evaluations aim to do!
- The various offline metric categories and example metrics that ladder up to each category include Ranking Metrics and Classification Metrics.
- Recommender systems, search engines, fraud detection models, language translation systems, and predictive maintenance algorithms are typical real-world applications that benefit from offline evaluations. Offline evaluations allow such applications to be rigorously tested without exposing iterations to users, enabling teams to measure accuracy and relevancy before deploying changes to production.
- The more insight gained from an offline evaluation, the better decisions you make in the online controlled experiment phase.
- Offline evaluations become particularly powerful as a monitoring tool. By running your offline evaluation pipeline against freshly collected production logs on a regular cadence, you can track whether model quality is holding steady, improving, or declining without waiting for an A/B test to tell you something has gone wrong. The data comes from production, but the evaluation methodology remains offline.
- Correlating offline and online results enables more efficient model iterations by using offline evaluations to predict online performance, streamlining refinement and adjustments before exposing real users to the model changes.
- The product development lifecycle as it pertains to AI models and how offline evaluations are a key step in understanding impact and effectiveness. It's important to understand the complexities of integrating AI systems and to mitigate risks by using offline evaluations.

 AI Model Evaluation ebook for free