For much of machine learning’s history, efficiency was secondary because models were smaller and inference felt fast enough. That changed as modern large transformers grew dramatically in size and context length, turning inference into an infrastructure problem where latency, power, and memory bandwidth became the real limits rather than raw arithmetic throughput. The central lesson is that today’s systems are bottlenecked by moving data, not by doing math, so the cost of serving models now scales with bytes transferred per token.
Quantization is presented as the practical response because it directly attacks that dominant cost. By reducing weights and activations from floating point to lower-bit integer representations, it cuts memory footprint, bandwidth demand, and energy use without changing the model’s structure. The chapter argues that this works because neural networks are redundant and tolerant of bounded approximation: moderate reductions such as INT8 or INT4 often preserve quality surprisingly well, while still delivering major gains in throughput and deployment efficiency.
The chapter then explains the numerical shift behind quantization by contrasting floating point with integers. Floating point offers flexible scaling and broad range, but that flexibility comes with hardware and memory overhead that is often wasted during inference. Integers use a fixed grid with uniform spacing, giving up expressiveness in exchange for speed, density, and lower power. The key tradeoff is therefore not simply accuracy versus error, but how much range and precision are truly needed to achieve sufficient quality at minimum energy.
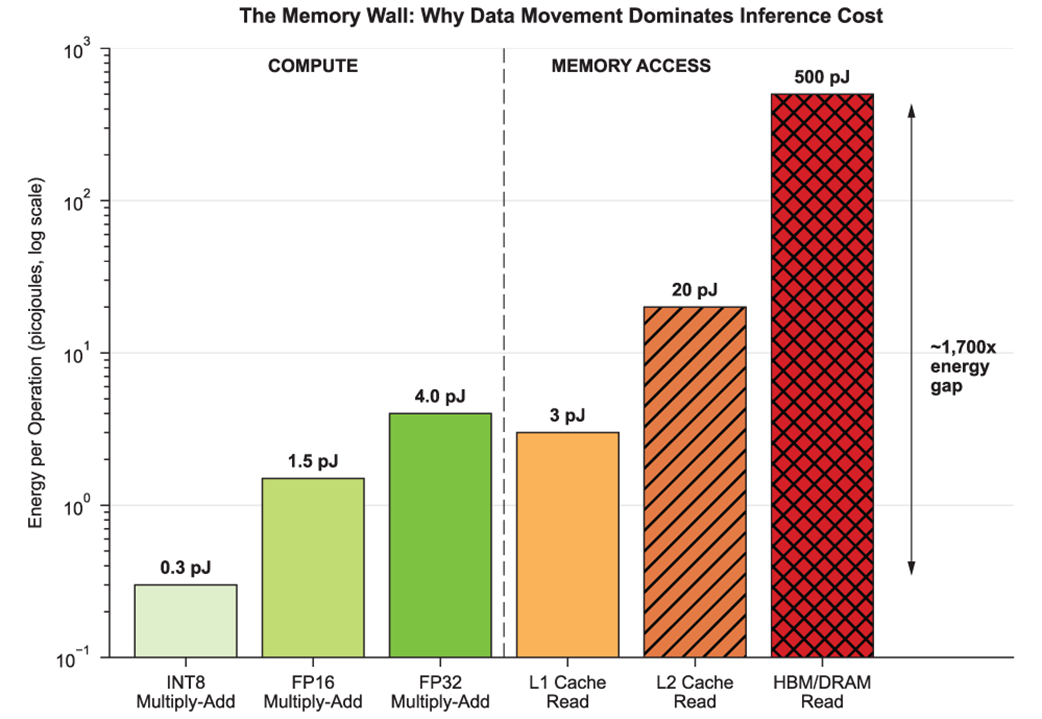
Fetching data from HBM costs roughly 1,700× more energy than an INT8 multiply-add. This gap explains why inference systems are bottlenecked by memory, not compute.
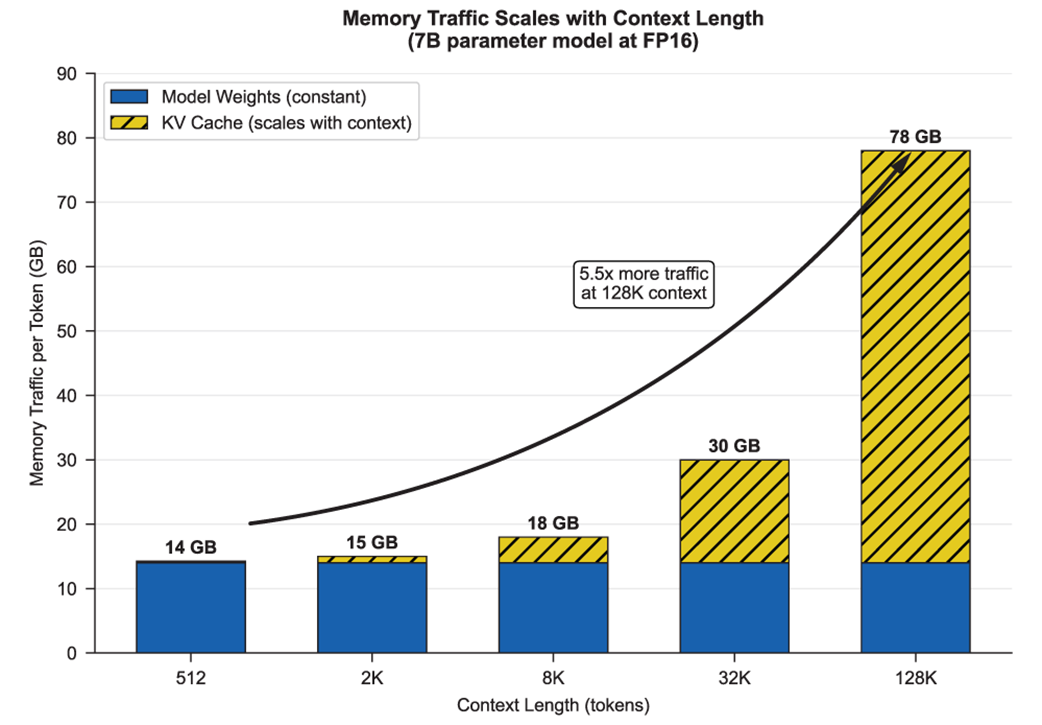
Memory traffic per token as context length grows. Model weights (filled) stay constant, but the KV cache (hatched) scales linearly with context. At 128K tokens, total memory traffic reaches 78 GB per token—5.5× more than at 512 tokens.
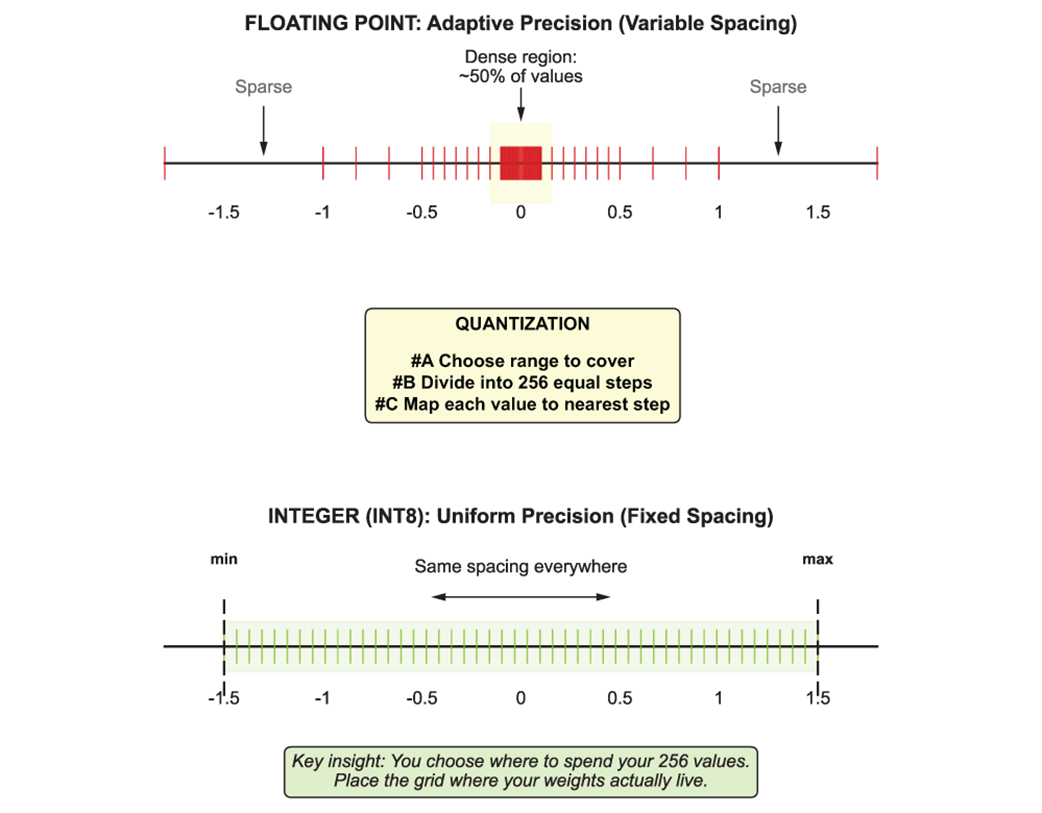
Floating point concentrates precision near zero (top), leaving large values sparsely represented. Integers use uniform spacing across your chosen range (bottom). Quantization is the act of deciding where to place that fixed grid.
Summary
Modern LLM inference is constrained by memory bandwidth and power consumption, not raw compute; a 7B parameter model moves roughly 15 GB through memory for every token generated, consuming nearly 2 joules of energy per token.
Lowering precision from 16-bit floats to 8-bit or 4-bit integers cuts memory footprint, bandwidth, and energy in roughly the same proportion as the bit reduction; that direct, linear scaling is what makes quantization the practical lever rather than a theoretical one.
Neural networks tolerate quantization because they encode directions and correlations rather than exact values; their inherent redundancy absorbs the bounded approximation error that lower precision introduces.
The core tradeoff in quantization is range versus resolution: integers force you to choose a fixed grid where every number must fit, unlike floating point which auto-scales at the cost of hardware complexity.
FAQ
What is the main efficiency problem facing modern large language models?The main problem is that inference is limited by memory movement and power, not by raw compute. GPUs often sit underutilized because reading weights and KV cache data from memory is the dominant cost.Why does quantization help reduce inference cost?Quantization reduces the number of bits used to represent weights and activations, which lowers memory footprint, memory bandwidth usage, and energy per token. It attacks the dominant bottleneck: data movement.Why is memory access more expensive than arithmetic in modern hardware?Arithmetic operations like multiply-adds are relatively cheap, while moving data through memory hierarchy is much more expensive. Accessing DRAM or HBM can cost orders of magnitude more energy than an integer or floating-point operation.How large is the energy gap between HBM access and INT8 computation?In the chapter’s example, fetching data from HBM can cost roughly 1,700 times more energy than an INT8 multiply-add. This huge gap is why inference is memory-bound rather than compute-bound.What happens to the memory cost of a 7B model at different precisions?A 7B-parameter model is about 28 GB in FP32, 14 GB in FP16, and 7 GB in INT8. Lower precision directly reduces the storage and traffic required to run the model.Why does the KV cache matter so much during inference?The KV cache stores attention keys and values for all previously generated tokens, and it must be reread at each step. As context length grows, KV cache traffic grows linearly and can dominate total memory movement.Why is quantization considered a better practical response than waiting for newer hardware?Hardware improvements mostly favor compute throughput, not energy per byte moved. Since inference cost is driven by memory traffic, simply waiting for faster GPUs does not solve the core problem as effectively as reducing precision does.Does quantization always hurt model quality significantly?No. Neural networks are redundant and can tolerate small bounded perturbations. At moderate bit widths, especially 8-bit and often 4-bit with good methods, quality degradation is usually gentle rather than catastrophic.What is the difference between floating point and integer representations?Floating point uses a mantissa and exponent to represent a wide range of magnitudes with variable precision. Integers use a fixed grid of evenly spaced values, which is simpler, more efficient, and cheaper in hardware.What is the central tradeoff in quantization?The central tradeoff is range versus resolution. Floating point preserves both at a higher system cost, while integers force you to choose how much range you need and how much precision you can afford to lose.
pro $24.99 per month
access to all Manning books, MEAPs, liveVideos, liveProjects, and audiobooks!

 Quantization and Fast Inference ebook for free