6 Reinforcement Learning
Reinforcement learning in RLHF is presented as the mechanism that turns human or model-based feedback into parameter updates: a policy generates completions, a reward model scores them, and the optimizer nudges the model toward outputs that earn higher reward while staying close to a reference model through a KL penalty. The chapter emphasizes that, although the mathematics can be intricate, the practical success of these systems still depends heavily on the quality of the data and the training signals fed into them.
The core technical story is policy-gradient learning. The text builds up from the idea that updates should increase the probability of actions with positive advantage and decrease it for negative advantage, then derives the standard log-probability gradient using trajectory factorization and the log-derivative trick. It explains why raw returns are noisy, how baselines reduce variance, and how advantage estimates such as Monte Carlo returns, TD residuals, and generalized advantage estimation provide better credit assignment. REINFORCE, RLOO, and PPO are used to show the progression from simple Monte Carlo updates to clipped, more stable objectives; PPO in particular adds a learned value function and ratio clipping to prevent overly large policy shifts.
The later parts broaden the view to modern RLHF practice. GRPO removes the value network and uses group-relative advantages across multiple completions per prompt, GSPO moves importance sampling from token level to sequence level to reduce instability, and CISPO clips importance weights instead of the surrogate objective so every token still receives gradient signal. The chapter also stresses implementation realities: how to aggregate losses across token and sequence lengths, when to use on-policy versus asynchronous systems, why truncated or mismatched sampling can destabilize training, and how details like KL placement, value initialization, reward normalization, and length handling can matter as much as the algorithmic choice itself.
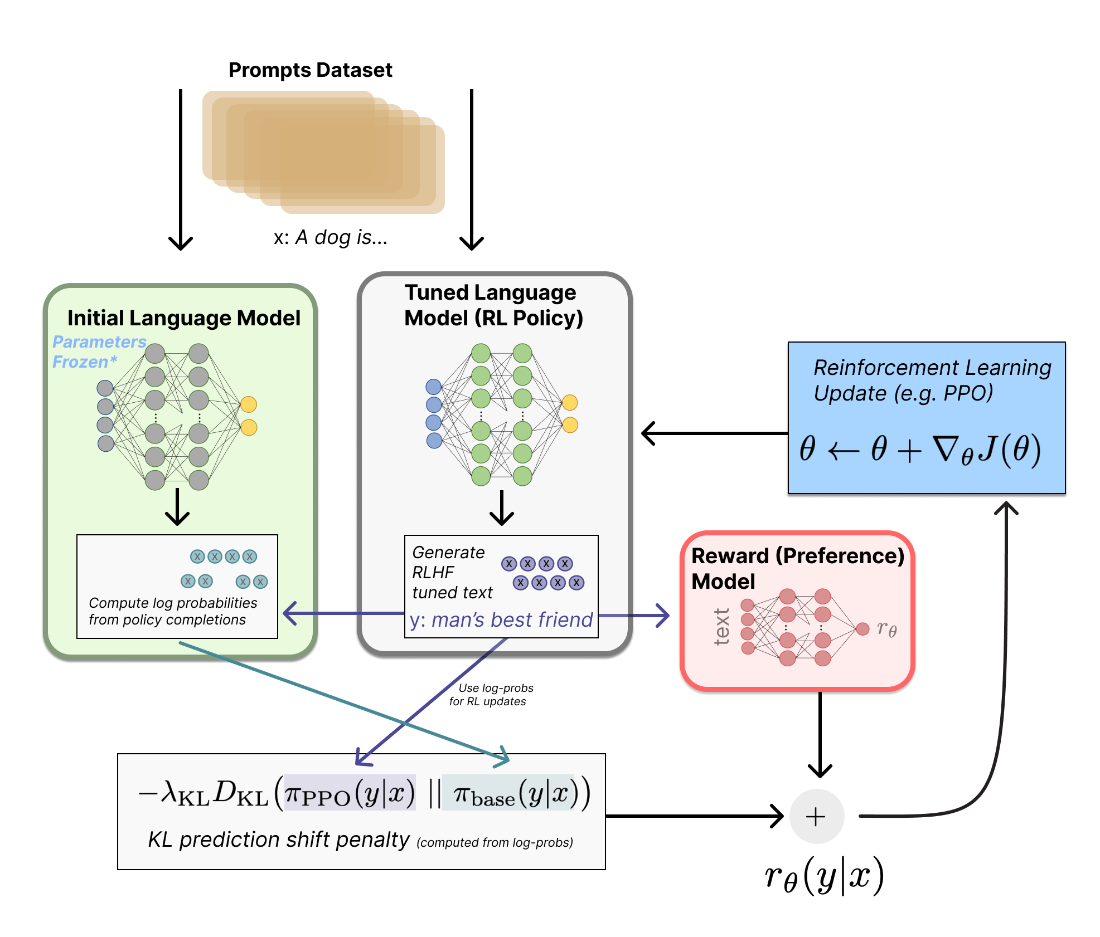
Overview of the RLHF training loop. A prompt from the dataset is passed to the tuned policy, which generates a completion. The reward model scores this completion, while the frozen initial model (typically the instruction-tuned model before RL) computes log probabilities on the same text to calculate a KL penalty that prevents excessive drift. The combined reward signal then drives a reinforcement learning update to the policy parameters.
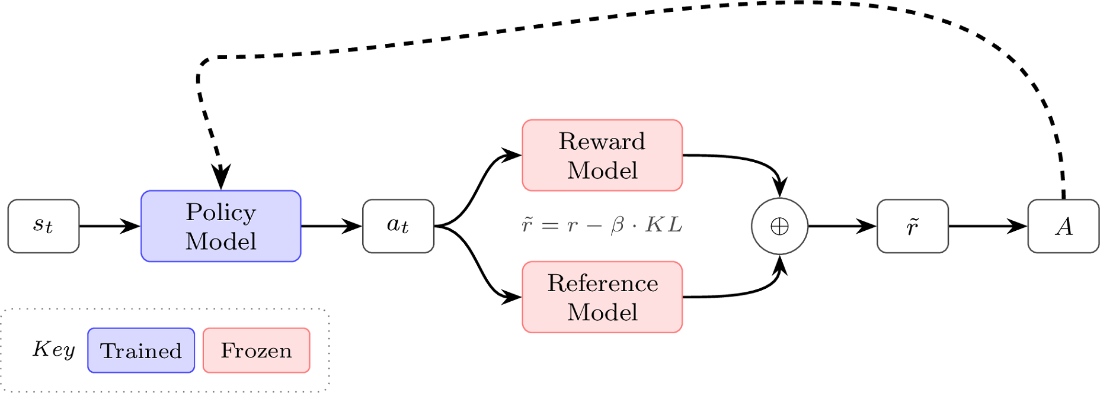
Basic REINFORCE architecture for language models. The shaped reward combines the reward model score with a KL penalty from the reference model. We build on this structure throughout the chapter.
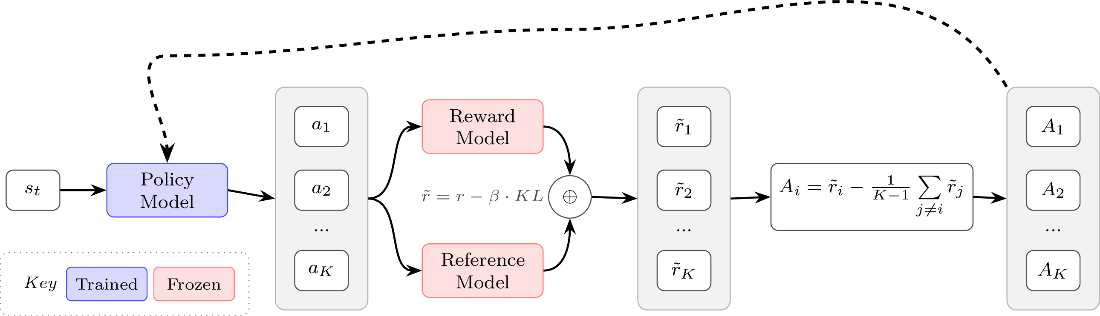
REINFORCE Leave-One-Out (RLOO) architecture. Multiple completions per prompt provide a leave-one-out baseline for advantage estimation without learning a value function.
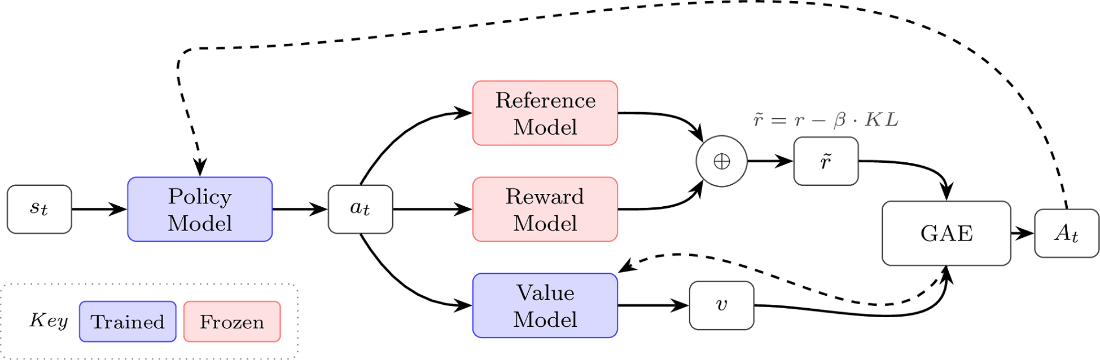
PPO framework. A learned value function enables Generalized Advantage Estimation (GAE) for per-token advantages, used with a clipped surrogate objective.
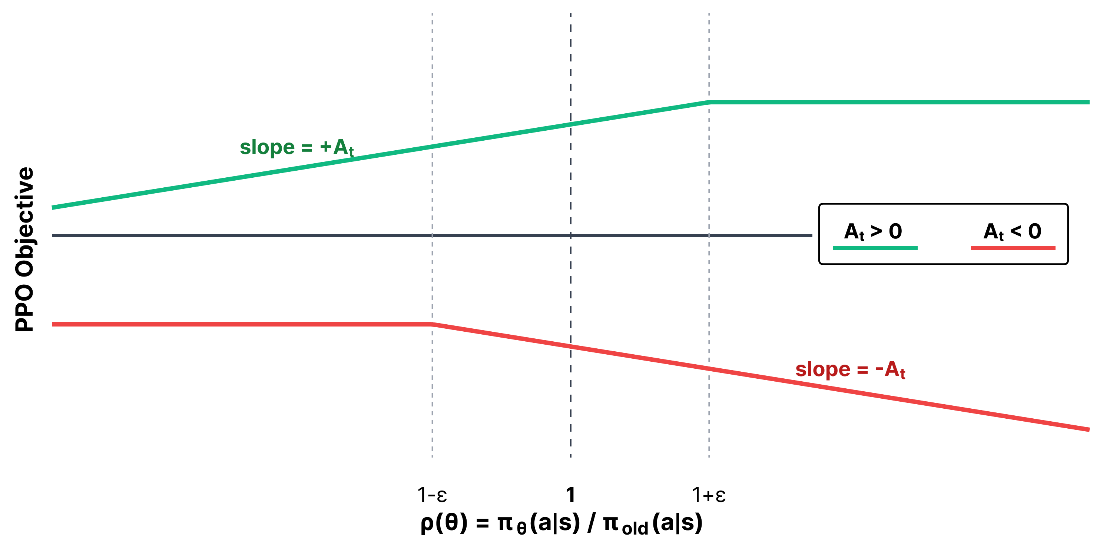
Visualization of the different regions of the PPO objective for a hypothetical advantage. The “trust region” would be described as the region where the policy ratio \(\rho\) is within \(1\pm\varepsilon\).
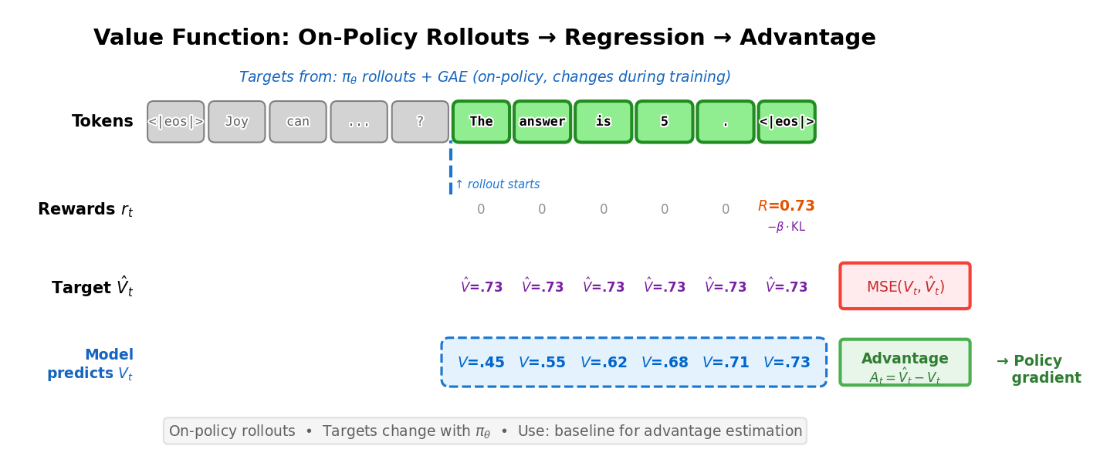
Value function training uses on-policy rollouts to compute targets. The model predicts \(V_t\) at each token, which is trained via MSE against the target return \(\hat{V}_t\). The advantage \(A_t = \hat{V}_t - V_t\) then weights the policy gradient update.
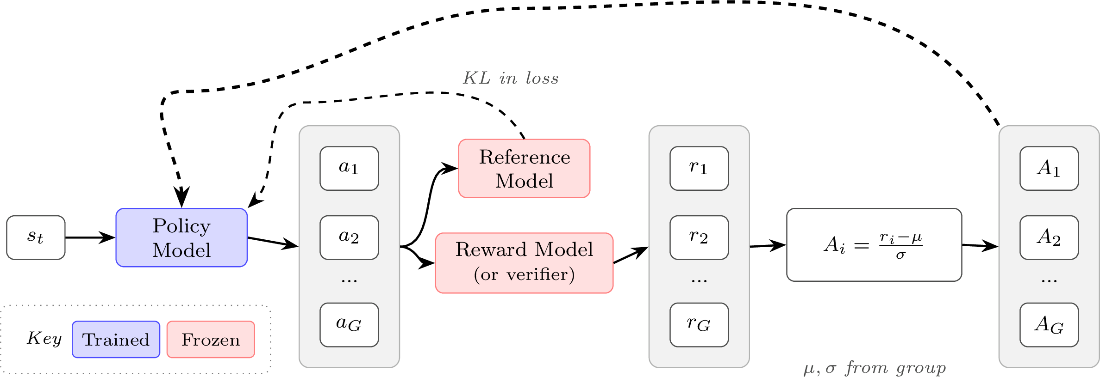
GRPO architecture. Advantages are normalized relative to the group mean and standard deviation. The KL penalty is applied directly in the loss rather than shaping the reward.
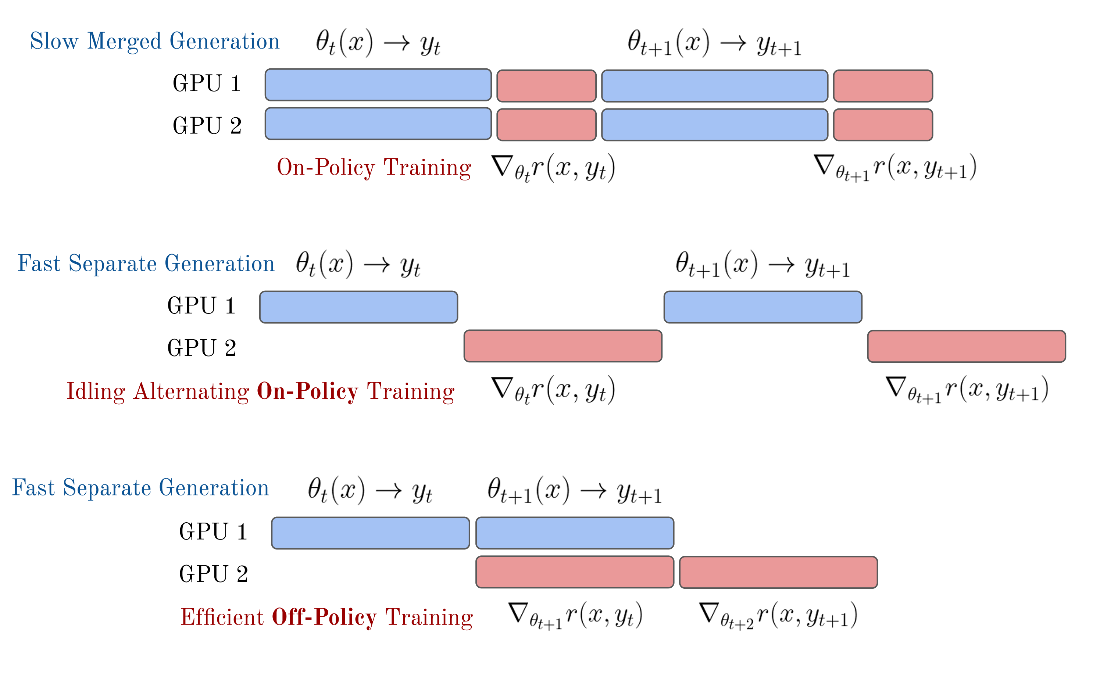
A comparison of the generation-update phases for synchronous or asynchronous RL training following Noukhovitch et al. 2024.
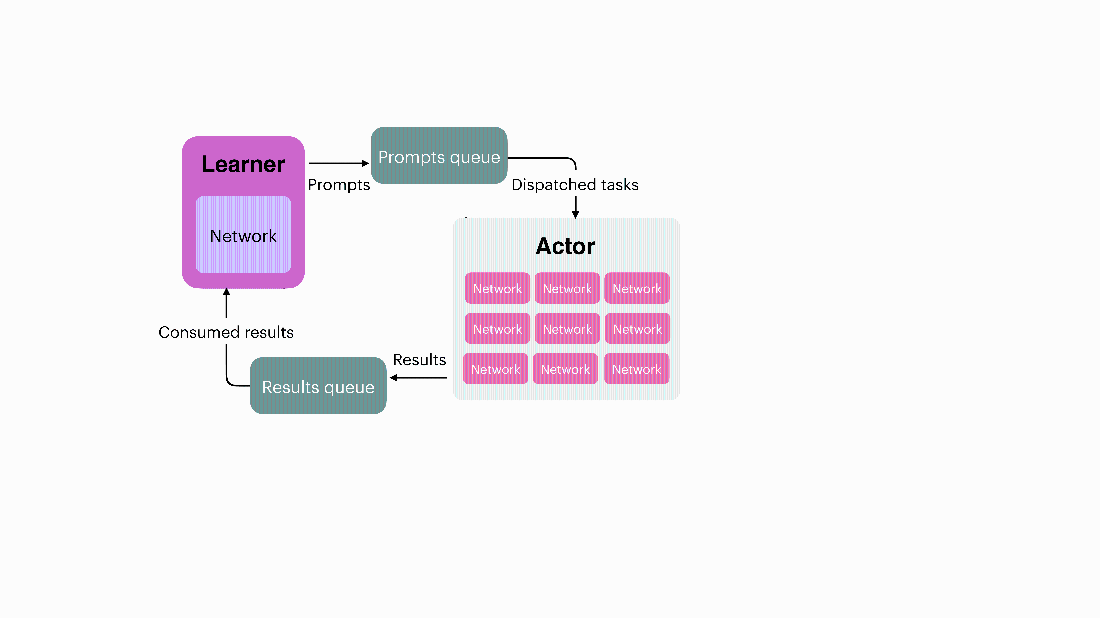
An example distributed RL system, where two queues are managed to pass data to the learner and actor GPUs, which can both be synchronized with a distributed computing library such as Ray. Olmo Team 2025, license CC-BY.
Summary
- The RL stage of RLHF closes the loop: the policy generates completions, the reward model scores them, and policy gradient algorithms update the model to produce higher-reward outputs. This is where the preference signal captured by the reward model is translated into model behavior.
- Policy gradient algorithms derive a gradient of expected reward with respect to model parameters, enabling direct optimization of the policy. Practical algorithms then reduce the variance of this gradient estimate through baselines – reference values that measure how good an action is relative to what’s typical – and advantage functions.
- The chapter covers several algorithms, each with different trade-offs and focuses:
- REINFORCE / RLOO: The simplest approaches – REINFORCE uses Monte Carlo return estimates with a batch-level baseline, while RLOO uses a leave-one-out baseline across multiple completions per prompt. Neither requires a learned value function.
- PPO: Uses importance sampling with clipped surrogate objectives and a learned value function for per-token advantage estimation via GAE. Dominated early RLHF but requires more memory and implementation complexity.
- GRPO: Replaces the learned value function of PPO with group-relative advantage normalization across multiple completions per prompt. Popular for reasoning tasks after DeepSeek R1’s release.
- GSPO / CISPO: Cutting edge algorithms designed for numerical stability with large-scale models, which modify how importance sampling is applied in modern RL. GSPO uses a single sequence-level importance ratio (as per-token ratios can get clipped regularly), while CISPO clips the importance weights themselves rather than the objective, ensuring every token still receives a gradient signal.
- Implementation details such as loss aggregation (per-token vs. per-sequence), clipping strategies, value network initialization, and handling truncated generations all affect stability and final model quality.
- Asynchronous training – where generation and gradient updates run on separate systems that may hold different model weights – is crucial to modern RL infrastructure for LLMs and introduces distribution mismatch that importance sampling (and other techniques) must correct for.
- Generalized Advantage Estimation (GAE) reduces variance in PPO’s policy gradient updates by blending multi-step temporal difference (TD) residuals, though newer value-function-free methods like GRPO and RLOO are making it less central to modern LLMs.
- The same policy gradient algorithms covered here form the backbone of reasoning training (chapter 7), where they are applied at larger scale with verifiable rewards rather than learned reward models.

 Reinforcement Learning from Human Feedback ebook for free
