3 Improper data type usage
This chapter surveys common data type pitfalls in PostgreSQL and how they translate into incorrect results, unexpected behavior, and maintenance headaches. The overarching guidance is to pick types that encode the true semantics of your data and enable correct computations, rather than relying on defaults or SQL-Standard curiosities that look convenient but hide sharp edges. The discussion spans time-related types, character types, monetary values, surrogate identifiers, and semi-structured data, offering practical replacements and patterns that are safer, clearer, and no slower in practice.
For temporal data, the chapter shows how “naive” timestamps (TIMESTAMP without time zone) yield wrong durations across time zones and daylight saving changes, and how even standardizing on a single zone doesn’t fix DST edge cases. The remedy is to store moments in time with TIMESTAMPTZ, which uses the same storage size, supports accurate arithmetic, and can be displayed in any zone when needed; you can always extract just the time for presentation. TIME WITH TIME ZONE (TIMETZ) and CURRENT_TIME are discouraged because “time of day” without a date lacks the context required for math and consistency; prefer timestamps and derive time views as needed.
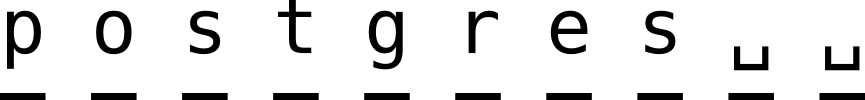
Beyond time, fixed-length CHAR(n) introduces trailing-space semantics, silent truncation on casts, wasted storage, and awkward pattern matching; VARCHAR(n) adds brittle limits without performance or storage gains and can also truncate silently on casts. Prefer TEXT and, if necessary, enforce length with CHECK constraints or a DOMAIN. MONEY is locale-dependent, rounds away sub-cent units, and accepts dubious inputs; use NUMERIC/DECIMAL and store currency in a separate column, avoiding floating-point types. SERIAL/BIGSERIAL create permission and cloning traps around sequences; use SQL-standard identity columns instead, and generate gapless sequences in the application if legally required. Finally, XML is verbose, fragile, hard to compare or index, and fussy about encodings; choose JSON/JSONB for compactness, performance, and indexability. The consistent theme: pick types that preserve meaning, support correct operations, and simplify your system over time.
String padding with CHAR(10)
Summary
- There is no benefit to using
TIMESTAMP (WITHOUT TIME ZONE), as it can lead to time calculation errors due to lack of time zone and DST context.TIMESTAMP WITH TIME ZONEis the proper data type for recording timestamps as specific moments in time. -
TIMETZandCURRENT_TIMEhave questionable usefulness because time zones have no meaning without the context of dates. Again, it is preferable to useTIMESTAMPTZeven if we don’t need to display the date part of the timestamp. -
MONEYdoesn’t store which currency, it suffers from a limited and flawed implementation, and should be avoided in favor of usingNUMERICor other number formats that can accurately store exact values, potentially in conjunction with storing the currency as a separate column. - The two serial types
SERIALandBIGSERIALhave been effectively superseded by identity columns, which have more predictable behavior when it comes to role ownership and use of sequences, and clarity regarding which table the sequence belongs to. - You don’t save storage space by using the limited character types
CHAR(n)andVARCHAR(n), and the whitespace stored withCHAR(n)can be detrimental to performance. Additionally, you run the risk of running into SQL quirks and painting yourself in a corner with maximum lengths —TEXTis the better choice. -
XMLis a terrible choice for document storage, unless you’re just copying immutable XML data inside the database — if you intend to query/manipulate the data, you should useJSON(B).

 PostgreSQL Mistakes and How to Avoid Them ebook for free
