3 Scaling up: from one block to many
The chapter explains how CUDA scales from one block to many so a GPU kernel can process arrays much larger than the 1,024-thread limit of a single block. The key idea is to keep the simple “one thread handles one element” model, but distribute those threads across multiple blocks and let the GPU schedule the blocks independently. A helpful mental model is that a grid is the whole launch, blocks are the groups that work together, and threads are the individual workers doing the actual computation.
Once work spans multiple blocks, each thread must compute a unique global index instead of relying on threadIdx.x alone, since that number repeats in every block. The chapter introduces the standard formula blockIdx.x * blockDim.x + threadIdx.x, which combines a thread’s position within its block with the block’s offset in the grid. It also stresses that blocks may run in any order, so code must not depend on one block finishing before another, and that race conditions appear if multiple threads write to the same location without atomic operations.
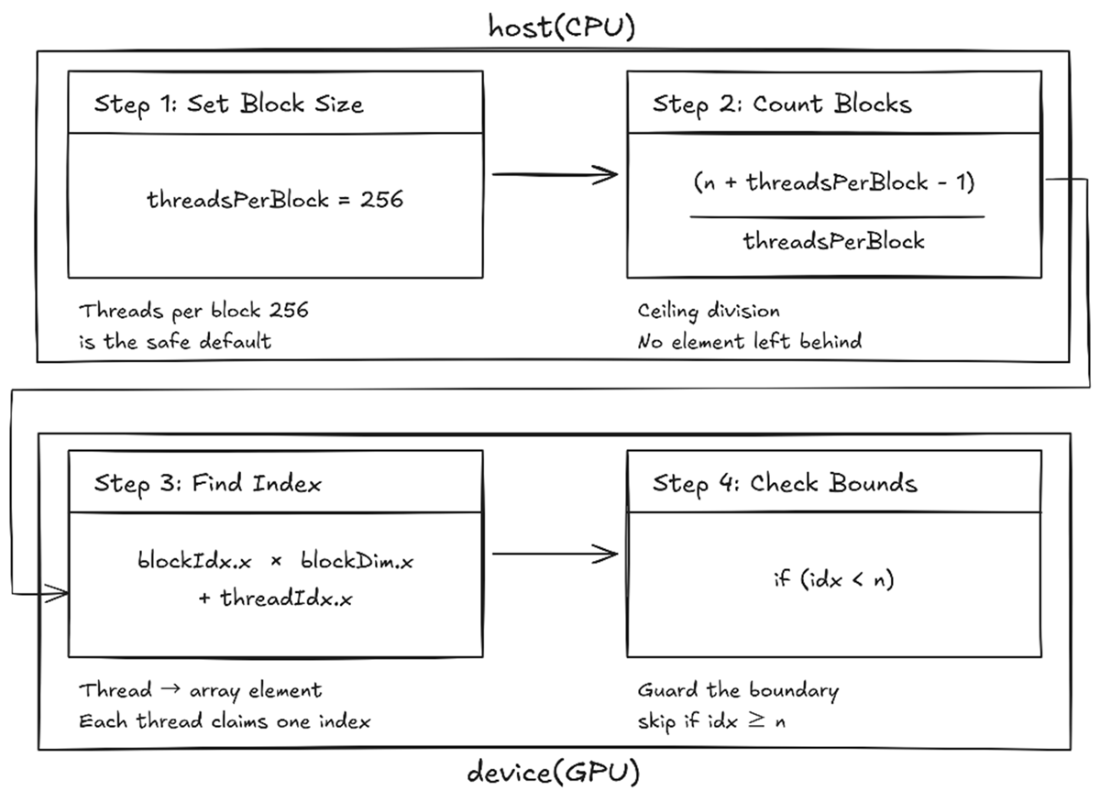
The rest of the chapter gives a practical recipe for launching correct 1D kernels: choose a block size, compute the number of blocks with ceiling division, calculate the global index inside the kernel, and guard work with if (idx < n) so extra threads do not access memory out of bounds. It recommends 256 threads per block as a strong default because it aligns with the GPU’s 32-thread warp size and usually avoids wasted lanes. The chapter closes by showing how these ideas fit into a complete CUDA program and by highlighting common mistakes such as using the wrong index, truncating the block count, or swapping the launch arguments.
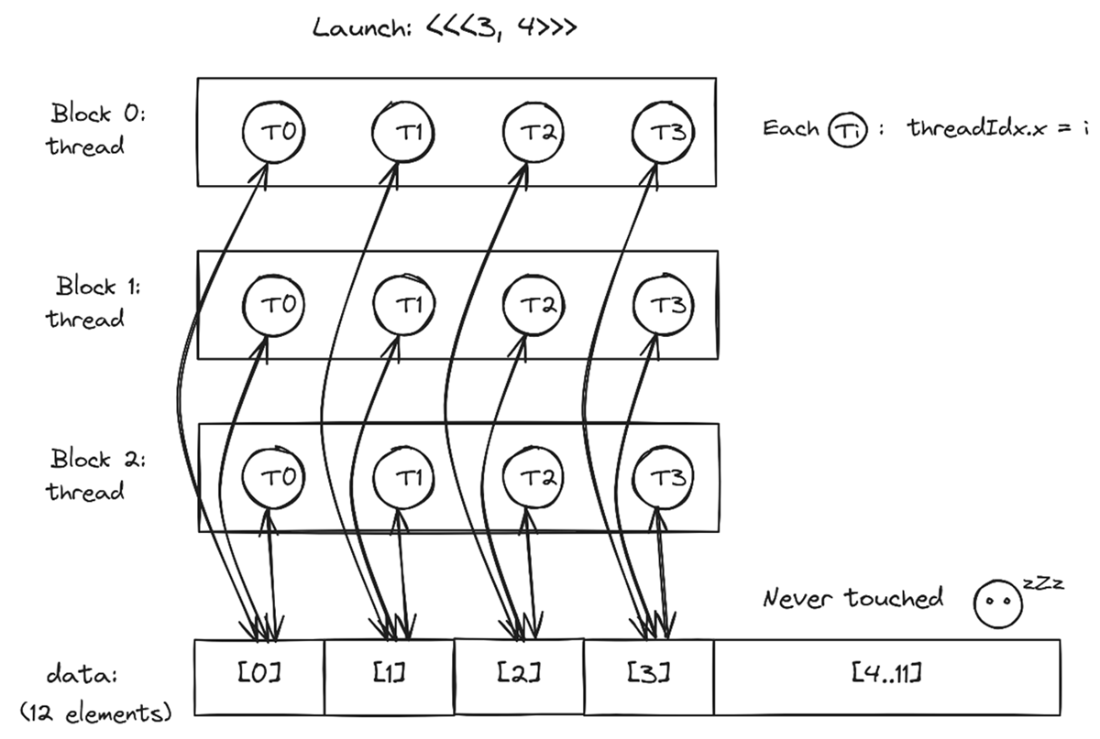
Launching <<<3, 4>>>: 12 threads, but only 4 elements touched. With 3 blocks of 4 threads each, every thread uses only threadIdx.x, so all three blocks target the same 4 elements (data[0..3]), leaving data[4..11] untouched. To reach the full array, each thread needs to factor in its block index too.
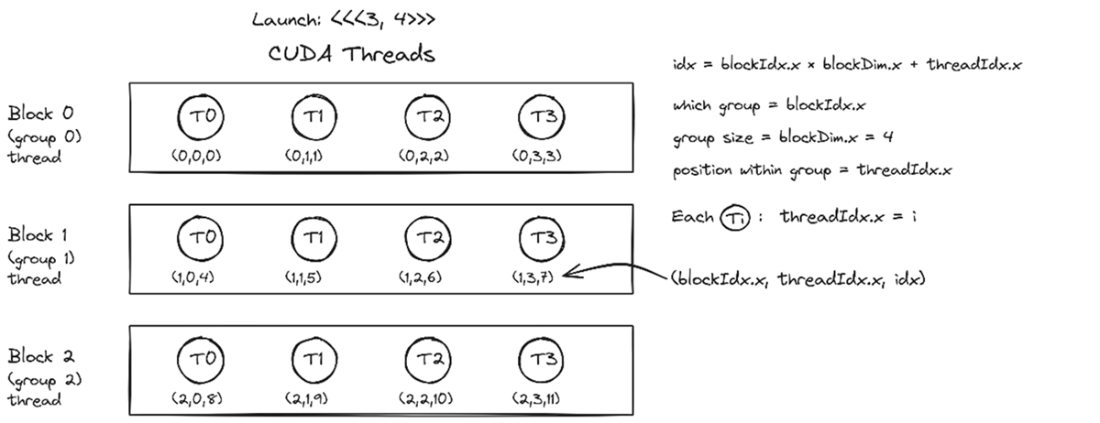
Global indexing: no two threads share the same index. By combining blockIdx.x, blockDim.x, and threadIdx.x, each thread gets a unique global index: Block 0 owns 0–3, Block 1 owns 4–7, and Block 2 owns 8–11.
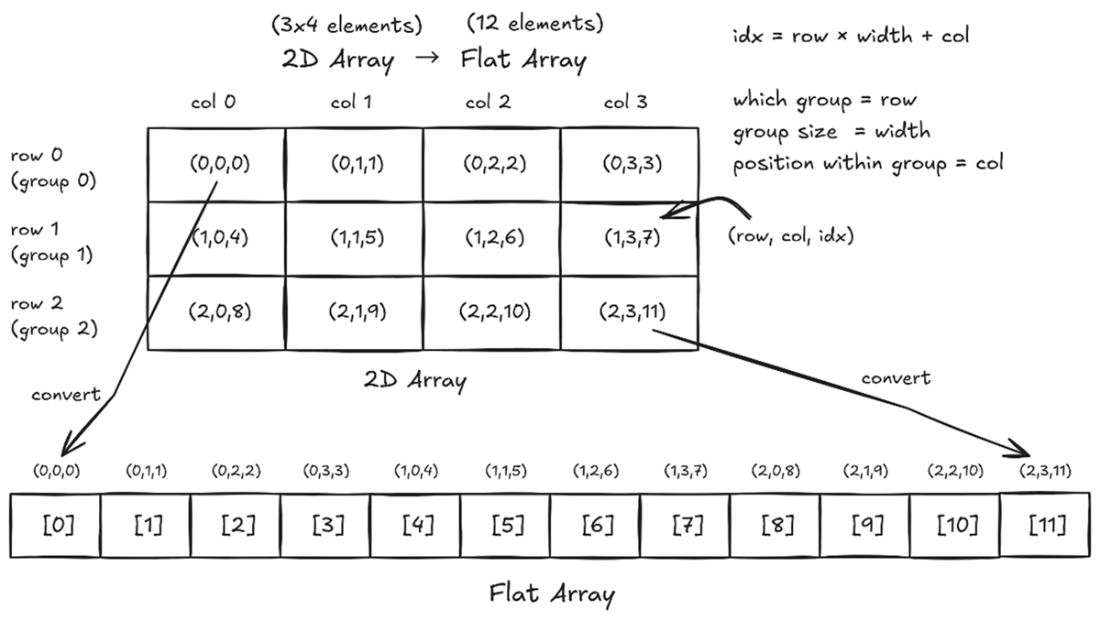
Row-major flattening: laying out a 2D array in a 1D flat array one row after another, the way C and CUDA store 2D arrays. Each element's flat index is computed as row × width + col: row 1, col 3 becomes index 7, and row 2, col 0 becomes index 8. The 2D structure stays in your head; the memory stays flat.
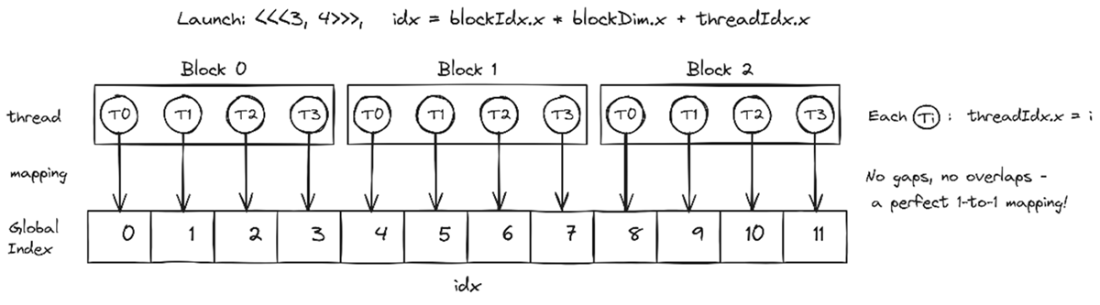
A perfect 1-to-1 mapping: one thread per element, no gaps, no overlaps. With <<<3, 4>>> and idx = blockIdx.x × blockDim.x + threadIdx.x, each of the 12 threads lands on exactly one element: Block 0 covers 0–3, Block 1 covers 4–7, and Block 2 covers 8–11.
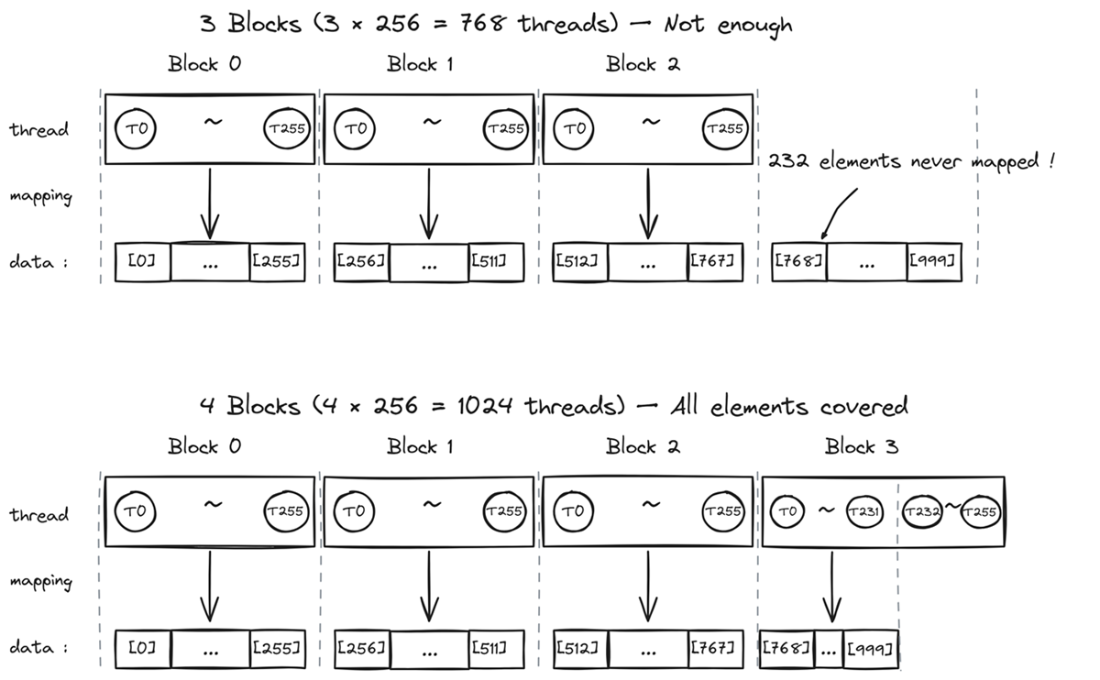
Too few blocks leaves gaps; one more block covers everything. With 3 blocks of 256 threads (768 total), the last 232 elements are never touched; simply adding a fourth block covers all 1,000 elements, though the 24 extra threads (indices 1000–1023) must be guarded with a bounds check.
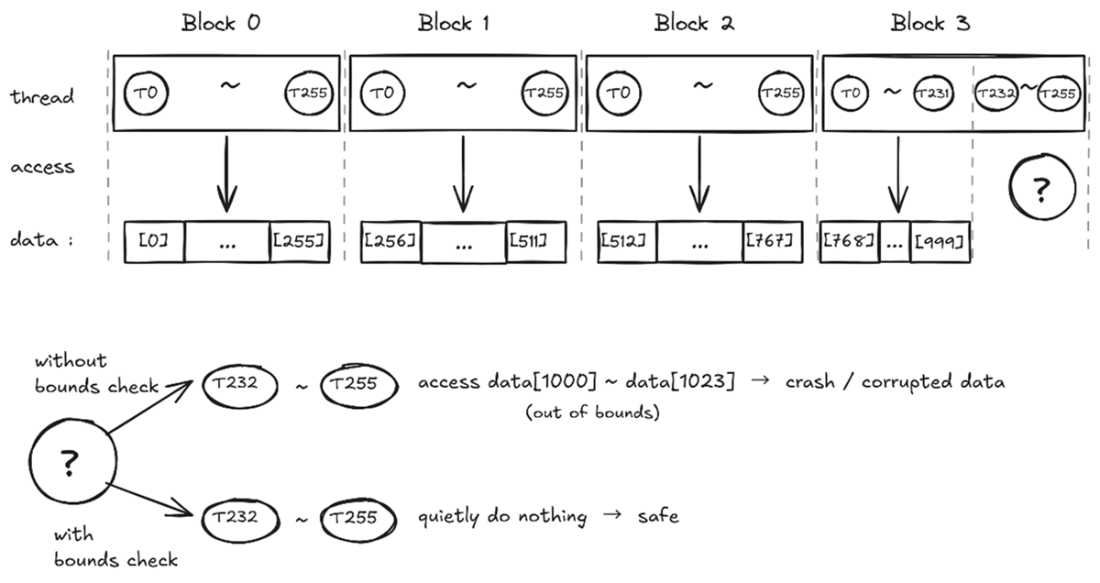
Bounds check: the one-line fix that prevents out-of-bounds disaster. Without it, threads T232–T255 in Block 3 blindly access data[1000]–data[1023], memory that doesn't belong to your array, causing crashes or silent corruption. With it, those same threads simply skip the work and do nothing: safe, but still consuming GPU resources.
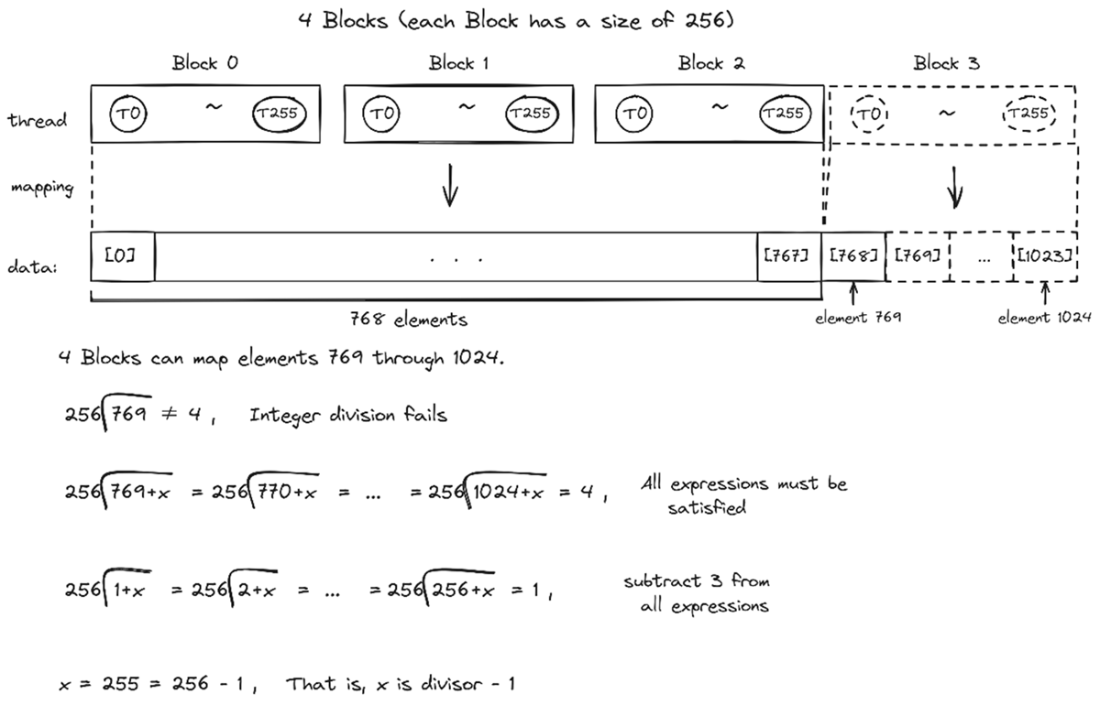
Ceiling division: why (divisor − 1) is the right amount to add. With 1,000 elements and 256 threads per block, plain integer division gives 3 blocks, which is not enough. Adding (256 − 1 = 255) to the numerator guarantees that any leftover elements tip the result up to 4 blocks, while exact multiples stay put.
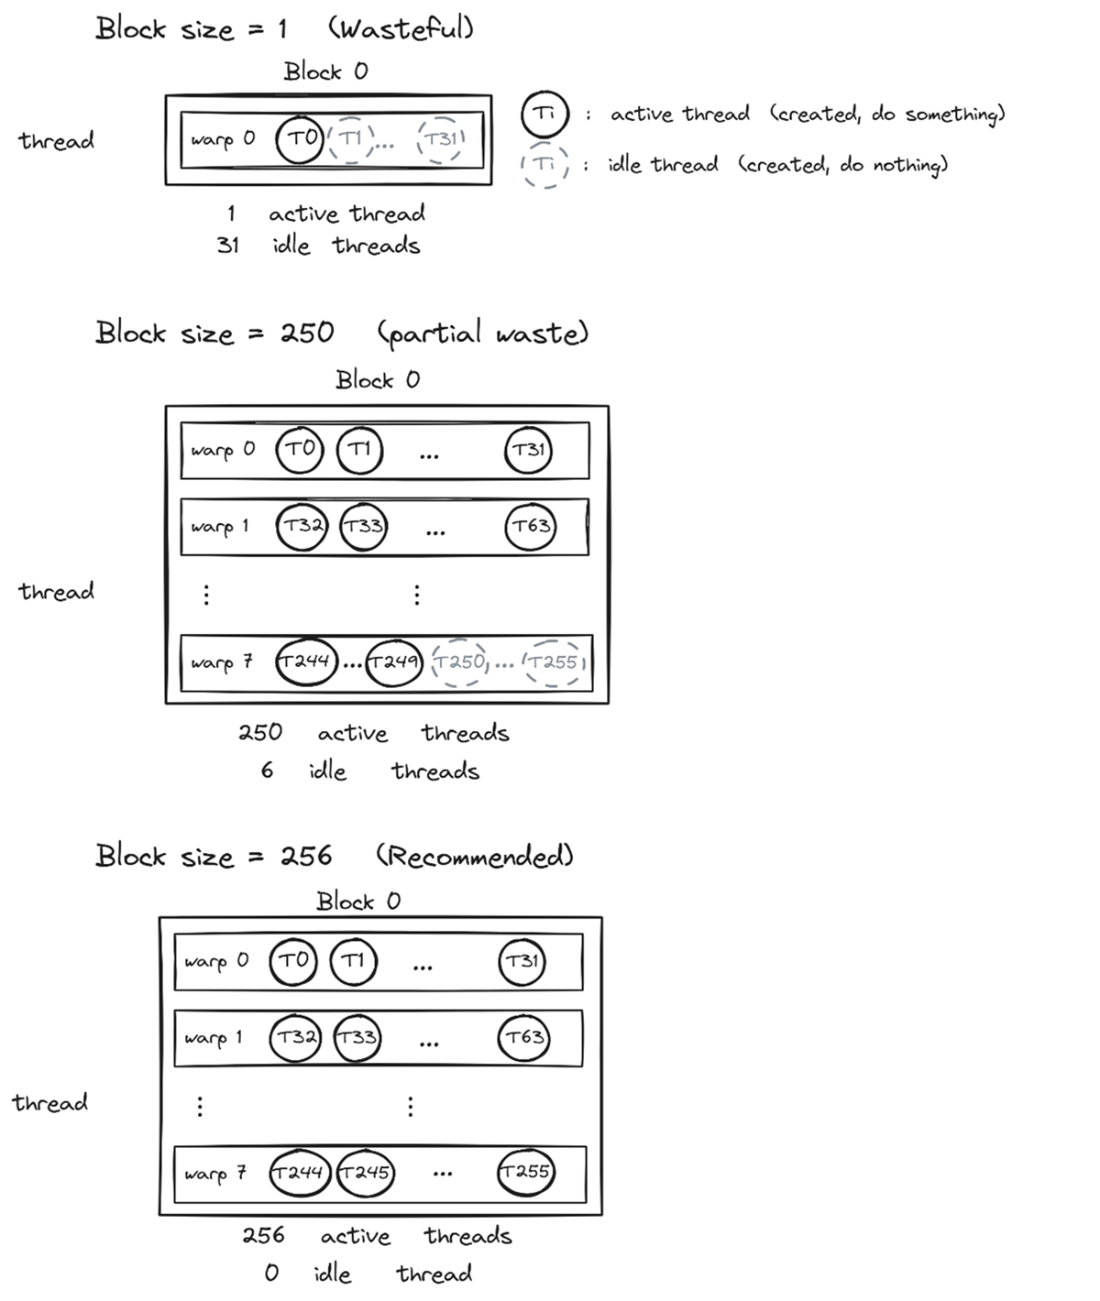
Block size matters: warp utilization from wasteful to optimal. A block size of 1 leaves 31 out of 32 warp threads idle, a about 97% waste. A block size of 250 is better but still wastes 6 threads in the last warp. A block size of 256 (a multiple of 32) fills every warp completely, leaving no thread in a warp idle.
The thread-to-element recipe: four steps nearly every CUDA kernel follows. Set your block size to 256, use ceiling division to count blocks, compute each thread's global index, then guard the boundary with if (idx < n). Get these four steps right, and every element gets covered: no gaps, no out-of-bounds crashes. Steps 1 and 2 run on the host (CPU); steps 3 and 4 run inside the kernel on the device (GPU).
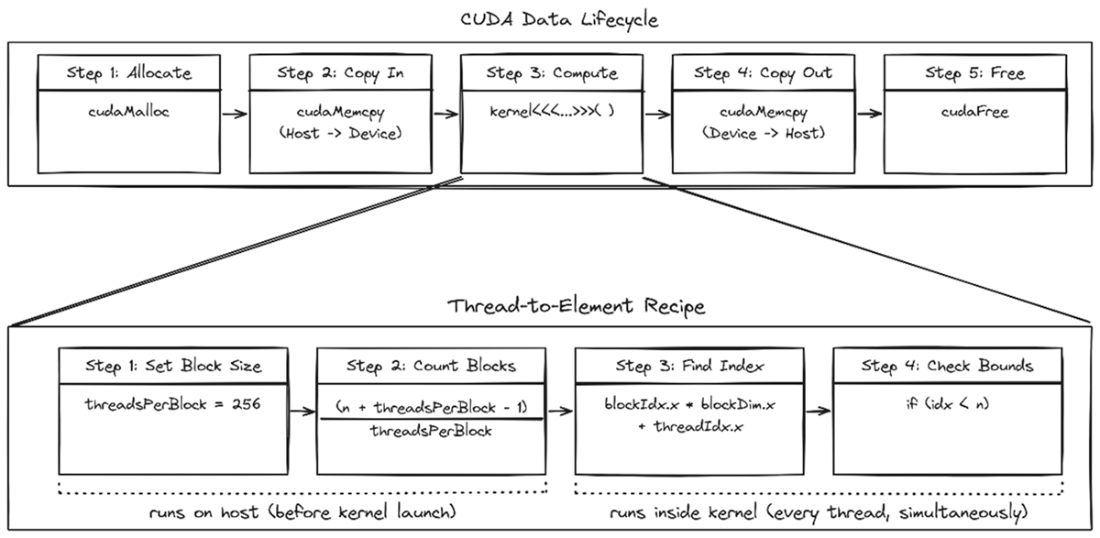
The Thread-to-Element Recipe is a zoom-in on Step 3. The CUDA Data Lifecycle shows the big picture: allocate, copy in, compute, copy out, free. The Thread-to-Element Recipe zooms into the Compute step, splitting it into two host-side steps (set block size, count blocks) and two kernel-side steps (find index, check bounds) that run simultaneously across every thread.
Summary
- Grids are composed of blocks, and blocks are composed of threads. CUDA organizes execution like a school with classrooms and students. A single block holds at most 1,024 threads.
- Going past the 1,024-thread limit makes the launch fail: no threads run and nothing is printed. Call cudaGetLastError() right after a launch to see the error.
- The global index formula int idx = blockIdx.x * blockDim.x + threadIdx.x gives each thread its unique position.
- The ceiling division formula (n + threadsPerBlock - 1) / threadsPerBlock rounds up so no elements are missed.
- Include a bounds check, if (idx < n), to prevent out-of-bounds memory access.
- Start with 256 threads per block, a multiple of 32 that works for most kernels.
- Each block is handed to a single SM and runs there from start to finish, and any extra blocks wait their turn. That is what lets the same kernel scale from a laptop GPU to a data-center GPU without a code change.
- Blocks may run in any order and can’t synchronize with each other while a kernel is running. Don’t assume Block 0 finishes before Block 1.
- Kernel launches return immediately. Call cudaDeviceSynchronize() after the launch to make the kernel’s completion point explicit, and use it sparingly once you tune for performance.

 Grokking Parallel Programming ebook for free
