4 Text2Cypher: Generating query language from natural language questions
This chapter explains how to turn natural language questions into Cypher queries so a knowledge graph can be queried dynamically, beyond the limits of vector-only retrieval. The core challenge is generating queries that are both syntactically correct and aligned with the graph’s schema, which requires mapping the meaning of a user’s question to node labels, relationship types, and properties. Using a shared schema and a small set of guiding examples enables an LLM to reliably translate intent into executable Cypher, demonstrated throughout with a Movies dataset.
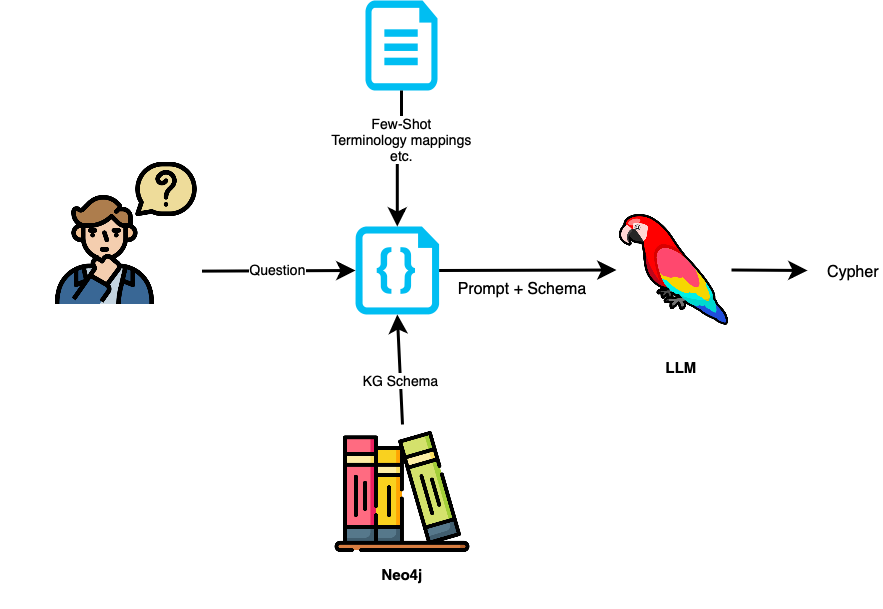
In the broader RAG flow, Text2Cypher complements vector search by handling questions that require precise traversals, filtering, grouping, and aggregation—use cases where similarity alone falls short. The workflow is straightforward: capture the question, provide the graph schema, add useful terminology mappings, include format instructions, supply a few-shot set of Q&A patterns, assemble the prompt, and let the LLM produce Cypher. The chapter shows how to expose schema details in the prompt, discusses practical schema inference from Neo4j (often via sampling and APOC procedures), and positions Text2Cypher as both a targeted tool for structured queries and a catch-all retriever within an agentic, multi-retriever system.
Practical guidance focuses on reducing common LLM errors: few-shot examples to correct recurring misunderstandings, explicit schema blocks to constrain available structures, terminology mappings to resolve vocabulary mismatches, and strict format instructions to ensure clean, executable outputs. A reusable prompt template combines these ingredients and yields strong results with base models; at the same time, specialized fine-tuned Text2Cypher models offer efficiency benefits even if they trail the largest frontier models. The takeaway is an iterative recipe: start with schema, mappings, examples, and formatting; observe failure modes; then expand the few-shot set and mappings to steadily improve accuracy, reliability, and coverage across diverse graph questions.
Workflow for generating Cypher queries from natural language questions
Summary
- Learned the basics of query language generation and that it fits in well the RAG pipeline as a complement to other retrieval methods. Especially when we want to aggregate data or get specific data from the graph.
- Covered useful practices for query language generation, like using few-shot examples, schema, terminology mappings and format instructions.
- Learned how to implement a text2cypher retriever using a base model, and how to structure the prompt to the LLM.
- Explored using specialized (fine-tuned) LLMs for text2cypher and how to improve their performance.
FAQ
What is Text2Cypher and why is it useful?
Text2Cypher is the process of converting a natural language question into a Cypher query that can be executed on a graph database. It enables flexible, dynamic retrieval that goes beyond pure vector similarity, supporting precise traversals, filtering, aggregation, and ranking across a knowledge graph.Where does query generation fit in a RAG pipeline?
Text2Cypher complements vector search. While vector similarity works well for retrieving unstructured text, some questions require structured graph queries (e.g., aggregations, joins, rankings). In such cases, generated Cypher provides the relevant context or answers that vector-only approaches cannot.Why must I include the database schema in the prompt?
Without a schema, the LLM guesses node labels, relationship types, and properties, leading to errors. Providing the schema maps user intent to the actual graph model (labels, relationships, properties, and how nodes connect), greatly improving correctness and relevance.What are the core steps in a Text2Cypher workflow?
- Retrieve the user’s question.
- Retrieve the knowledge graph schema.
- Add helpful context: terminology mappings, format instructions, few-shot examples.
- Assemble the prompt.
- Use the LLM to generate the Cypher query.

 Essential GraphRAG ebook for free
