6 The universal workflow of machine learning
Real-world machine learning begins with a problem, not a ready-made dataset. The workflow emphasizes three broad phases that tie technical work to business value: define the task, develop a model, and deploy and maintain it. Success hinges on clear problem framing, selecting meaningful measures of success, and above all, high-quality, representative data. The chapter also underlines ethical responsibility: technical choices carry social impacts, and flawed objectives or biased data can turn models into vehicles for harm.
Defining the task means clarifying inputs, targets, constraints, and the exact learning setup (classification, regression, ranking, etc.), while assessing existing processes and feasibility. Since data is the primary driver of generalization, the chapter details dataset collection and annotation strategies, trade-offs of outsourcing versus in-house labeling, and the need for subject-matter expertise and robust tooling. It warns about non-representative data, sampling bias, target leakage, and concept drift, recommending data exploration, thoughtful feature checks, and metrics aligned to the problem (e.g., precision/recall or ROC AUC instead of raw accuracy when classes are imbalanced).
Model development starts with careful preprocessing (vectorization, normalization, and handling missing values) and a reliable evaluation protocol (hold-out or K-fold). The initial goal is to beat a simple baseline using informed features, appropriate architectures, and suitable loss functions; then deliberately overfit to gauge capacity, before regularizing and tuning (dropout, L1/L2, hyperparameters, and iterative data curation), while avoiding validation leakage. Deployment covers communicating realistic expectations to stakeholders, shipping inference models via a server API, on-device, or in-browser, and optimizing them with pruning and quantization for speed and size. Finally, sustained success requires monitoring in production (A/B tests, audits, user feedback) and continuous maintenance to combat concept drift by collecting fresh data and retraining subsequent model generations.
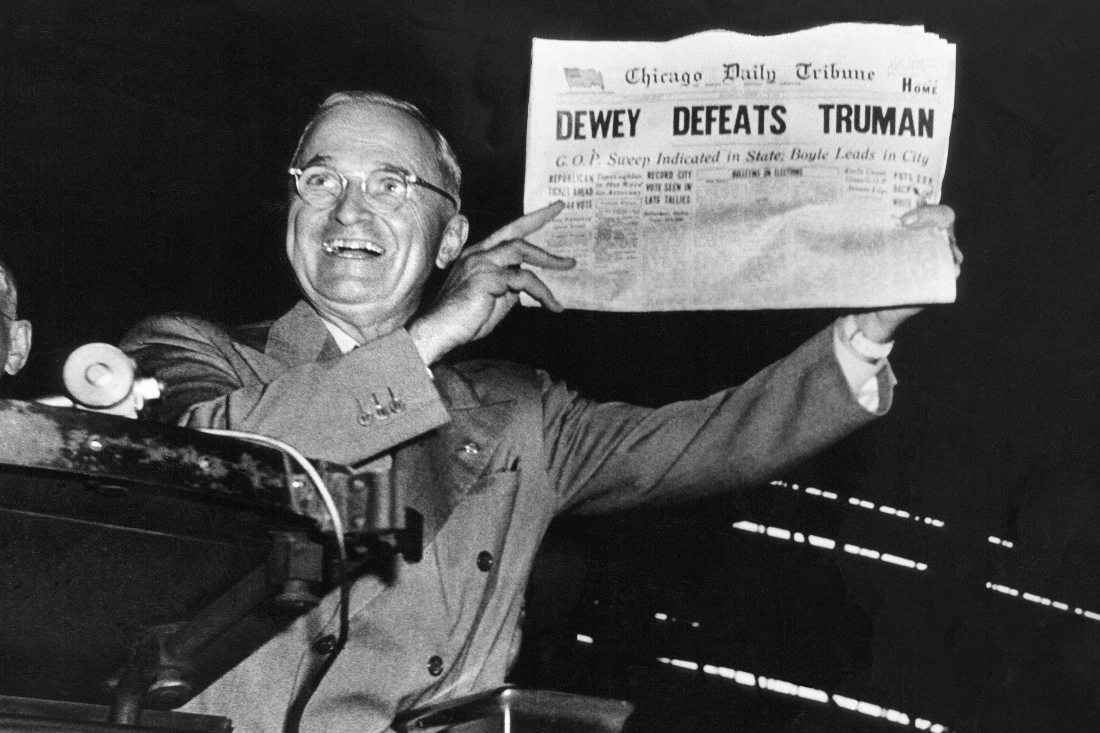
“DEWEY DEFEATS TRUMAN”: a famous example of sampling bias
Chapter summary
- When you take on a new machine learning project, first, define the problem at hand:
- Understand the broader context of what you’re setting out to do – what’s the end goal and what are the constraints?
- Collect and annotate a dataset; make sure you understand your data in depth.
- Choose how you’ll measure success on your problem – what metrics will you monitor on your validation data?
- Once you understand the problem and you have an appropriate dataset, develop a model:
- Prepare your data.
- Pick your evaluation protocol: hold-out validation? K-fold validation? Which portion of the data should you use for validation?
- Achieve statistical power: beat a simple baseline.
- Scale up: develop a model that can overfit.
- Regularize your model and tune its hyperparameters, based on performance on the validation data. A lot of machine learning research tends to focus only on this step – but keep the big picture in mind.
- When your model is ready and yields good performance on the test data, it’s time for deployment:
- First, make sure to set appropriate expectations with stakeholders.
- Optimize a final model for inference, and ship the model to the deployment environment of choice – web server, mobile, browser, embedded device…
- Monitor your model’s performance in production and keep collecting data so you can develop the next generation of the model.
FAQ
What are the three main stages in the universal workflow of machine learning?
The workflow has three broad stages:
- Define the task: understand the business goal, map it to an ML task, identify inputs and targets, and decide how success will be measured.
- Develop a model: prepare data, pick an evaluation protocol and a simple baseline, train a first model with statistical power, then scale, regularize, and tune for generalization.
- Deploy the model: communicate expectations to stakeholders, ship an inference model (server, device, or browser), monitor performance in production, and plan the next iteration.
How do I frame a machine learning problem from a business request?
- Clarify inputs and targets: what data do you have or can collect, and what exactly should be predicted?
- Choose a task type: binary/multiclass classification, multilabel classification, regression, ranking, detection/segmentation, or even non-ML analysis if more appropriate.
- Study existing solutions: manual processes, rules-based systems, and their limitations.
- List constraints: latency, privacy, on-device requirements, data access, compute budget.
- Make hypotheses to validate: that the target is predictable from inputs and that the data is informative enough.
What ethical considerations should I keep in mind before starting?
- Feasibility vs harm: avoid tasks with dubious validity (e.g., inferring traits not grounded in data) that risk encoding prejudice as “objective” outputs.
- Bias in labels: labeling processes can capture and amplify human biases; design guidelines, audits, and diverse annotator pools to mitigate.
- Transparency and expectations: explain limitations and failure modes; avoid implying human-like understanding.
- Privacy and consent: minimize data collection, protect sensitive inputs, and honor user expectations and regulations.
- Remember: technical choices are also ethical choices; align with the values and impacts you intend.
What are best practices for collecting and annotating a dataset?
- Pick the right labeling workflow: in-house experts, trained annotators, crowdsourcing, or specialized vendors—trade off cost, speed, expertise, and quality control.
- Define clear guidelines: detailed instructions, gold-standard examples, and spot checks to reduce noise.
- Invest in tooling: efficient annotation software and review pipelines pay off quickly.
- Plan for scale and iteration: expect multiple rounds of data improvements as you learn where the model struggles.
- Leverage existing signals when possible: e.g., clicks, likes, or operational logs can serve as labels.
How do I ensure my data is fit for purpose (representative, unbiased, and stable over time)?
- Representativity: collect training data from the same environment and user population as production; avoid training on “pretty” proxies that differ from real inputs.
- Sampling bias: ensure your collection method doesn’t correlate with the outcome (e.g., only surveying reachable subgroups); use stratified sampling and corrections.
- Concept drift: production data changes; monitor performance over time and plan regular refreshes and retraining.
- Early data checks: preview raw samples, examine distributions and maps, check class balance, and verify missing-value patterns.
- Target leakage: remove features that wouldn’t exist in production or that encode the answer directly.
How do I choose a measure of success and a matching loss/activation?
- Metrics align to goals: for balanced classification, accuracy and ROC AUC are common; for imbalanced or ranking-style problems, use precision/recall or confusion-based metrics; for regression, MAE is often more interpretable.
- Loss vs metric: you often optimize a proxy loss (e.g., crossentropy) for a metric that’s hard to differentiate (e.g., ROC AUC).
- Typical choices: binary classification → sigmoid + binary crossentropy; multiclass single-label → softmax + categorical crossentropy; multilabel → sigmoid + binary crossentropy; regression → linear output + MSE.
What evaluation protocol should I use to estimate generalization reliably?
- Hold-out validation: simplest and effective with plenty of data.
- K-fold cross-validation: better when data is limited; average across folds.
- Iterated K-fold: repeat K-fold with different splits for extra reliability on very small datasets.
- Always ensure validation representativity and no leakage: avoid duplicate or near-duplicate samples across train/validation splits.
How should I prepare data for deep learning?
- Vectorization: convert raw inputs (text, images, audio, tabular) to numeric tensors.
- Normalization: keep values small and features roughly on the same scale; standardize to zero mean/unit variance when appropriate.
- Missing values: for categorical features, add a “missing” category; for numeric, prefer imputing with mean/median (or model-based imputation) over arbitrary constants; consider simulating expected missingness during training.
How do I get to a first working model that beats a baseline?
- Start small to gain statistical power: build a simple model that exceeds naïve baselines.
- Focus on high-signal steps: feature engineering, the right architecture prior (dense, convnet, RNN/Transformer, or non-deep alternatives), and a sensible training setup (loss, learning rate, batch size).
- Research prior art: reuse proven templates and features for similar tasks.
- If you can’t beat a baseline, reassess: your target may not be predictable from the available inputs or the data may be insufficient.
How do I scale, regularize, tune, and avoid overfitting to validation?
- Scale to find capacity limits: add layers/units and train longer until you observe overfitting (validation performance degrades).
- Regularize and tune: try different architectures, add dropout, L1/L2, adjust learning rate, batch size, and units; iterate on features and data curation.
- Automate when possible: use hyperparameter tuning tools to explore configurations efficiently.
- Avoid validation overfitting: repeated tuning leaks information; confirm with a final test set, and consider stronger protocols (e.g., iterated K-fold) if discrepancies appear.
How do I deploy, optimize, monitor, and maintain a model in production?
- Deployment options:
- REST API (e.g., TensorFlow Serving or ONNX): good when connectivity is reliable, latency is moderate, and data can be sent server-side.
- On-device (e.g., TensorFlow Lite, ONNX Runtime Mobile): for strict latency, offline use, or sensitive inputs.
- In-browser (TensorFlow.js / ONNX JS): to keep data local, reduce server costs, and eliminate network round-trip latency.
- Inference optimization: prune weights to shrink compute, and quantize to int8 to cut size and often speed up with minimal accuracy loss.
- Set expectations: communicate failure modes and concrete false positive/negative trade-offs; select operating thresholds with stakeholders.
- Monitor in the wild: use A/B tests, logging, manual audits or user surveys to track impact on business metrics and data drift.
- Maintain continuously: collect and annotate fresh, representative data (especially “hard” cases), watch for new features/labels, and retrain regularly to counter concept drift.

 Deep Learning with Python, Third Edition ebook for free
