In this chapter, the reader adds the audio side of a voice AI system by building a Python-based speech recording and transcription workflow on a Mac. The goal is to capture microphone input, convert it into text, and produce a reusable foundation for a voice-enabled chatbot in the next chapter. Along the way, the chapter explains what speech recognition is, why Whisper is so effective, and why MLX Whisper is a better fit for Apple silicon than the standard CPU-based PyTorch version.
The chapter first introduces the core ideas behind speech recognition and digital audio. It explains how Whisper was trained on massive multilingual audio data, how its encoder-decoder transformer architecture turns spectrograms into text, and why it can achieve human-level accuracy in English and strong performance in many other languages while still running locally and privately. It then covers the practical audio concepts needed for implementation, including sample rate, mono versus stereo channels, and the difference between float32 arrays and int16 WAV data.
After that, the chapter walks through installation and coding. It shows how to install the required Python packages, record audio from the microphone with sounddevice, save it as a WAV file, and transcribe it with a single mlx_whisper.transcribe() call. It also helps the reader choose an appropriate Whisper model size based on memory and accuracy tradeoffs, then wraps everything into a reusable script that can be run from the command line or imported into other programs. Finally, it closes with troubleshooting advice for microphone permissions, missing packages, slow downloads, and ffmpeg issues, plus exercises for testing accuracy, comparing model sizes, and experimenting with noisy or non-English speech.
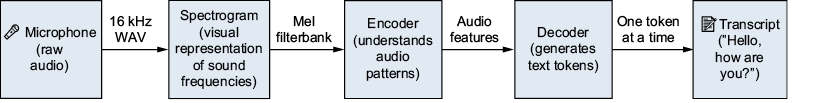
Whisper’s encoder-decoder architecture. Audio is converted into a spectrogram, which the encoder processes. The decoder processes the encoder’s output together with control tokens to generate a transcript.
Summary
- Whisper is OpenAI’s speech recognition model, trained on 680,000 hours of multilingual audio. It achieves human-level accuracy in English and works entirely offline.
- MLX Whisper is a port of Whisper to Apple’s MLX framework, optimized for Apple silicon (M1, M2, M3, etc., chips). It is 4–6 times faster than standard PyTorch Whisper on the same Mac hardware.
- Audio for Whisper must be mono, 16 kHz, and float32 (for processing) or int16 (for WAV files).
sounddevice.rec()captures audio from the microphone;sd.wait()blocks until recording finishes.mlx_whisper.transcribe(path,path_or_hf_repo=model)returns a dictionary;result["text"]contains the transcript.- Five model sizes are available, from tiny through large-v3. Start with small on memory-constrained systems, try medium when more unified memory is available, and use large-v3 only when the benefit of accuracy justifies the additional memory and latency.
- The
voice_input.pymodule created in this chapter providesrecord_and_transcribe()andtranscribe_file()functions, which you will use in chapter 10.
FAQ
What is speech recognition, and why is it difficult?
Speech recognition, also called automatic speech recognition (ASR), is the task of converting audio into text. It is difficult because accents, speaking speed, pronunciation, background noise, and context all affect how words are recognized.How does Whisper achieve high transcription accuracy?
Whisper is trained on 680,000 hours of multilingual audio, which helps it learn both how words sound and the statistical patterns of language. It uses an encoder-decoder transformer architecture to convert speech into text with human-level accuracy in English and near-human accuracy in many other languages.Why does MLX Whisper run faster on Apple silicon than standard PyTorch Whisper?
MLX is built specifically for Apple silicon and takes advantage of unified memory across the CPU, GPU, and Neural Engine. Standard PyTorch Whisper on a Mac typically runs on the CPU, while MLX Whisper can use the Mac’s hardware more efficiently, resulting in much faster transcription.What packages do I need to install to record audio and transcribe it with MLX Whisper?
You needmlx-whisper, sounddevice, numpy, and scipy. mlx-whisper provides transcription, sounddevice accesses the microphone, numpy handles audio arrays, and scipy writes WAV files.What are the key digital audio settings I need to understand?
The main settings are sample rate, channels, and bit depth. Whisper expects 16 kHz audio, mono input with one channel, and audio stored as float32 in Python before being converted to int16 for WAV files.Why does the chapter record audio as float32 and convert it to int16 later?
Float32 is convenient for working with audio in Python and NumPy because it uses values between -1.0 and 1.0. WAV files typically store samples as int16, so the audio is scaled by 32767 and converted before saving.How does the microphone recording script capture audio in Python?
The script usessd.rec() to record from the default microphone, sd.wait() to block until recording finishes, and squeeze() to flatten the audio array from shape (N, 1) to (N,).How do I transcribe a recorded WAV file with MLX Whisper?
Callmlx_whisper.transcribe() with the audio file path and pass the model name using path_or_hf_repo. The function returns a dictionary, and the chapter uses result["text"] to get the transcript.Which Whisper model should I choose for my Mac?
With 8 GB of unified memory, start withwhisper-small-mlx. With 16 GB or more, try whisper-medium-mlx first. Use whisper-large-v3-mlx when accuracy matters most and you have enough free memory.What common problems can occur when recording or transcribing speech, and how do I fix them?
Common issues include no microphone access, empty transcripts, missingmlx_whisper, slow first downloads, and missing ffmpeg. Fixes include enabling microphone permissions in macOS, speaking after recording starts, reinstalling the package in the correct virtual environment, waiting for the model download to complete, and installing ffmpeg with Homebrew.
 Build Applications with Local AI Models on a Mac ebook for free
