4 Mixture-of-Experts (MoE) in DeepSeek: Scaling intelligence efficiently
The chapter introduces mixture-of-experts as a way to replace a single dense feed-forward network with many smaller specialist networks, or experts, so a model can grow in knowledge without paying a proportional compute cost. The key idea is sparsity: for each token, only a small subset of experts is activated, while the rest stay idle. A learned router decides which experts matter most, making MoE an efficient alternative to always running one large dense block for every token.
It then walks through the mechanics of MoE in a step-by-step, mathematical way. Tokens are scored by a router, the top-k experts are selected, and their scores are normalized into weights with softmax. Each chosen expert produces an output, and those outputs are combined into a single result by a weighted sum, restoring the same tensor shape expected by the Transformer. The chapter also explains why routing can become unstable: if some experts get too many tokens and others too few, training becomes inefficient and model capacity is wasted.
To fix this, the chapter compares traditional balancing methods with DeepSeek’s improvements. Standard auxiliary and load-balancing losses encourage more even expert usage, but they can conflict with the main language-model objective and still allow temporary overloads. DeepSeek addresses this with fine-grained expert segmentation, shared experts that handle common knowledge, and auxiliary-loss-free load balancing that adjusts router bias dynamically instead of adding a separate loss. The chapter closes by showing a from-scratch PyTorch implementation of a DeepSeek-style MoE layer and reporting that, in a small experiment, it achieved lower validation loss, higher throughput, and much more even expert utilization than a standard MoE.
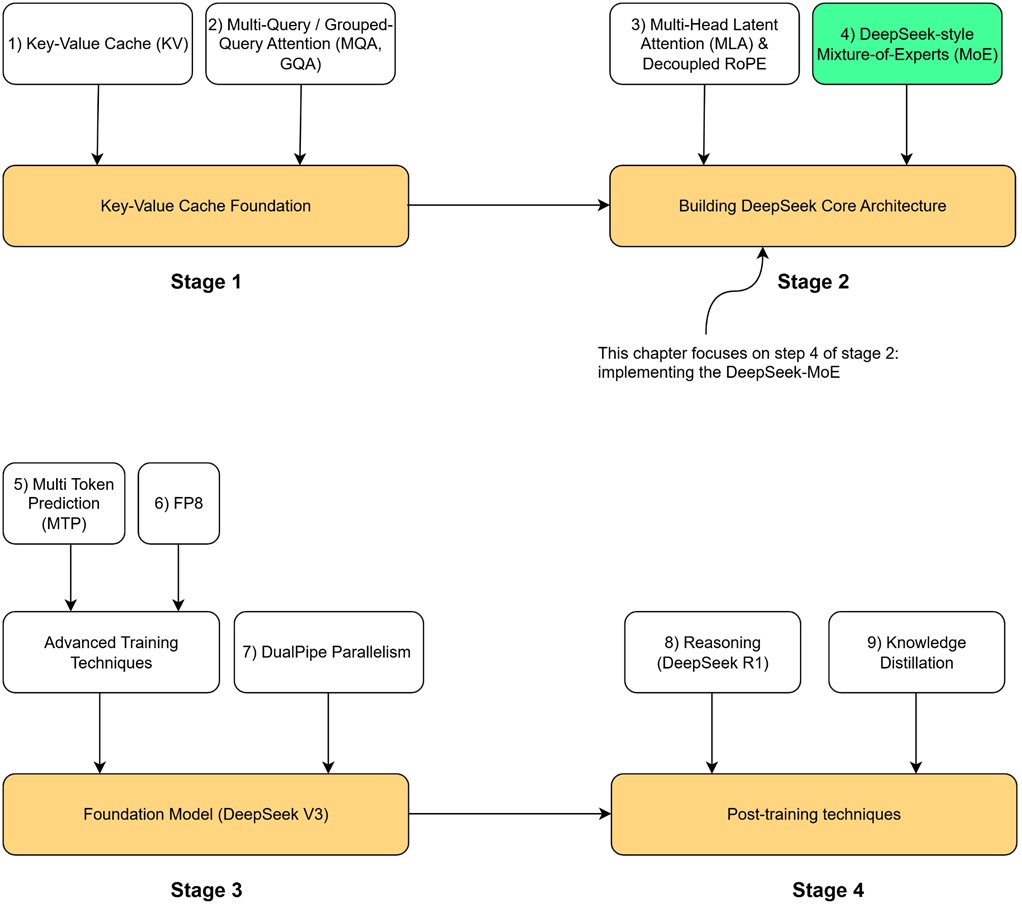
```This chapter focuses on the highlighted component, DeepSeek-style Mixture-of-Experts (MoE), the second major innovation in the core architecture.
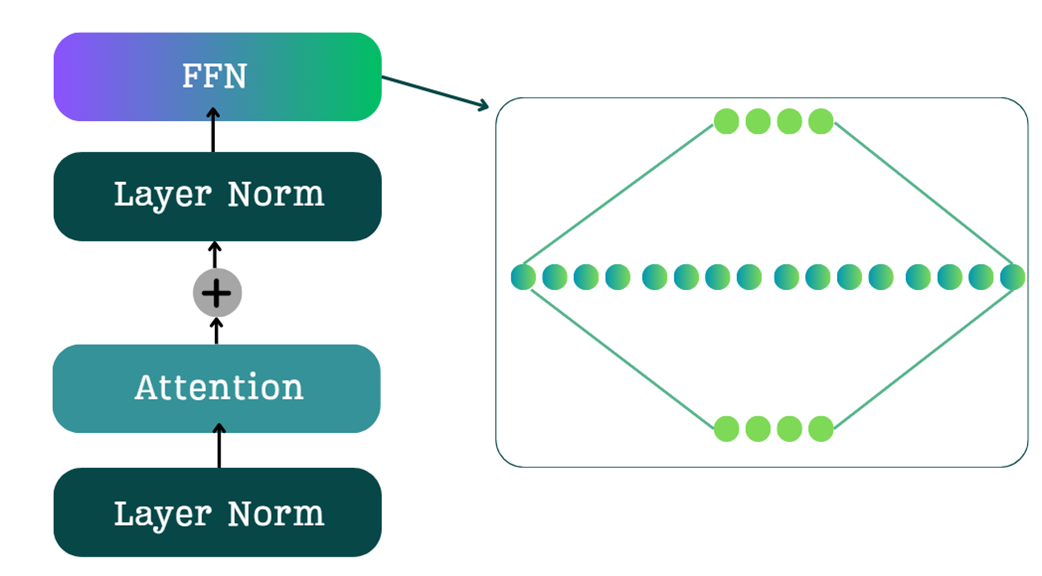
The standard Feed-Forward Network (FFN) in a Transformer block, featuring an expansion-contraction architecture.
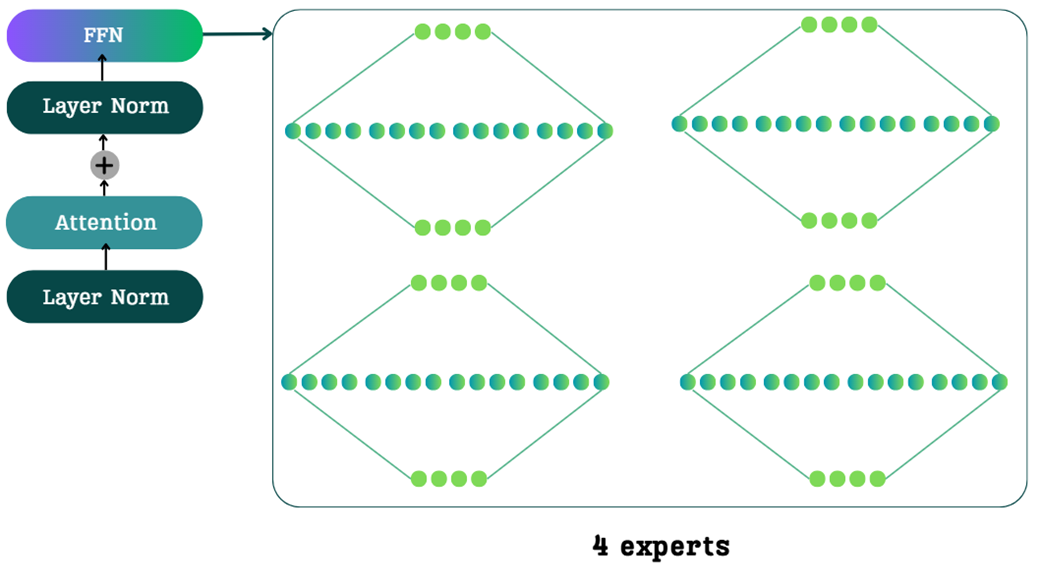
The architectural change of MoE. The single, dense FFN is replaced by a collection of four smaller, specialized expert networks.
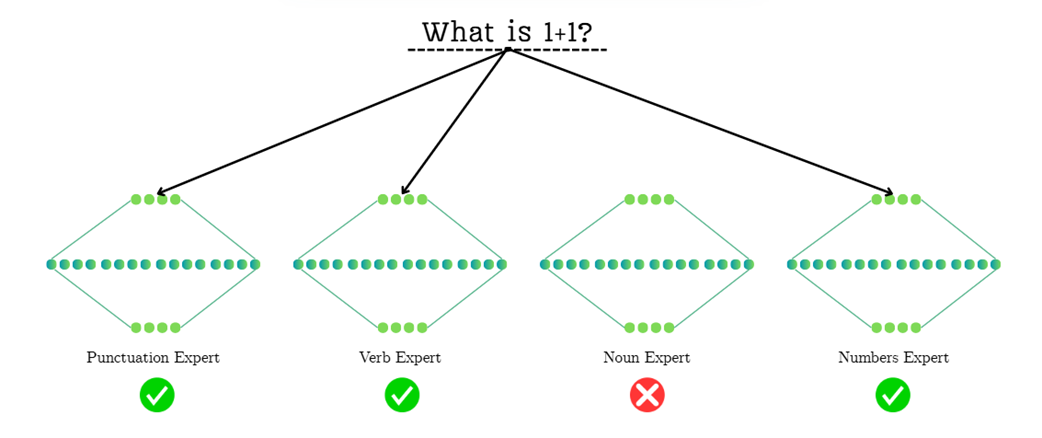
An example of expert routing in a Mixture-of-Experts model. For the input "What is 1+1?", the router must decide which specialized experts to activate. The routing mechanism might prioritize grammatical components (like the question mark and the verb "is"), highlighting how routing is a nuanced decision based on learned patterns.
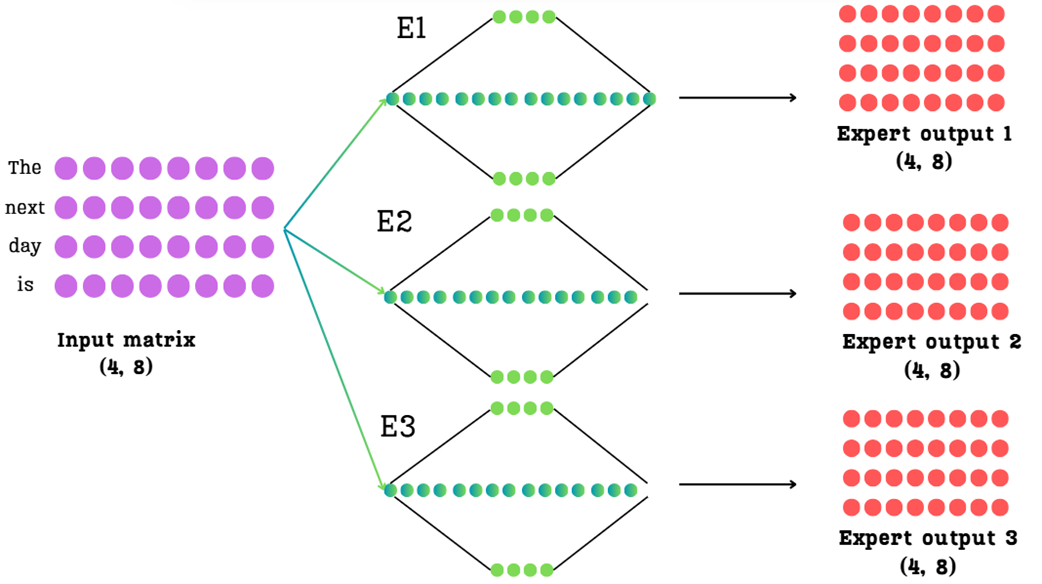
The initial challenge of MoE. The input matrix is passed through each of the three expert networks in parallel, resulting in three separate expert output matrices.
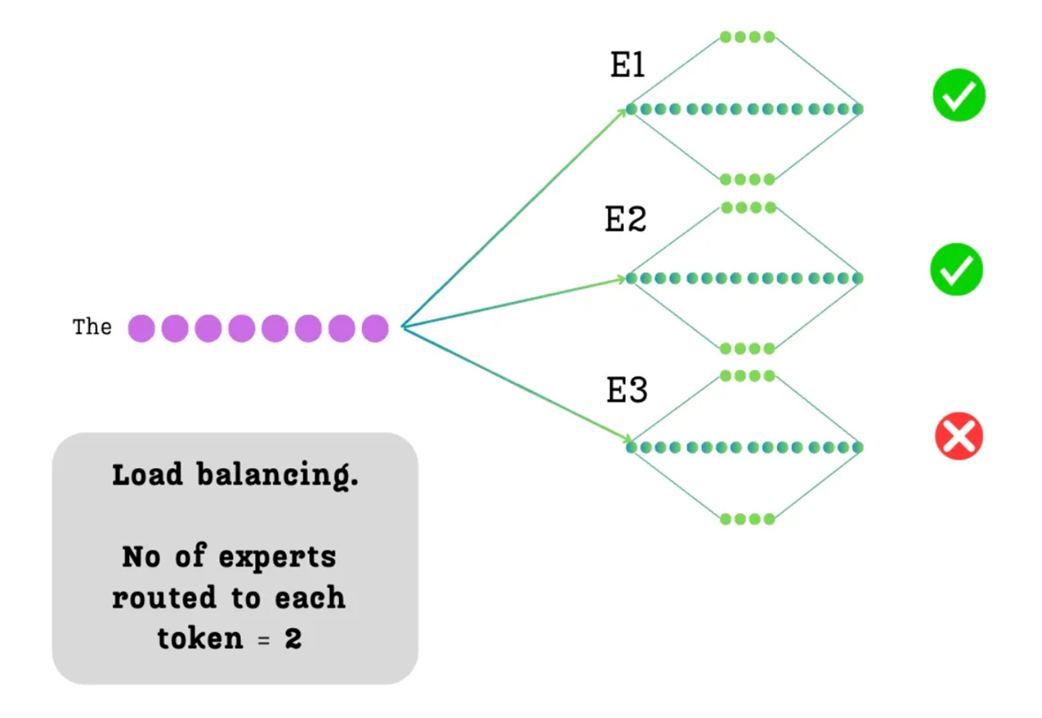
The principle of sparsity or load balancing. For each token, we decide to route it to only a subset (k=2) of the available experts.
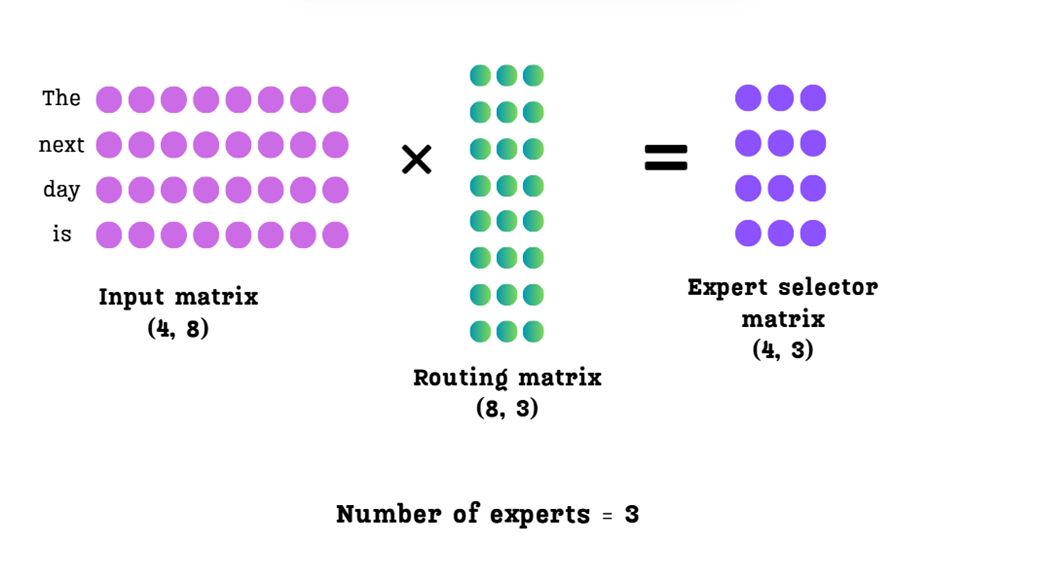
The routing mechanism. The input matrix is multiplied by a learned routing matrix to produce an expert selector matrix, which contains a raw score for each expert for each token.
The top-k selection process. For each row, only the two highest scores are kept, and the rest are masked out.
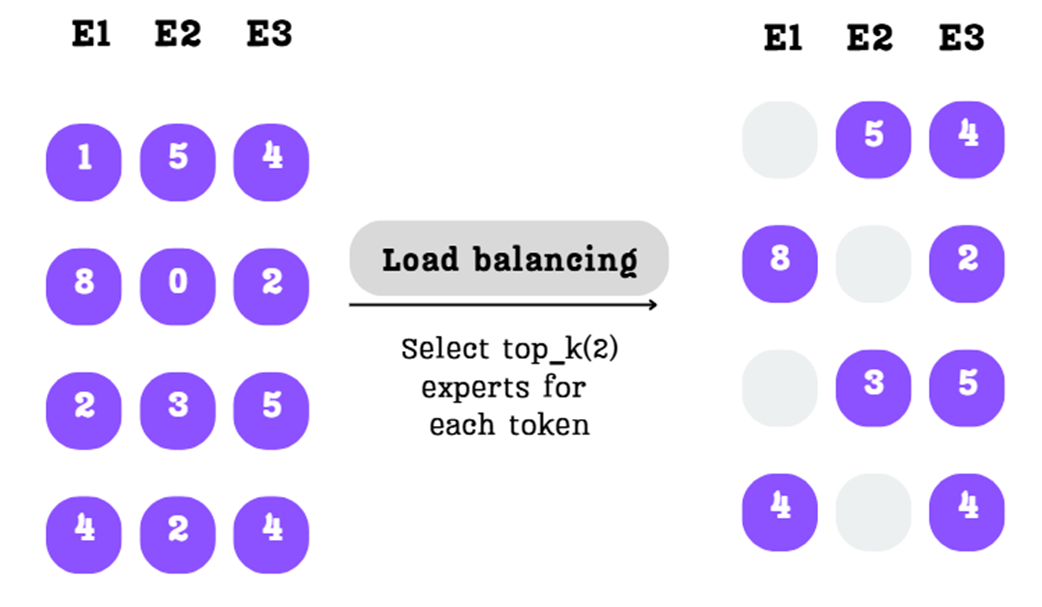
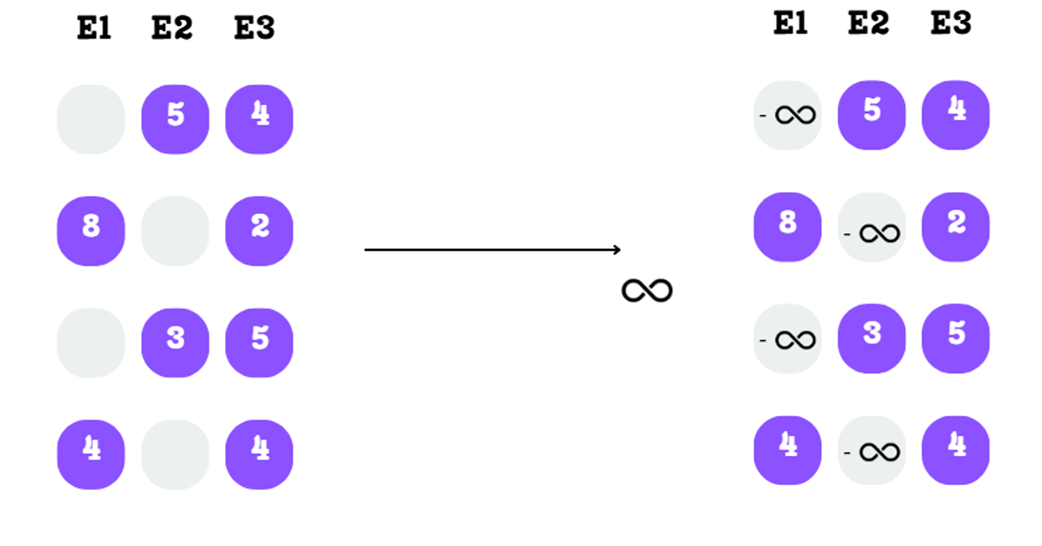
The masked scores are replaced with negative infinity in preparation for the softmax function.
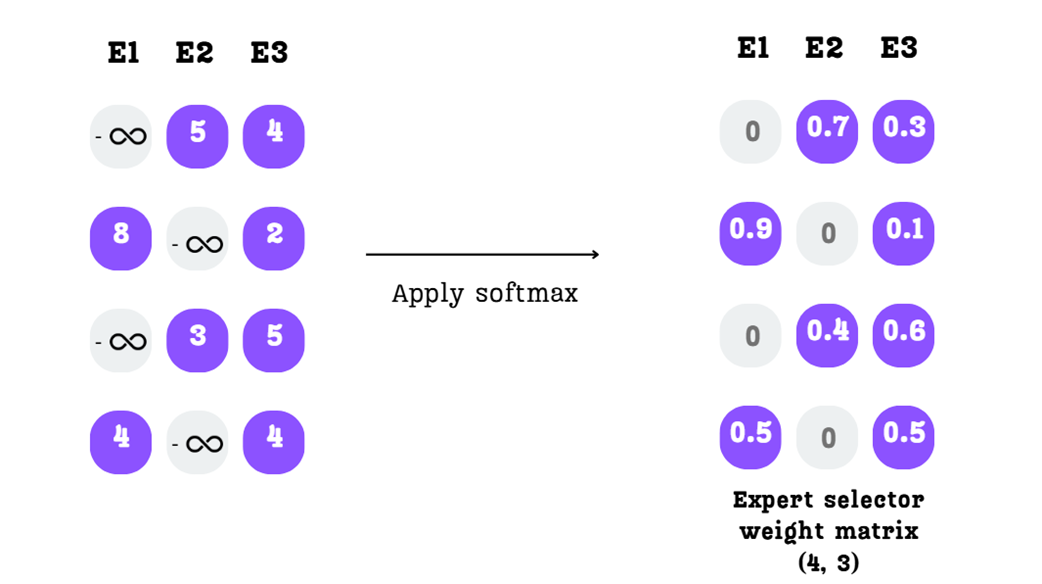
The softmax function converts the scores into a final expert selector weight matrix.
Calculating the final output for a single token. The weights from the selector matrix are used to create a weighted sum of the corresponding expert outputs.
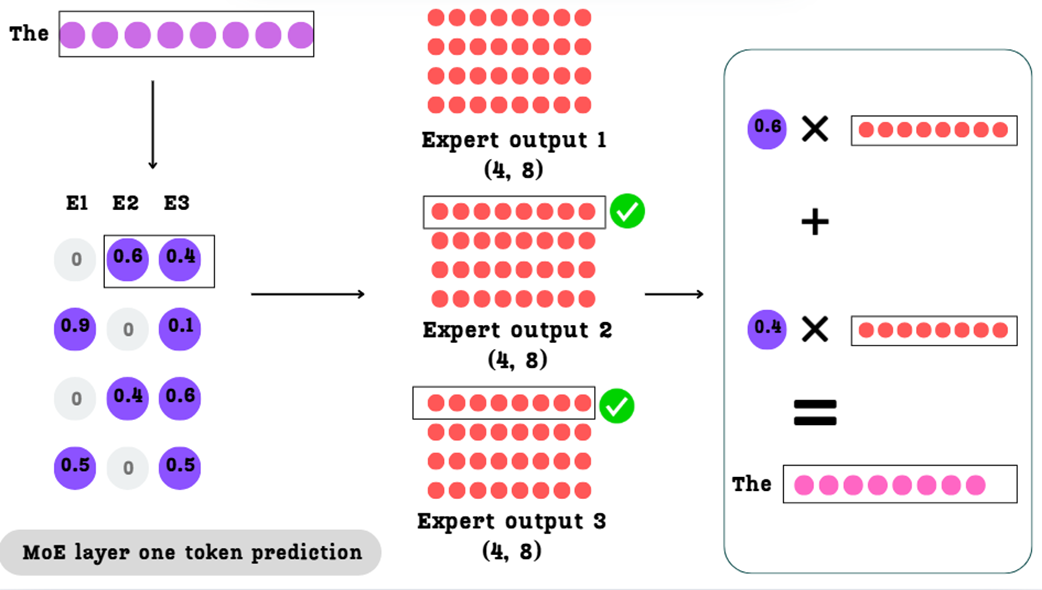
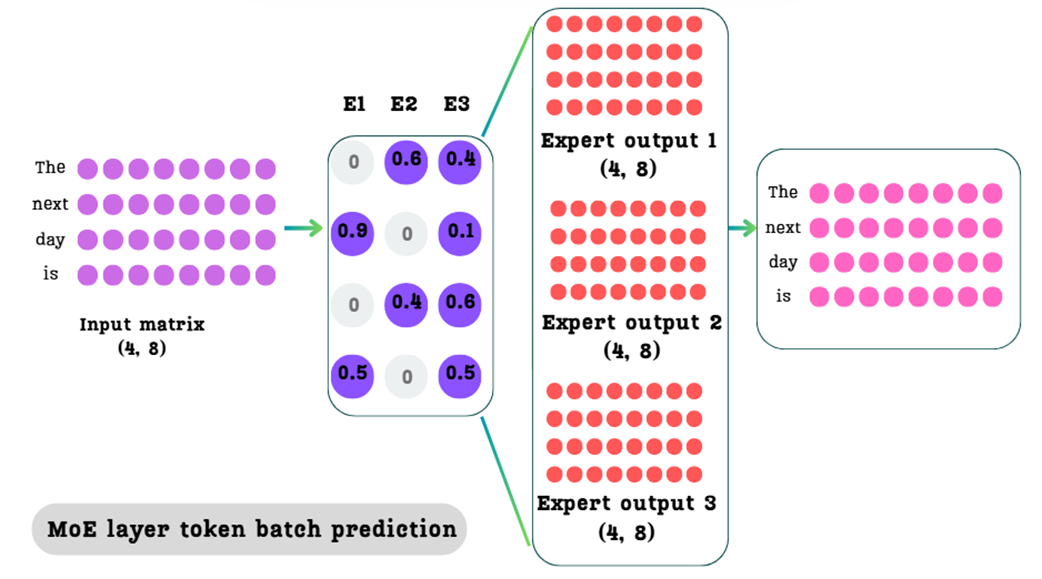
The complete MoE process for a batch of tokens. The expert selector weight matrix guides the weighted summation of the expert outputs to produce a single, final output matrix of the same shape as the input.
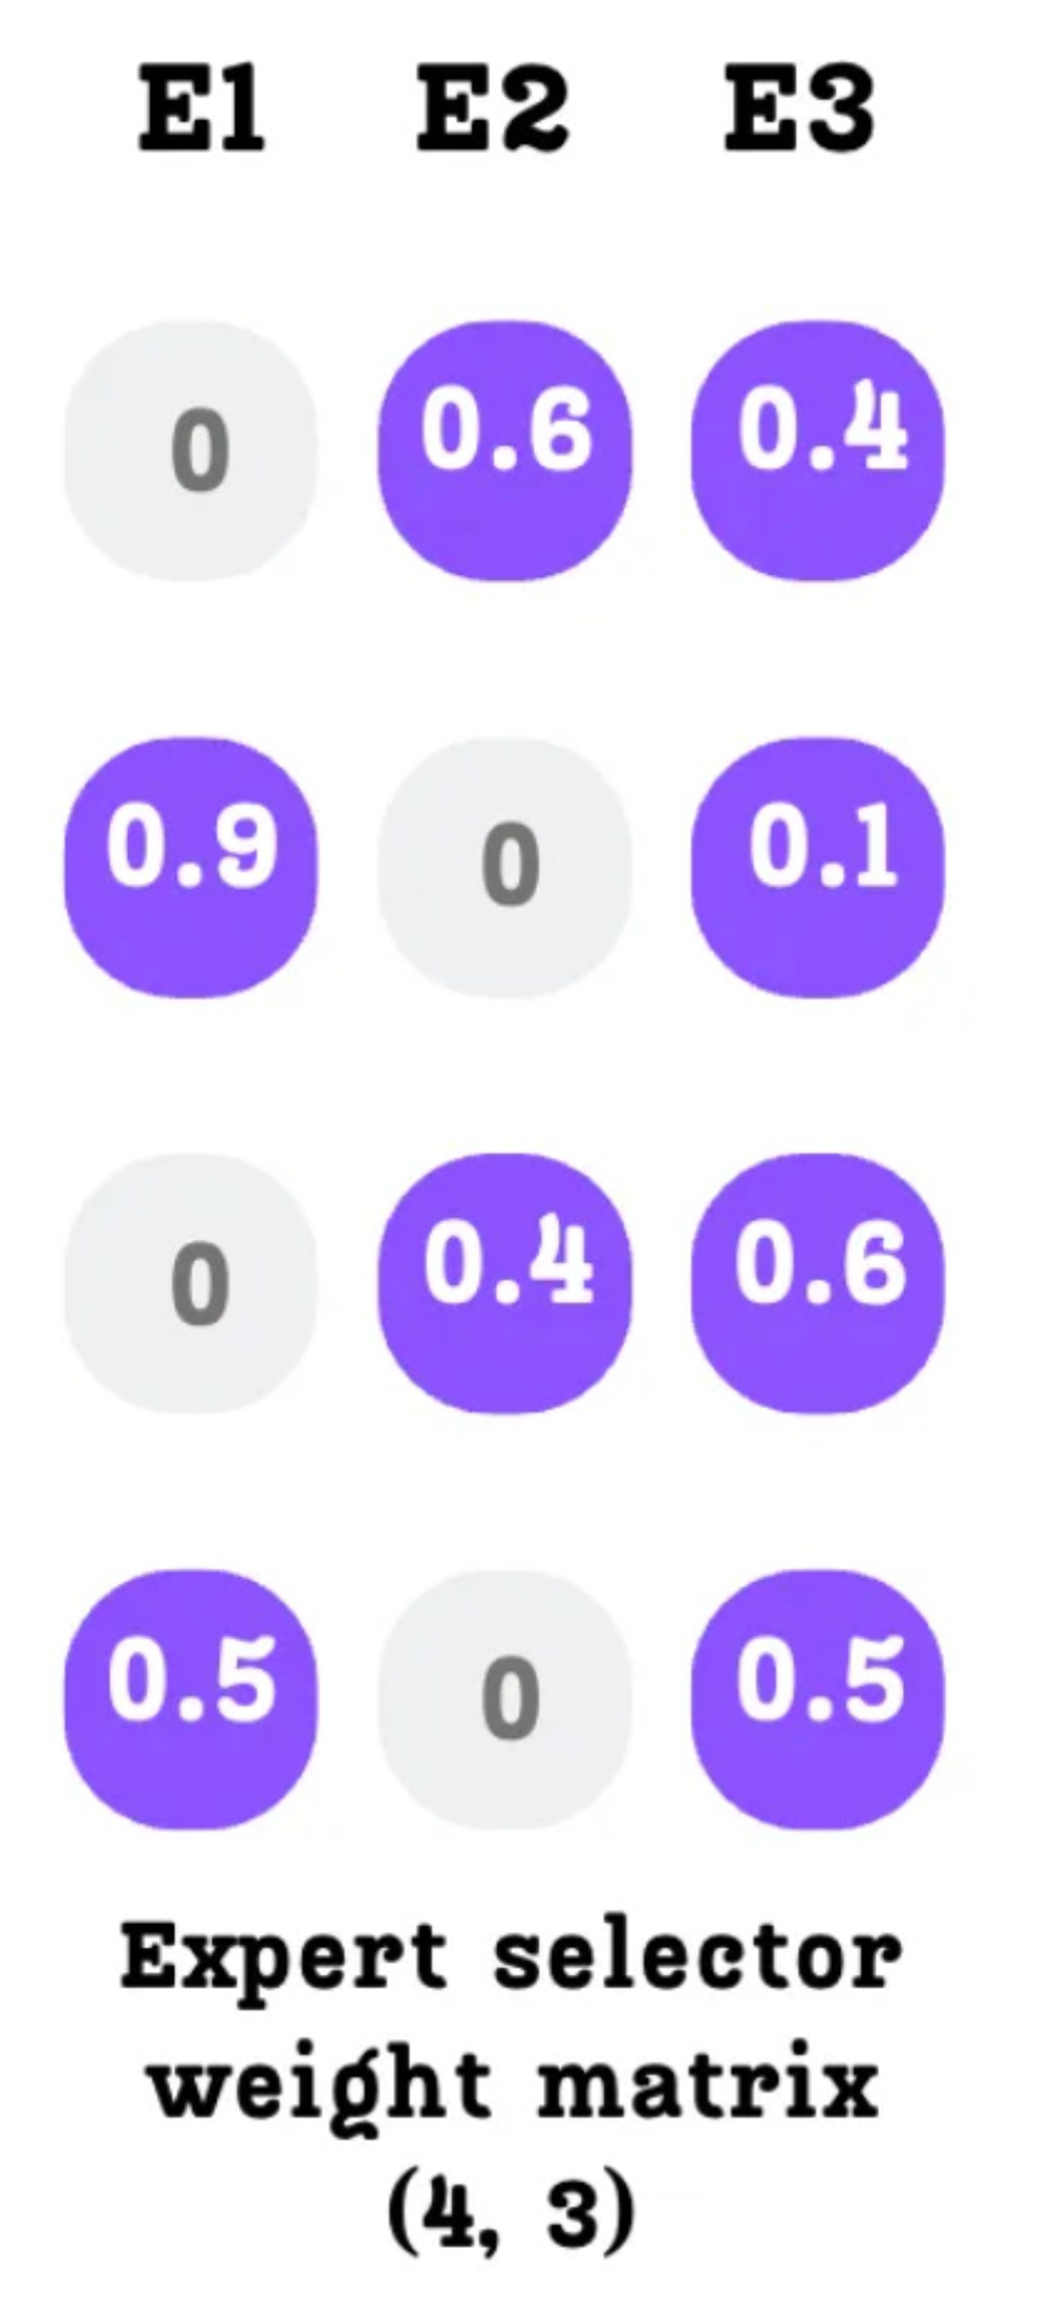
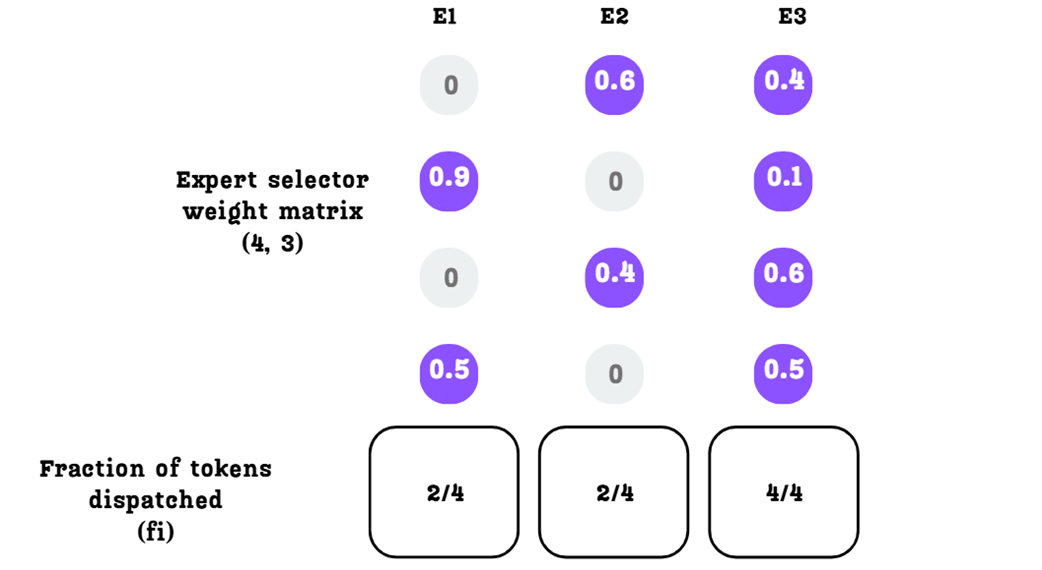
The Expert Selector Weight Matrix. Each row corresponds to a token, and each column corresponds to an expert.
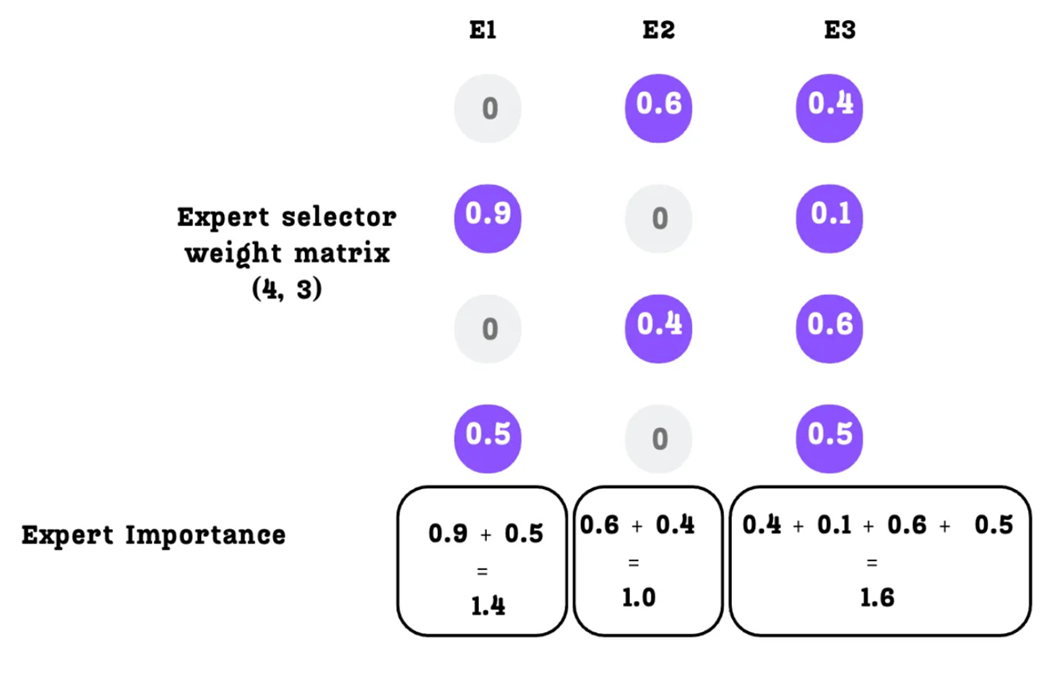
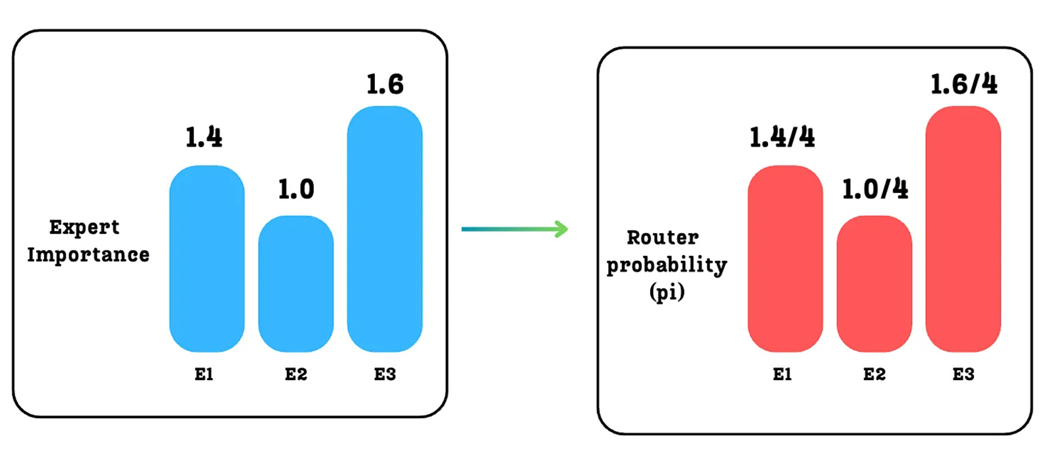
Calculating Expert Importance by summing the probabilities down each column.
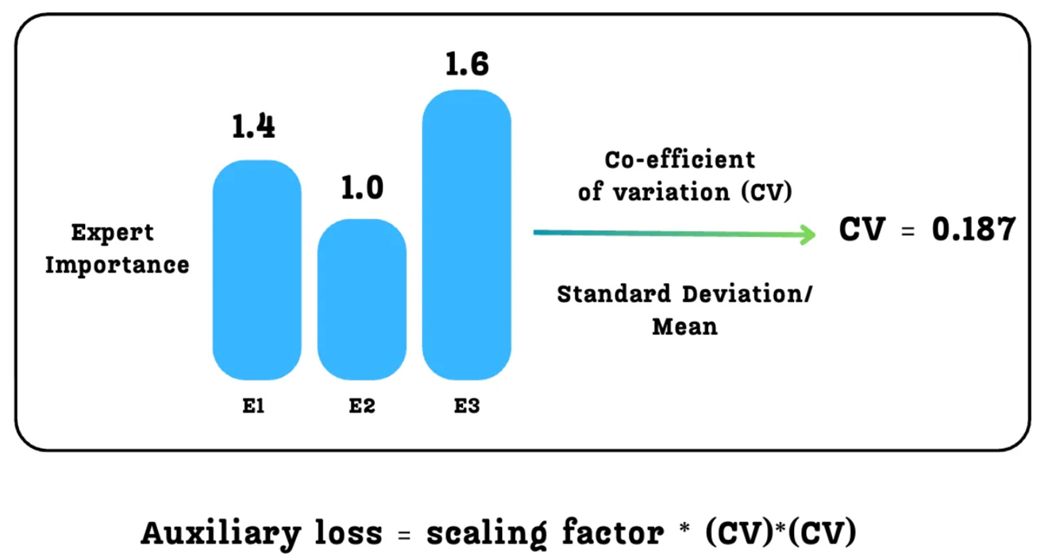
The Auxiliary Loss is calculated from the Coefficient of Variation of the Expert Importance scores.
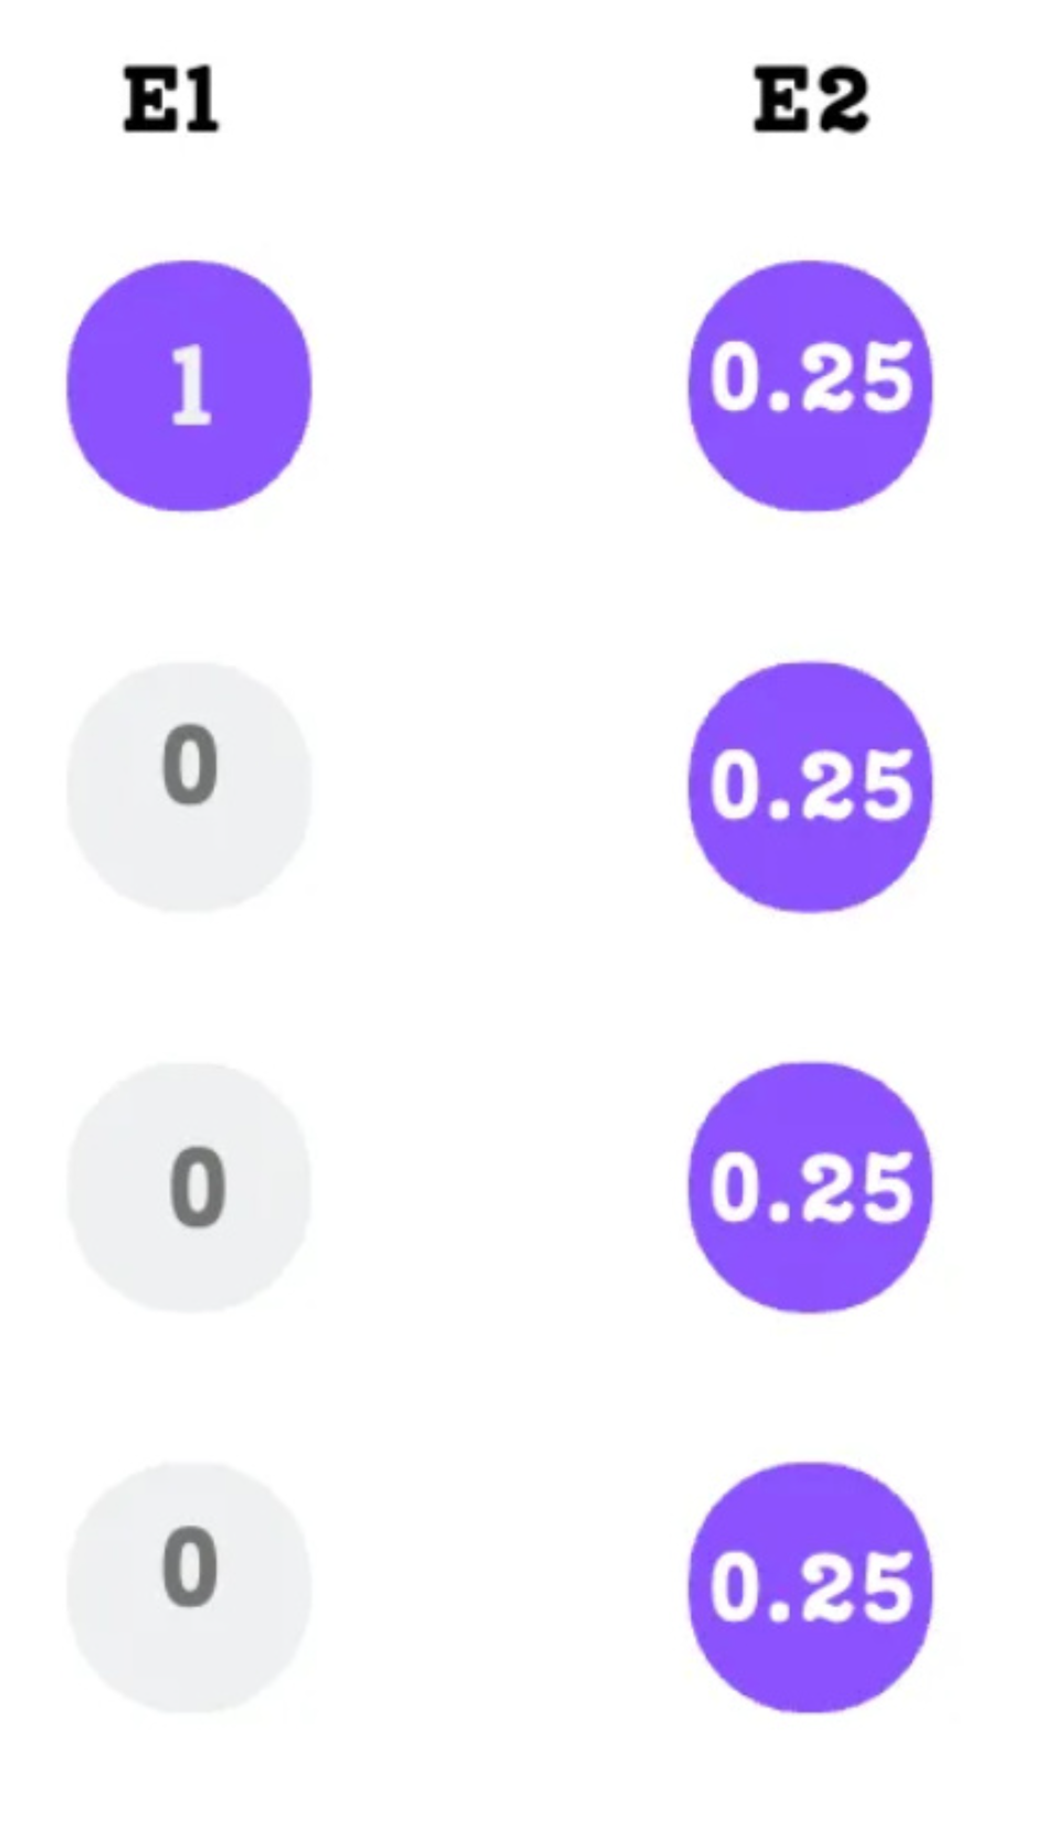
An example demonstrating that equal expert importance does not guarantee a balanced token load.
Calculating the Router Probability (pi) for each expert.
Calculating the Fraction of Tokens Dispatched (fi) for each expert.
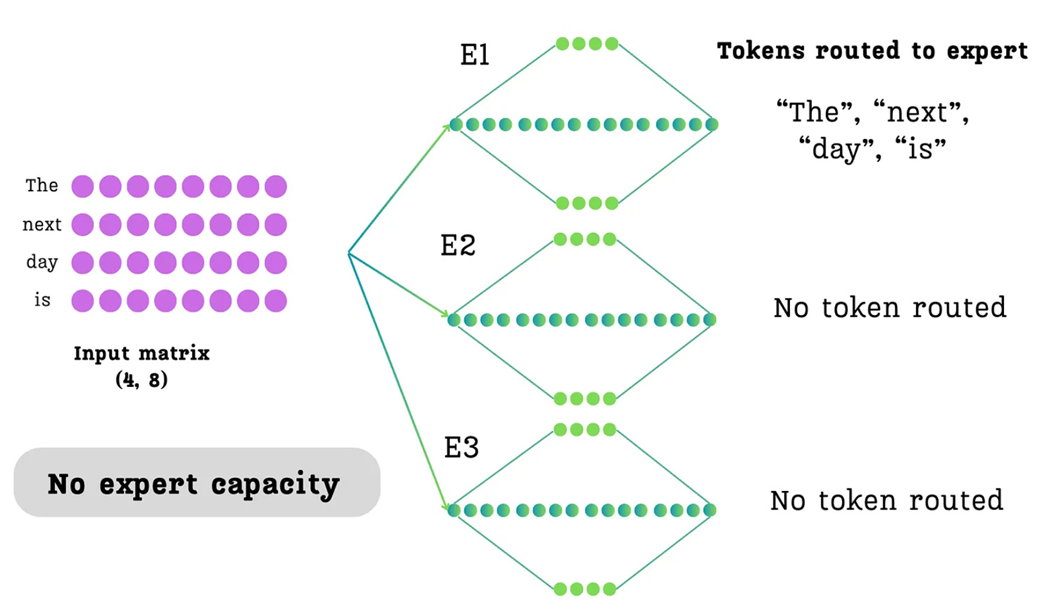
An illustration of imbalanced routing without an expert capacity. In this scenario, the router has sent all tokens in the batch to Expert 1, leaving the other experts idle. This overloading of a single expert is the problem that expert capacity is designed to prevent.
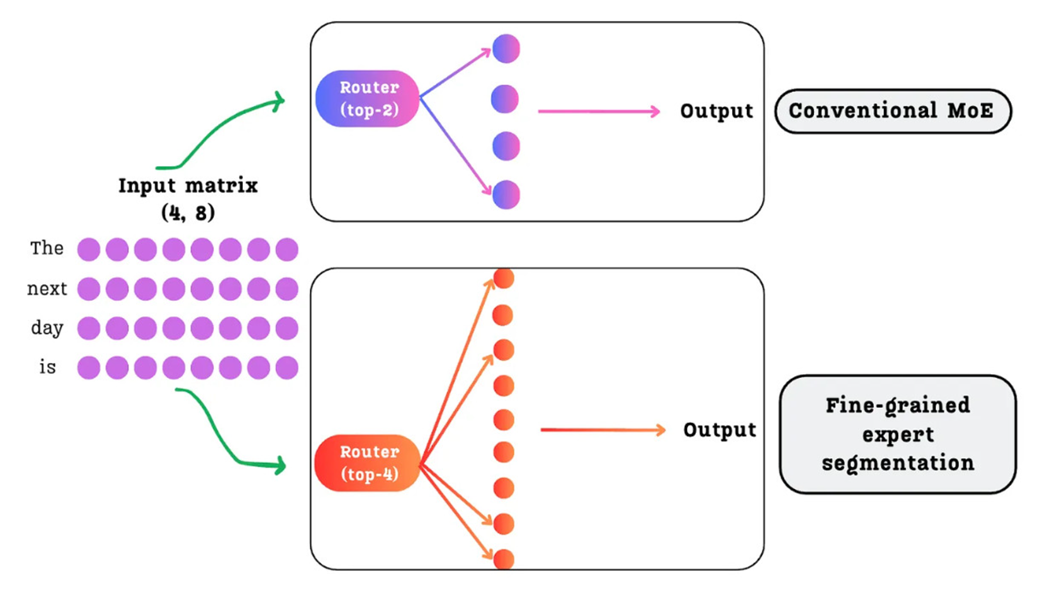
A comparison between a conventional MoE with a few large experts (top) and DeepSeek's fine-grained approach with many smaller experts (bottom).
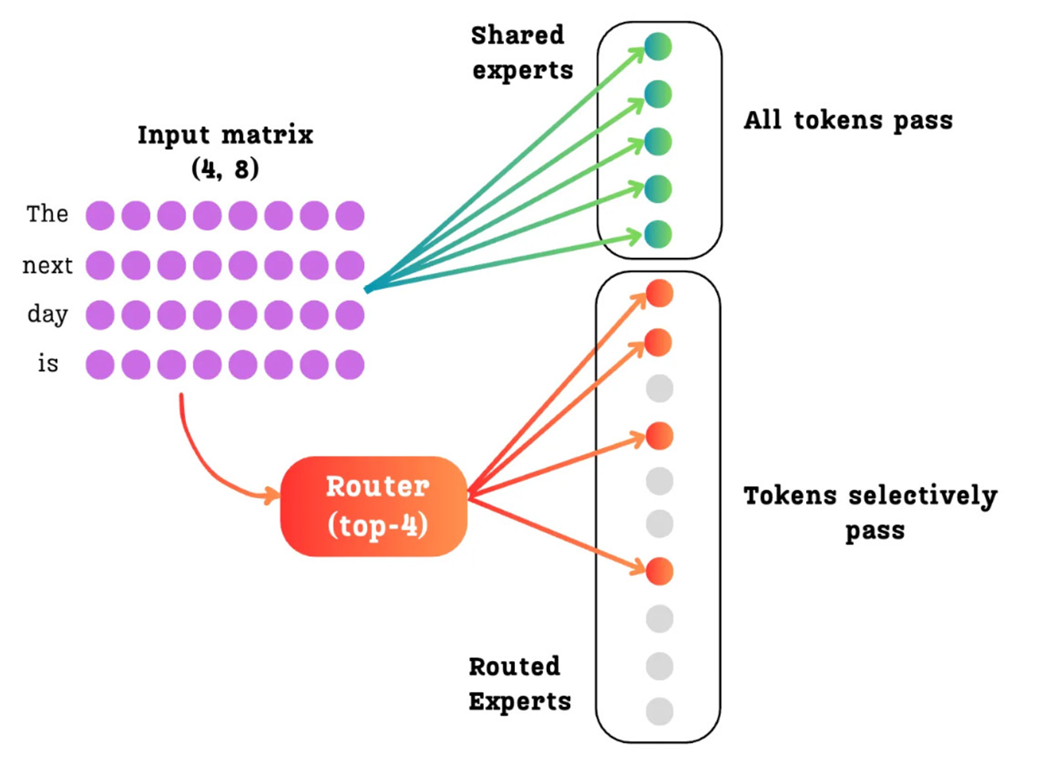
The DeepSeekMoE architecture with Shared and Routed Experts. All tokens are processed by the dense Shared Experts, while the router selectively sends each token to a sparse subset of the Routed Experts.
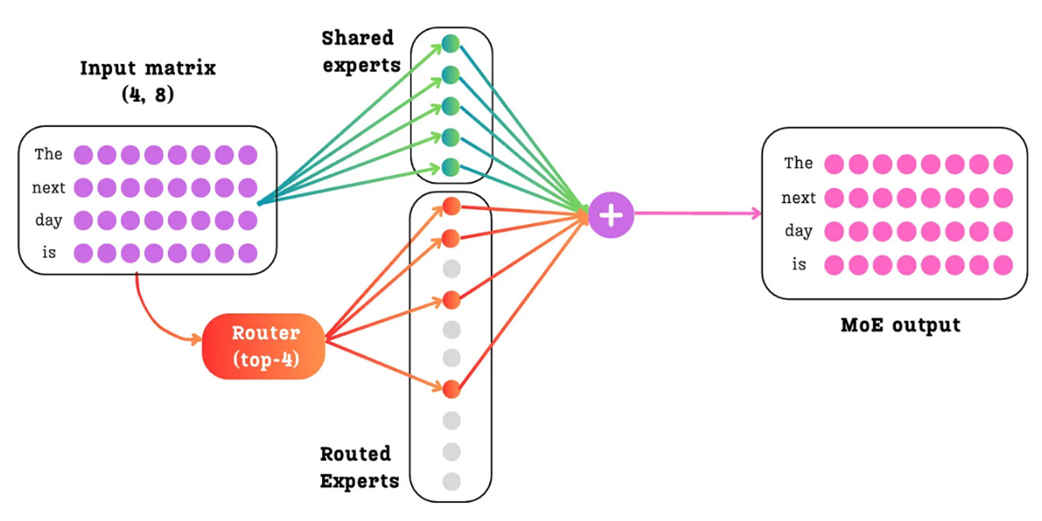
The final output of the DeepSeekMoE layer is the sum of the outputs from the dense shared experts and the sparse routed experts.
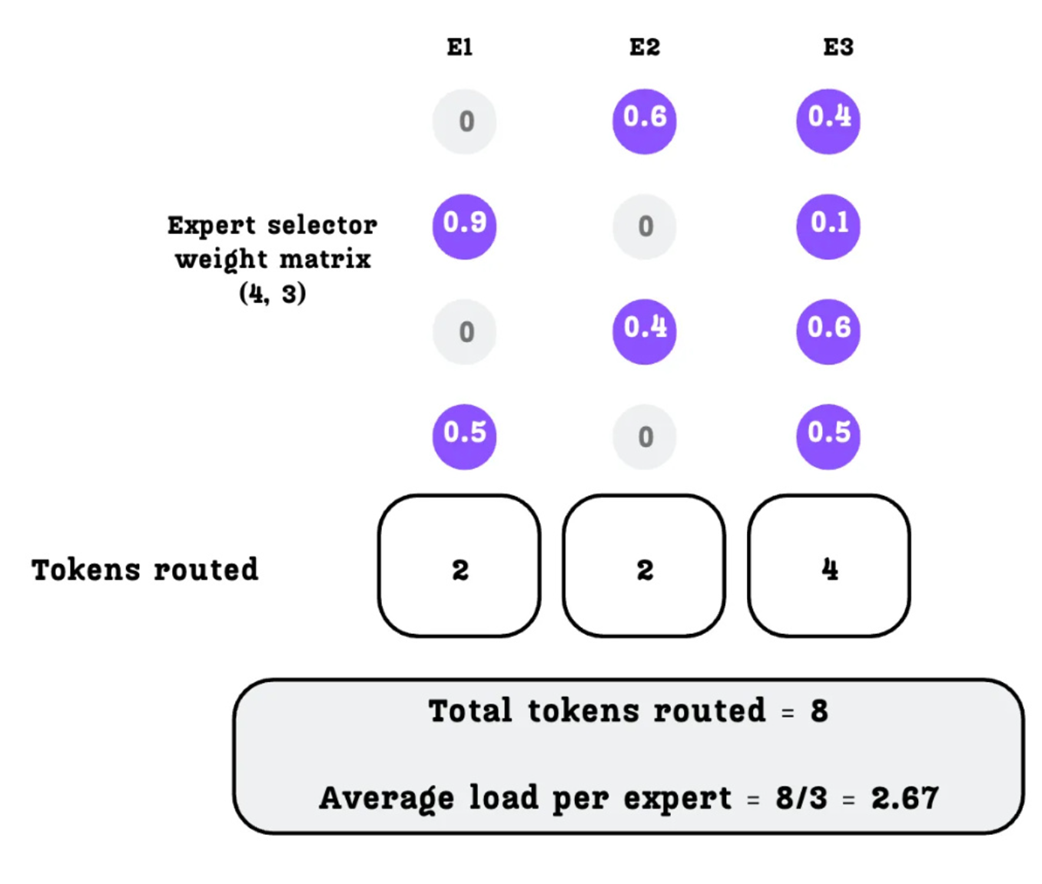
Calculating the number of tokens routed to each expert based on the top-k selection.
Calculating the load violation for each expert.
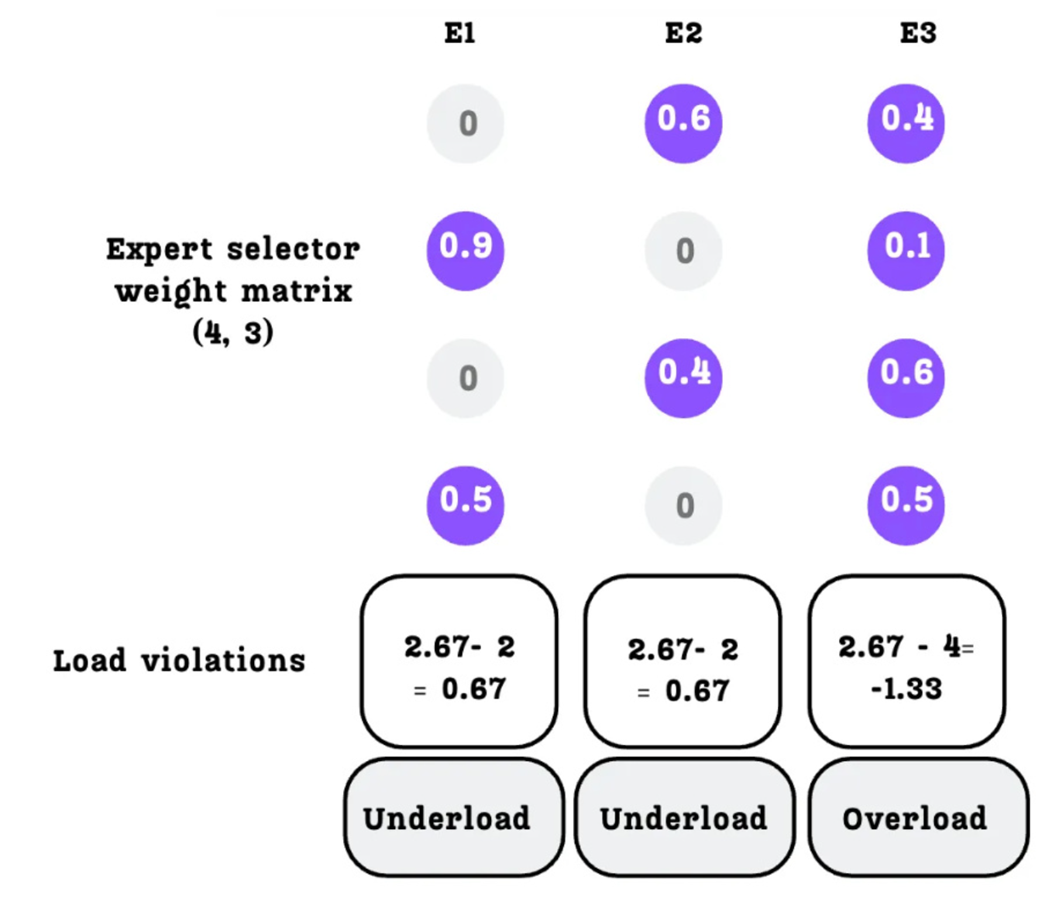
The direction of the bias update based on the expert's load status.
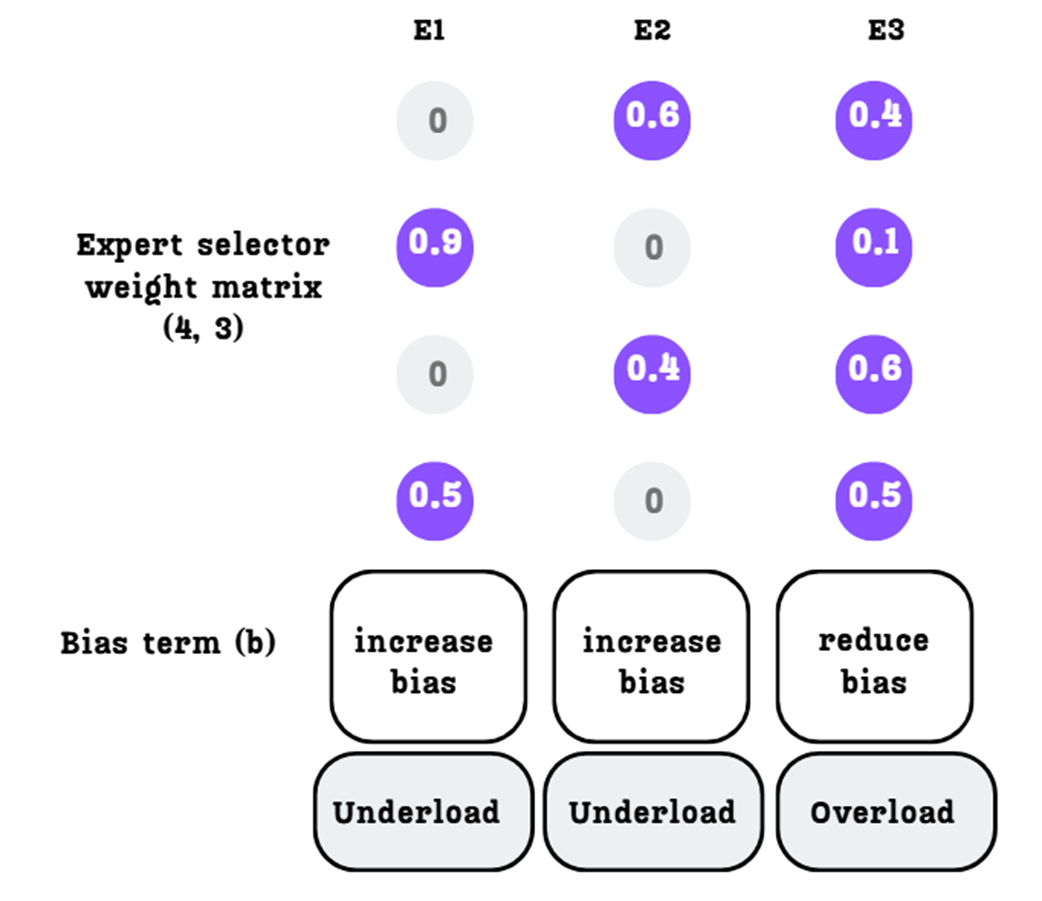
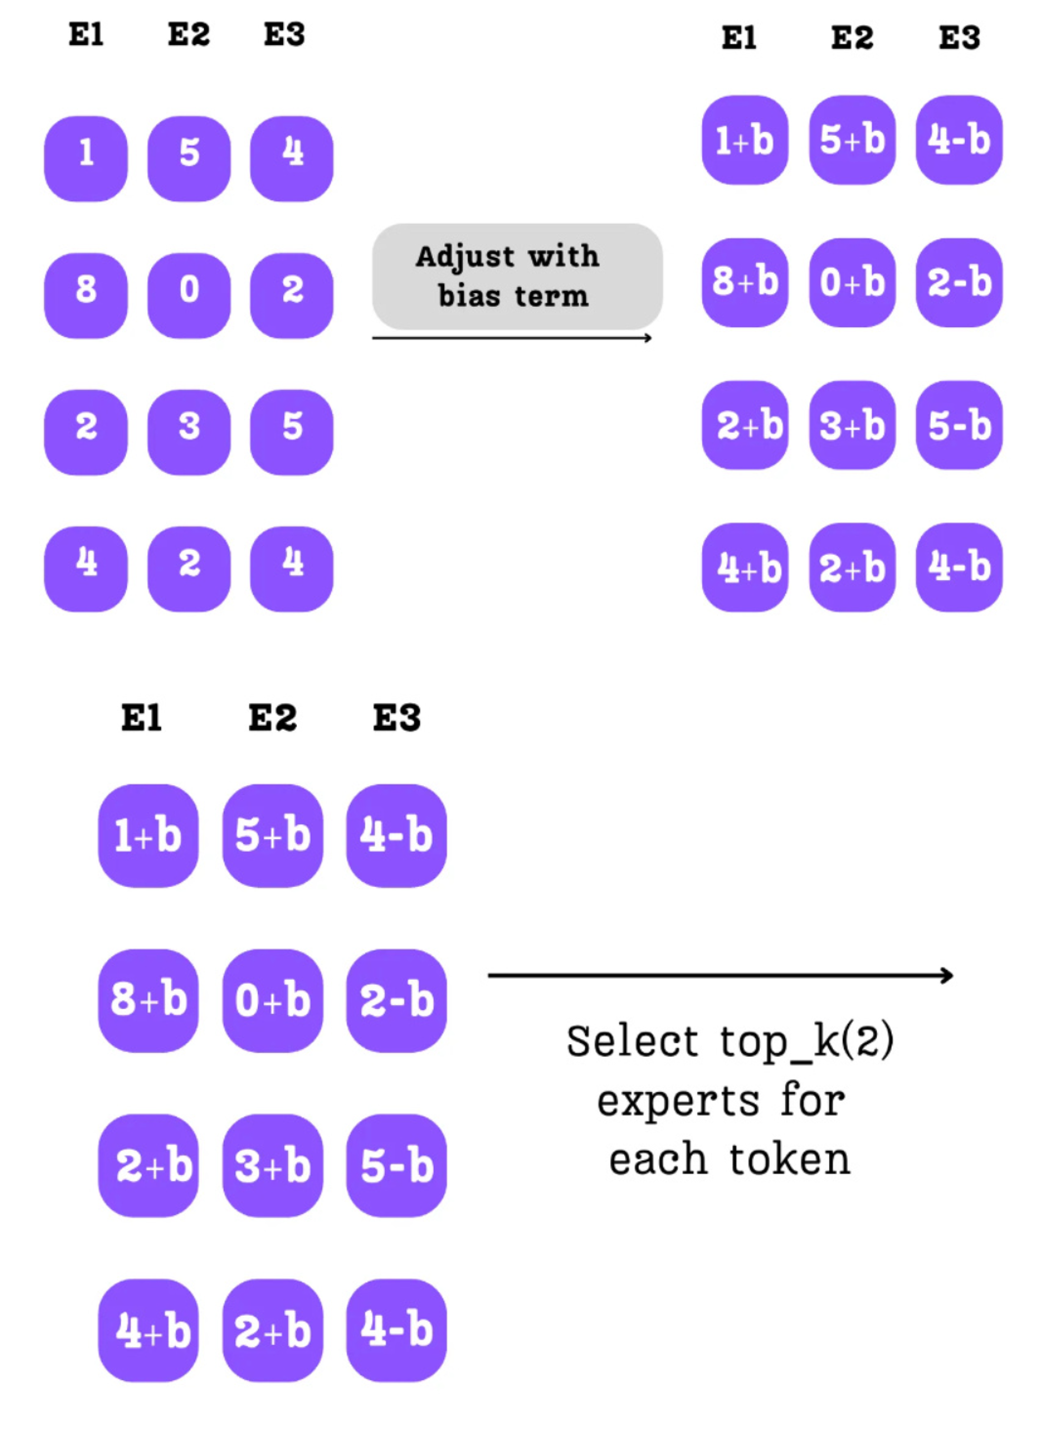
The bias term is added to the raw router logits before the top-k selection process.
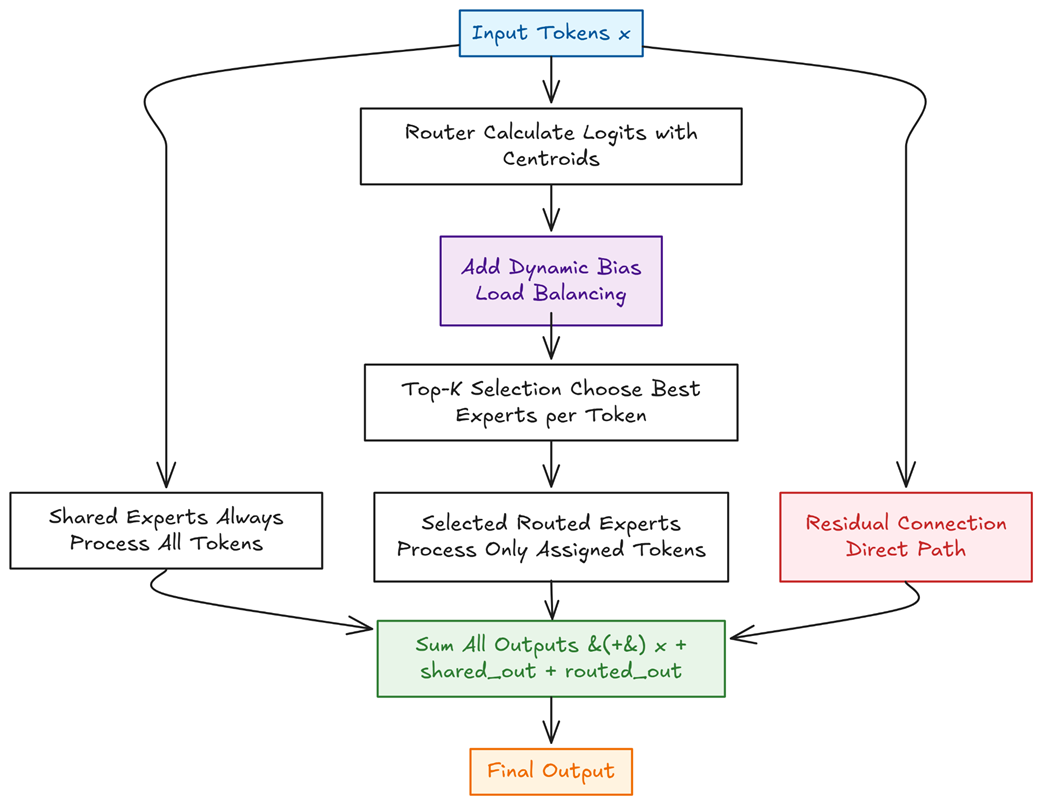
The complete forward pass of the DeepSeekMoE module, showing the three parallel data paths: the dense shared expert path, the sparse routed expert path with dynamic load balancing, and the residual connection.
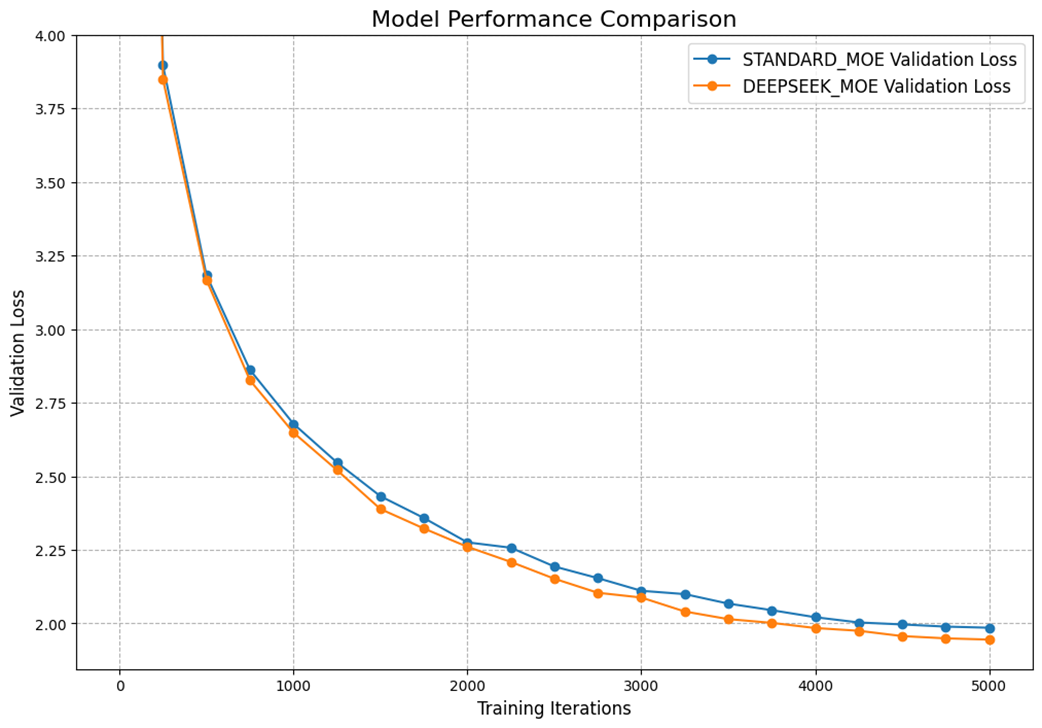
A comparison of the validation loss curves for the Standard MoE and DeepSeek-MoE models. Despite having a similar number of parameters, the DeepSeek-MoE architecture consistently achieves a lower loss, indicating superior learning. Both models were trained for 5,000 iterations.
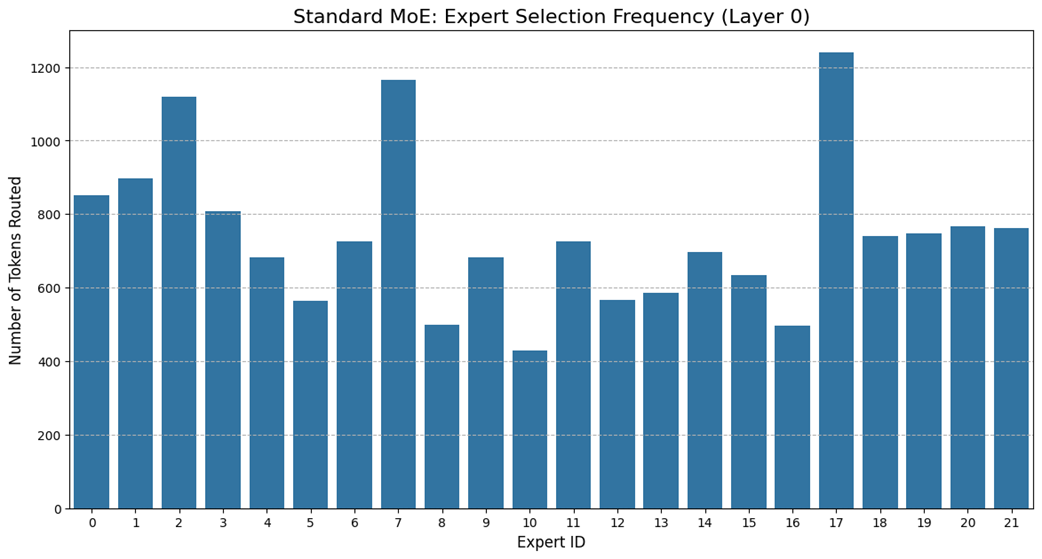
Expert selection frequency for the Standard-MoE model in a sample batch. The uneven distribution highlights the problem of imbalanced routing.
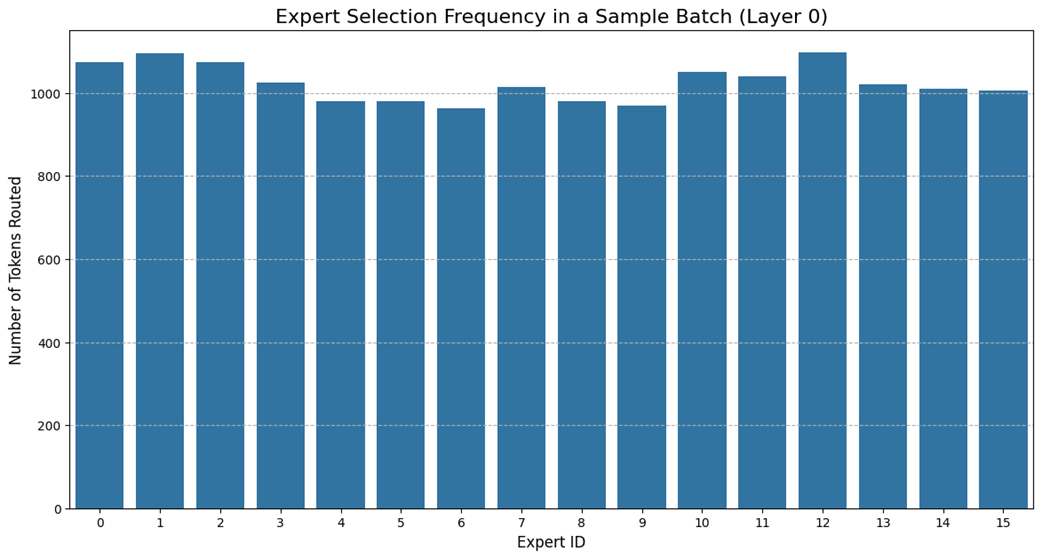
Expert selection frequency for the DeepSeek-MoE model in a sample batch. The distribution is remarkably uniform, demonstrating the effectiveness of the dynamic bias mechanism.
Summary
- Dense Feed-Forward Networks (FFNs) in standard Transformers are computationally expensive, as all of their parameters are activated for every single token, creating a bottleneck for both training and inference.
- Mixture of Experts (MoE) replaces the single, dense FFN with a committee of smaller, specialized "expert" networks.
- The efficiency of MoE comes from sparsity: for any given token, a routing mechanism activates only a small subset of the total experts (e.g., the top 2), leaving the rest dormant and their computations unperformed.
- During pre-training, experts learn to specialize in handling specific types of information (e.g., punctuation, verbs, or Python code), which is why activating only a few is effective.
- The routing mechanism is a small, learnable linear layer that generates scores for each expert. A top-k selection identifies the most relevant experts, and a softmax function converts their scores into weights for combining their outputs.
- Imbalanced routing, where some experts are over-utilized and others are ignored, leads to inefficient learning and performance degradation.
- Traditional MoE models use an Auxiliary Loss term to penalize imbalance, but this can interfere with the primary training objective of learning the language.
- DeepSeek's first innovation, Fine-Grained Expert Segmentation, uses a massive number of smaller experts to solve the problem of Knowledge Hybridity, allowing for deeper specialization.
- DeepSeek's second innovation, Shared Expert Isolation, uses a small set of dense "generalist" experts to learn common knowledge, solving the problem of Knowledge Redundancy and freeing up the routed "specialist" experts.
- DeepSeek's third innovation, Auxiliary-Loss-Free Load Balancing, dynamically adjusts router scores with a bias term, enforcing balance without interfering with the main training loss and resolving the core trade-off of traditional balancing methods.
FAQ
What is Mixture-of-Experts (MoE) in a Transformer model?
MoE is a replacement for the standard dense FFN in a Transformer block. Instead of using one large feed-forward network for every token, the model uses multiple smaller expert networks and routes each token to only a few of them.
Why does sparsity make MoE more efficient than a dense FFN?
Sparsity means only a small subset of experts is activated for each token. This lets the model keep a very large total number of parameters while paying the computation cost of only a few experts per token.
What problem in standard Transformers does MoE address?
Standard Transformer FFNs are dense, so every token activates all parameters in the layer. This creates high training cost and high inference latency, especially as the model grows larger.
What is expert specialization in MoE?
Expert specialization is the idea that different experts learn different kinds of patterns during training. Because each token is routed only to a few experts, those experts can become highly specialized in handling certain token types or behaviors.
How does the router decide which experts to activate?
The router is a small learnable neural network, usually implemented as a linear layer. It produces a score for each expert for each token, and the highest-scoring experts are selected for processing.
What does top-k selection mean in MoE?
Top-k selection means that for each token, only the k experts with the highest router scores are kept. All other experts are masked out, so only a limited subset contributes to the final output.
Why are negative infinity values used before softmax?
Non-selected expert scores are replaced with negative infinity so that after softmax their probabilities become zero. This cleanly removes them from the final expert weighting.
What is the difference between expert importance and expert load?
Expert importance is the sum of routing probabilities assigned to an expert across a batch. Expert load is the actual number of tokens routed to that expert. These are related but not identical, which is why balancing can be tricky.
Why did DeepSeek introduce shared experts in its MoE design?
Shared experts handle common, general-purpose knowledge for every token, while routed experts focus on narrow specialization. This reduces knowledge redundancy by avoiding the need for every routed expert to relearn the same basic information.
How does DeepSeek’s auxiliary-loss-free load balancing work?
Instead of adding an extra balancing loss, DeepSeek updates a bias term for each expert after each training step. Underloaded experts get their bias increased and overloaded experts get their bias decreased, which nudges future routing decisions toward a more even load.

 Build a DeepSeek Model (From Scratch) ebook for free