6 Tabular Reinforcement Learning
The chapter presents tabular reinforcement learning as the practical bridge between temporal-difference theory and usable control algorithms. It explains that TD learning is foundational because it lets agents improve from experience without waiting for complete outcomes, using prediction error to update value estimates online. The discussion connects this idea to policy evaluation and improvement, shows why model-free learning is necessary in real settings, and introduces the core distinction between on-policy and off-policy methods as the basis for how agents learn from and act in uncertain environments.
To make the ideas concrete, the chapter develops a restaurant table-scheduling example where an agent must decide whether to take a guaranteed small reward or wait for a larger but uncertain one. This example is used to derive and validate TD updates, showing that repeated sampling can converge toward analytically optimal values even when transition probabilities are unknown. It then extends the same logic to action values with tabular Q-functions, emphasizing that tabular methods store one value per state or state-action pair and are therefore easy to interpret, update, and use for direct decision-making.
The later sections focus on the main tabular control algorithms: SARSA, Q-learning, and eligibility traces. SARSA learns on-policy from the action it actually takes, making it conservative and often safer under exploration risk, while Q-learning learns off-policy from the best possible next action and tends to be more optimistic and aggressive. Eligibility traces and TD(λ) are introduced as a way to spread credit backward over multiple steps, balancing bias and variance, with SARSA(λ) and Watkins’s Q(λ) showing how traces can be combined with on-policy or off-policy learning. The chapter closes with a gas-station inventory case study that demonstrates how these methods can solve a realistic sequential decision problem, highlighting that algorithm choice affects not just reward, but stability, safety, and business fit.
Like cooking, we use feedback from error to update parameters step by step.
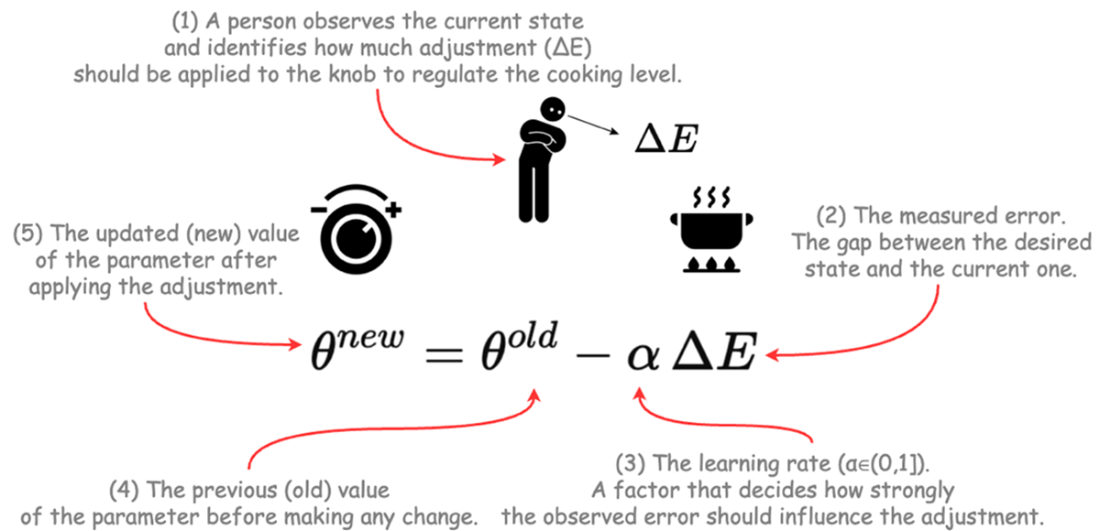
The formula shows how each update moves the old value toward a better one.
Convergence behavior of Temporal difference learning algorithm.
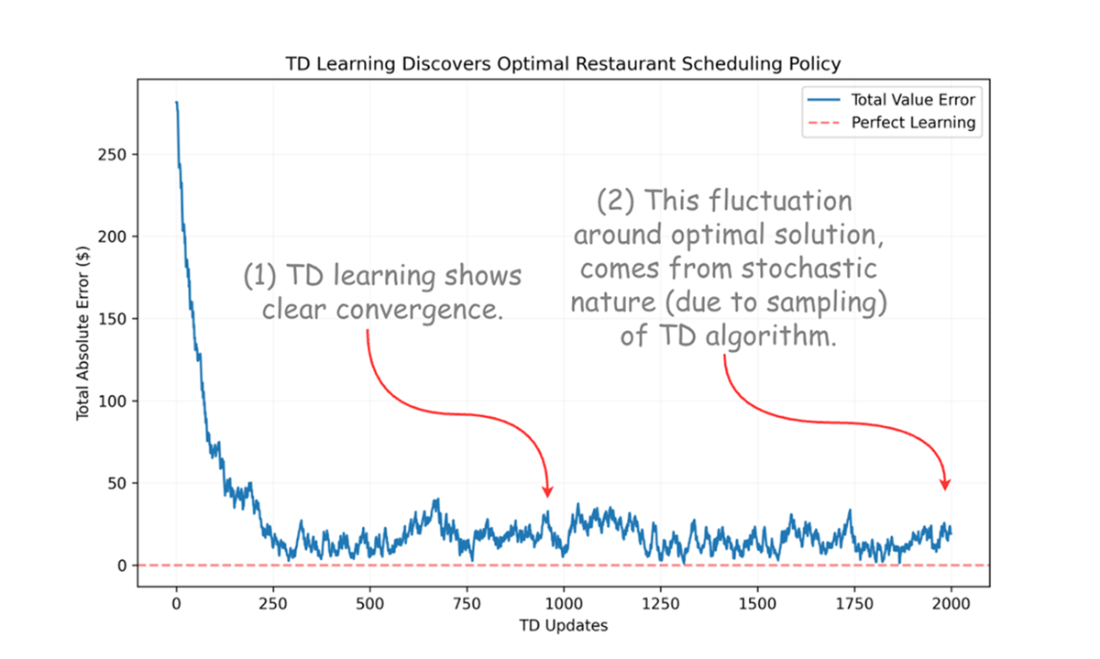
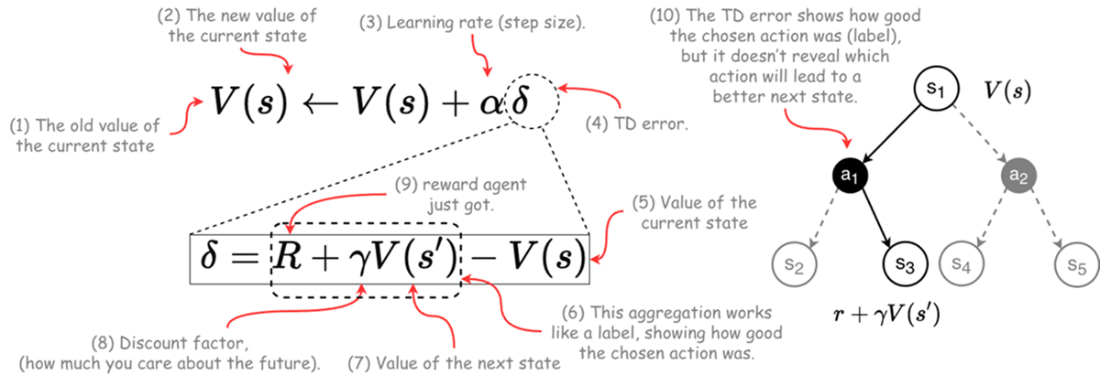
illustration of problem of aligning within the TD framework
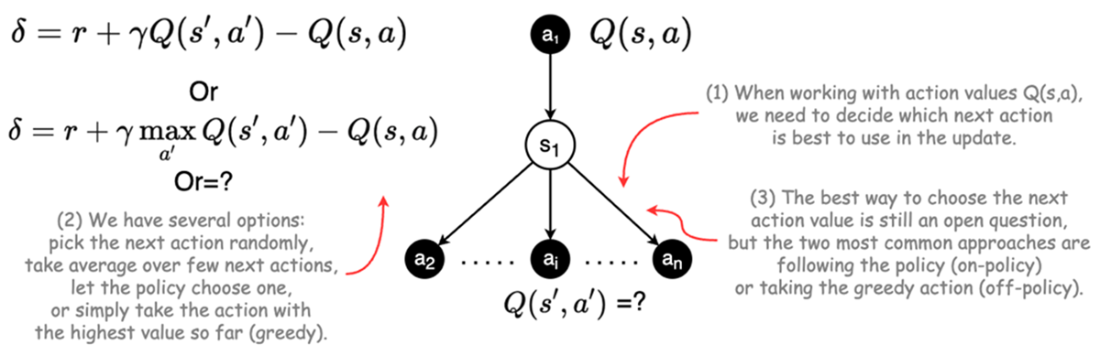
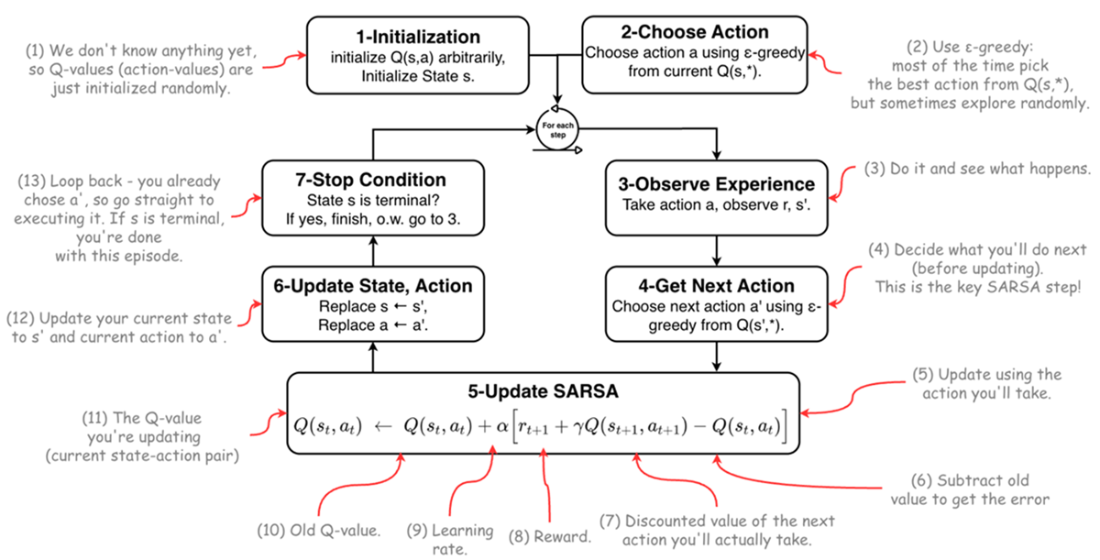
SARSA Algorithm Flowchart.
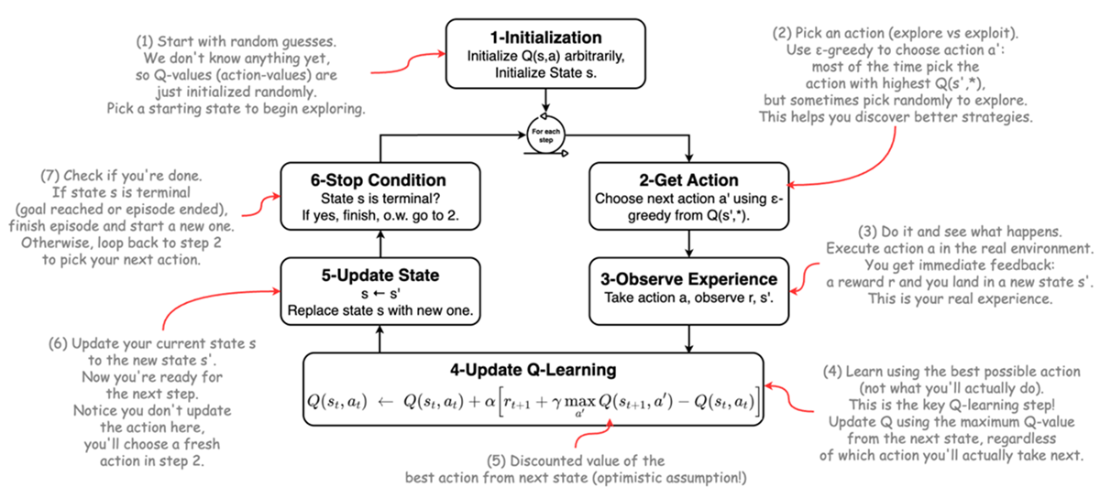
Q-learning Algorithm Flowchart.
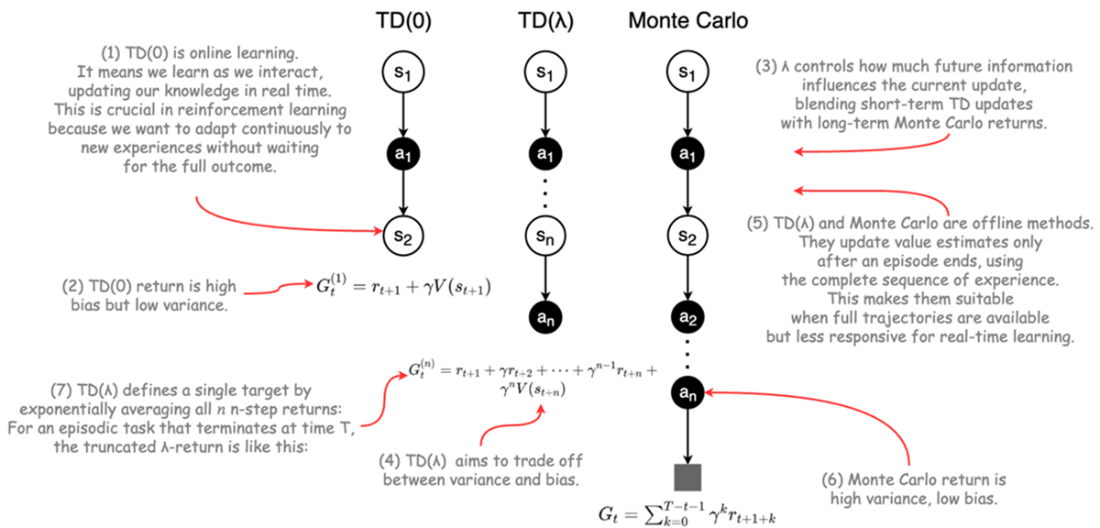
Comparison of TD(0), Monte Carlo and TD(λ) methods.
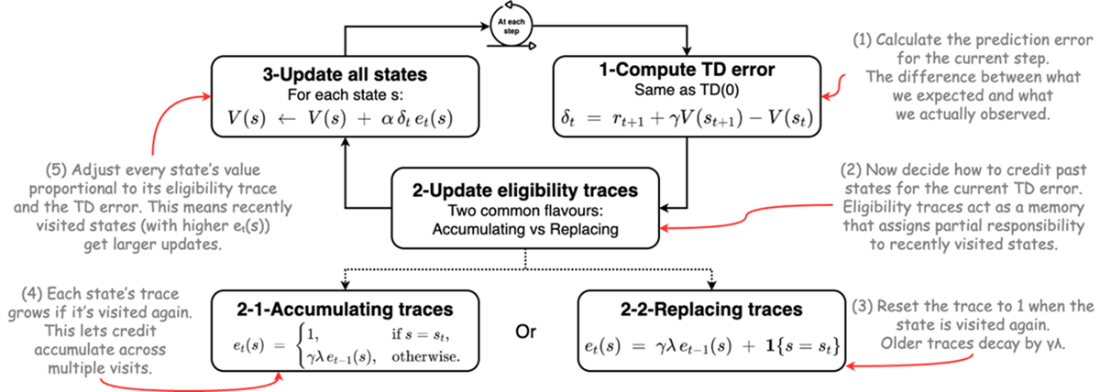
Update mechanism of temporal difference learning with eligibility traces.
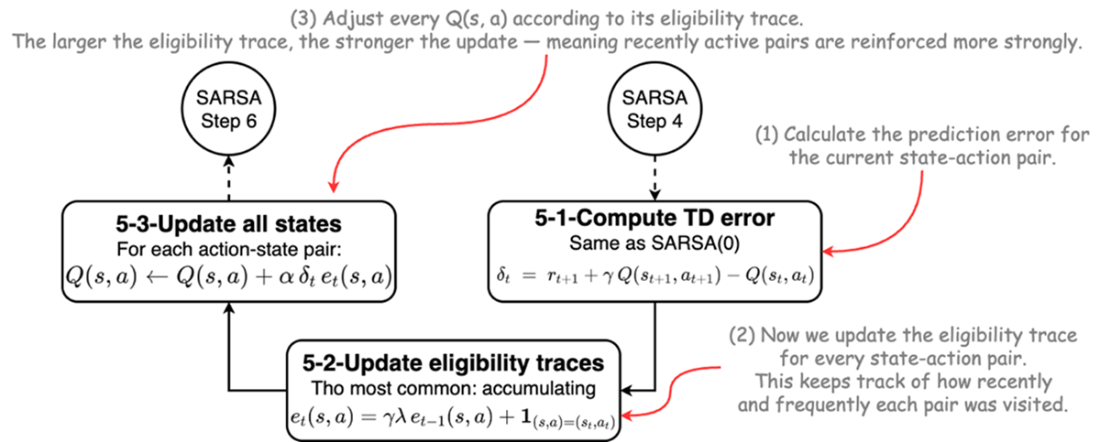
integrating eligibility trace in SARSA framework: SARSA(λ).
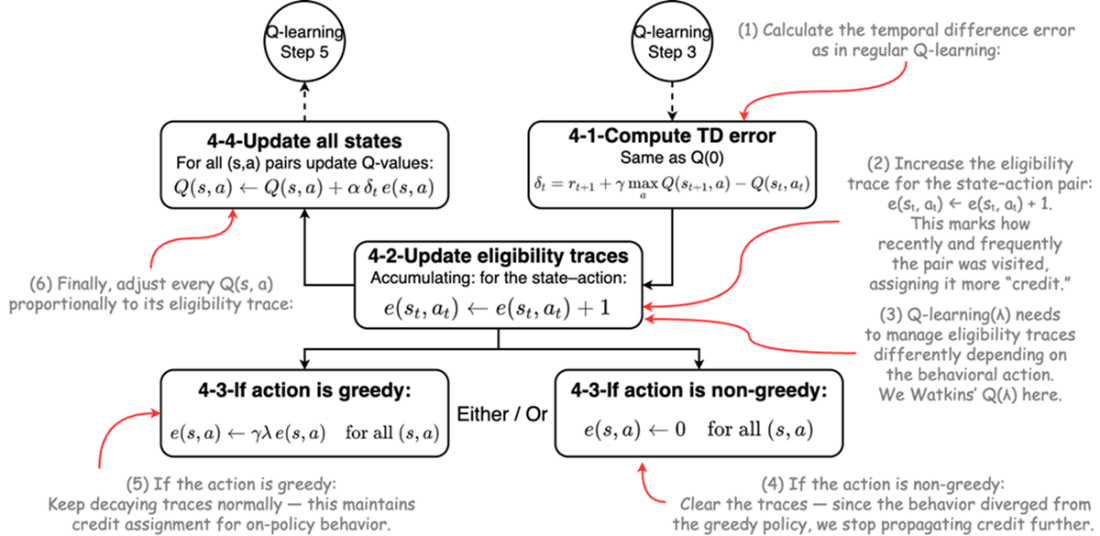
Integrating eligibility traces with Q-learning using Watkins's Q(λ) method.
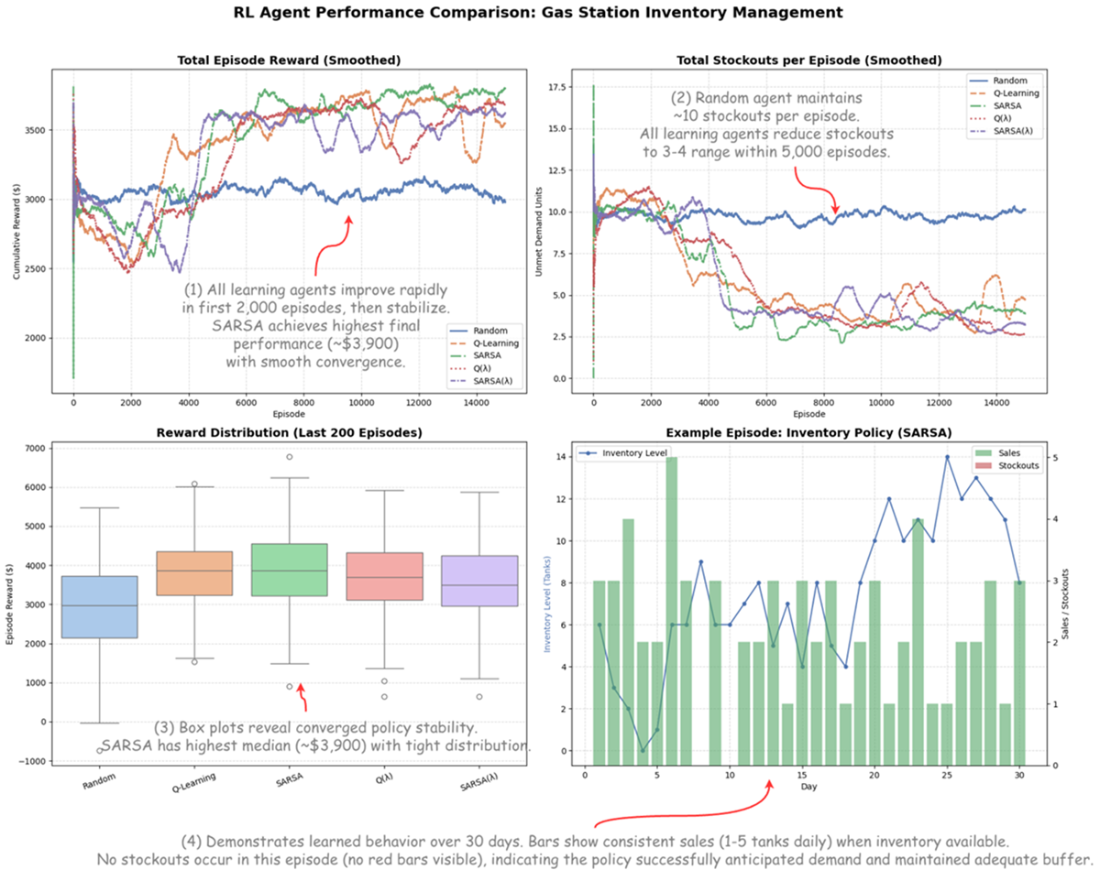
Tabular Reinforcement Learning Curves and Performance Analysis.
Summary
- In model-based learning, the agent has access to the full dynamics of the environment—the transition probabilities P(s'|s,a) and reward function R(s,a). Dynamic Programming is a model-based approach.
- In model-free learning, the agent does not know these dynamics and must learn directly from experience tuples (s, a, r, s') gathered through trial and error. Temporal difference learning, Q-learning, and SARSA are all model-free.
- In offline learning, the agent is trained on a fixed, pre-collected batch of data and does not learn during interaction.
- In online learning, the agent updates its knowledge continuously during interaction with the environment, learning step-by-step as new experience arrives. All the temporal difference methods discussed in this chapter are online learners.
- In on-policy learning, the agent learns to improve the same policy it is using to make decisions. It learns from its own "lived experience." SARSA is on-policy.
- In off-policy learning, the agent can learn about a different policy (the target policy, typically the optimal one) than the one it is using to generate behavior (the behavior policy, typically an exploratory one). Q-learning is off-policy.
- Temporal-Difference learning is one of the two pillars of reinforcement learning, enabling agents to learn from raw experience without a model of the environment.
- The core idea of temporal difference learning is to update your predictions based on the error between your current guess and a slightly better guess one step into the future.
- This process of updating estimates using other estimates is called bootstrapping, and it allows learning to happen online, after every single step.
- The TD error (δ) is the learning signal, quantifying the "surprise" or difference between what you expected and what you observed.
- Temporal difference learning is the bridge between Dynamic Programming (which needs a full model) and Monte Carlo methods (which must wait for an episode to end).
- For an agent to make decisions in a model-free world, it must learn action values (Q(s,a)), not just state values (V(s)).
- Tabular methods represent the value function as a lookup table or spreadsheet, with a distinct entry for every state-action pair.
- Q-learning is the quintessential off-policy algorithm; it learns about the optimal greedy policy while behaving according to a different, more exploratory policy.
- Because Q-learning uses the max Q-value for its update, it is considered optimistic and often converges faster to the optimal policy.
- SARSA is the quintessential on-policy algorithm; it learns about the same policy it is using to make decisions, including all its exploratory actions.
- Because SARSA's updates use the Q-value of the actual next action taken, it is considered more realistic or conservative, learning a policy that is robust in the face of its own exploration.
- The credit assignment problem asks how to distribute credit for a reward among the many actions that may have led to it, especially when rewards are delayed.
- Eligibility traces (TD(λ)) are the solution, creating a short-term memory that allows the TD error to be propagated backward to all recently visited state-action pairs.
- The λ parameter controls how far back credit is assigned, providing a tuneable spectrum between one-step TD (λ=0) and Monte Carlo (λ=1).
- SARSA(λ) is a highly effective on-policy algorithm that combines the stability of SARSA with the learning speed of eligibility traces.
- Watkins's Q(λ) adapts traces for off-policy learning by resetting the traces to zero whenever a non-greedy (exploratory) action is taken.

 Applied Reinforcement Learning ebook for free
